Fable 5, med (Claude Code), paper
9 Jun 2026· 37% квоты pro·5h· 23 min 19 s
FancyI thought it would burn more than it did. Overall little distinguishable from Opus, in places even simpler.
I thought it would burn more than it did. Overall little distinguishable from Opus, in places even simpler.
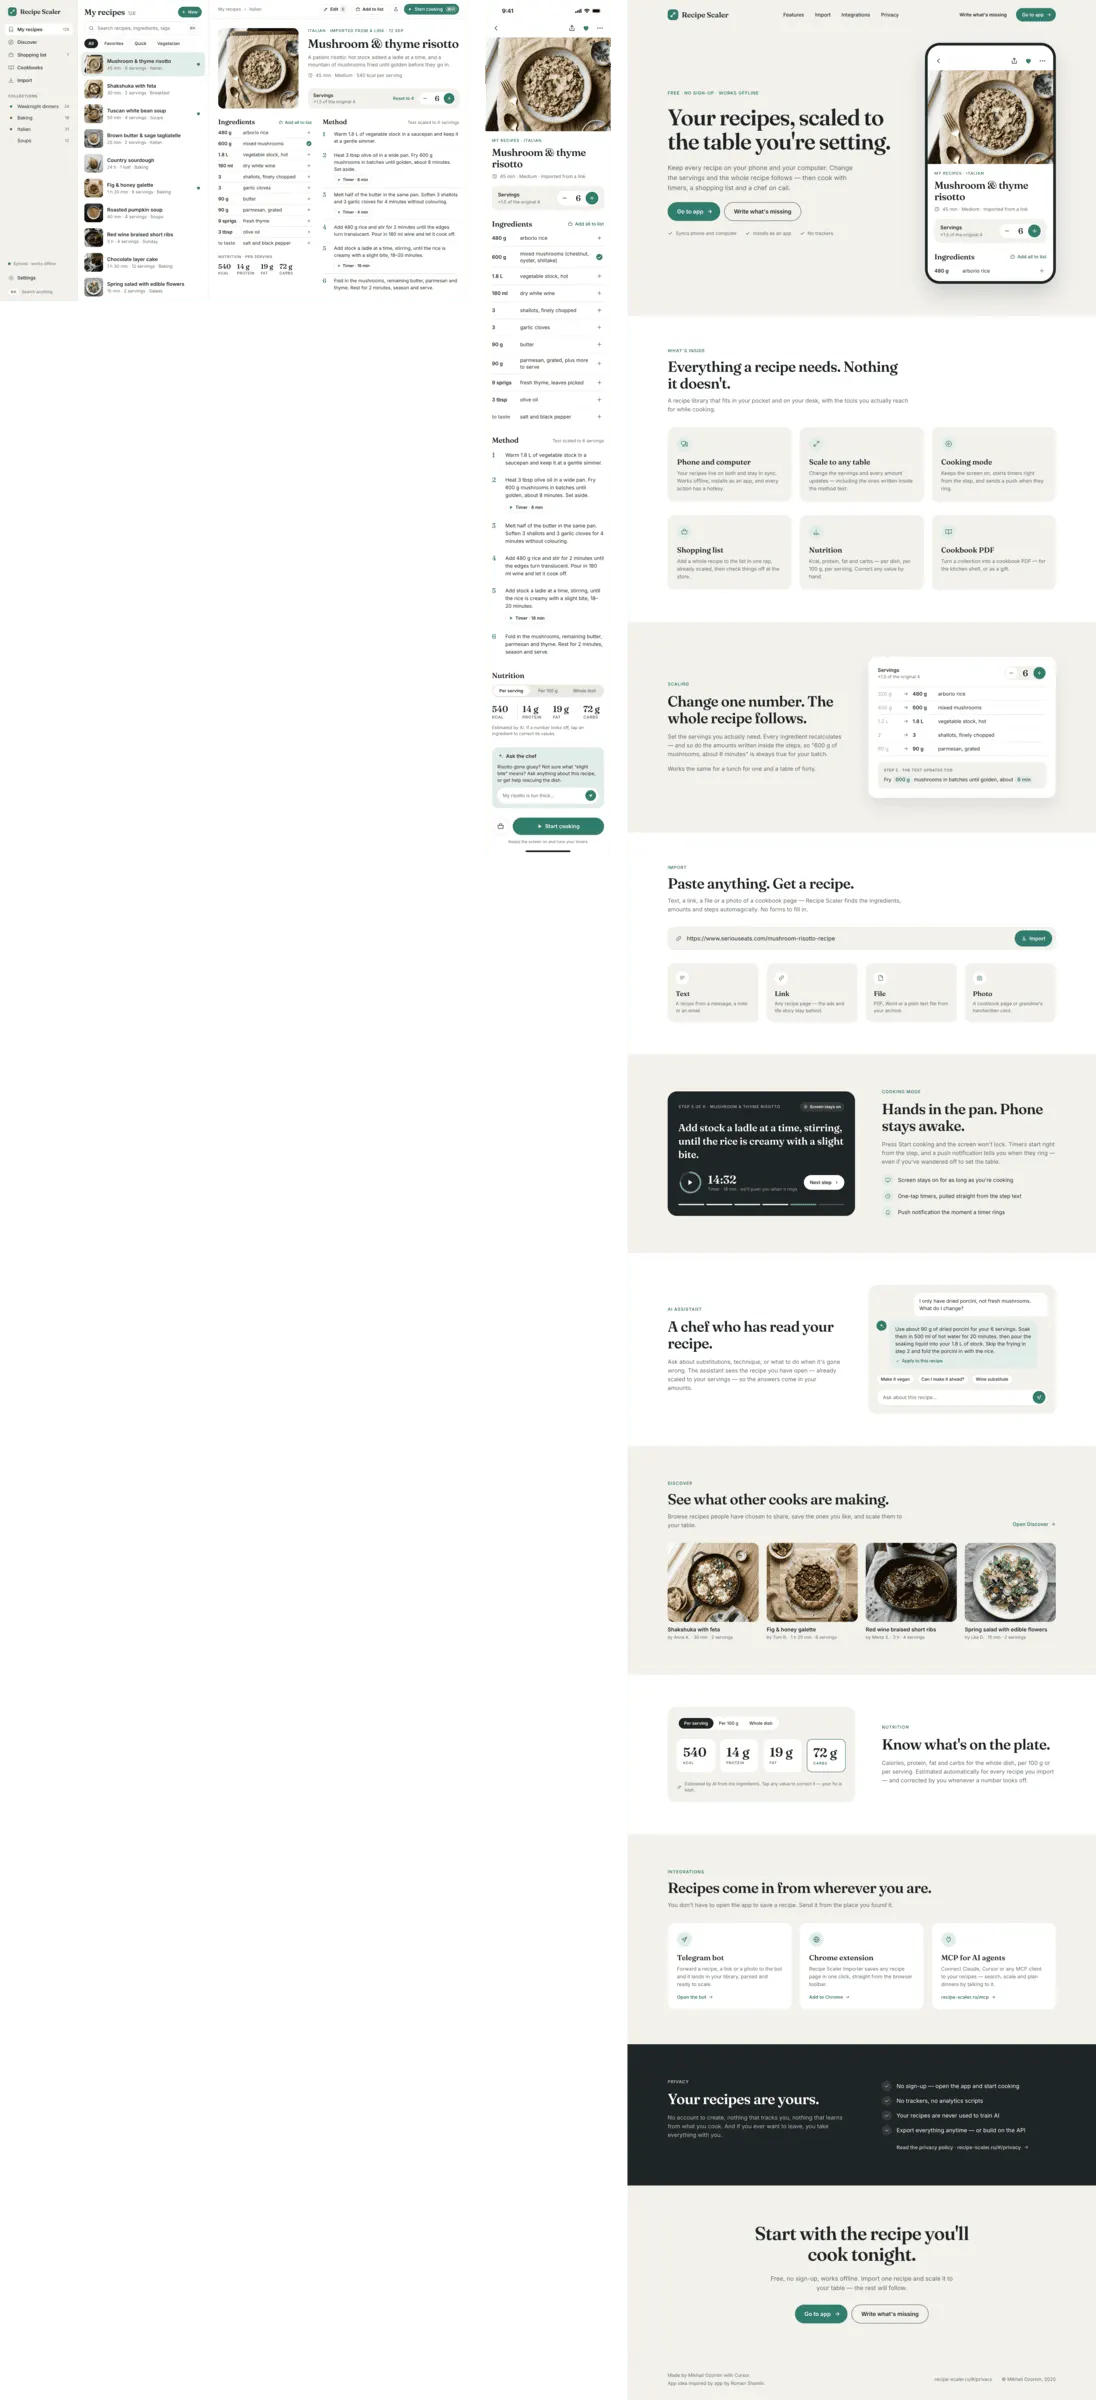
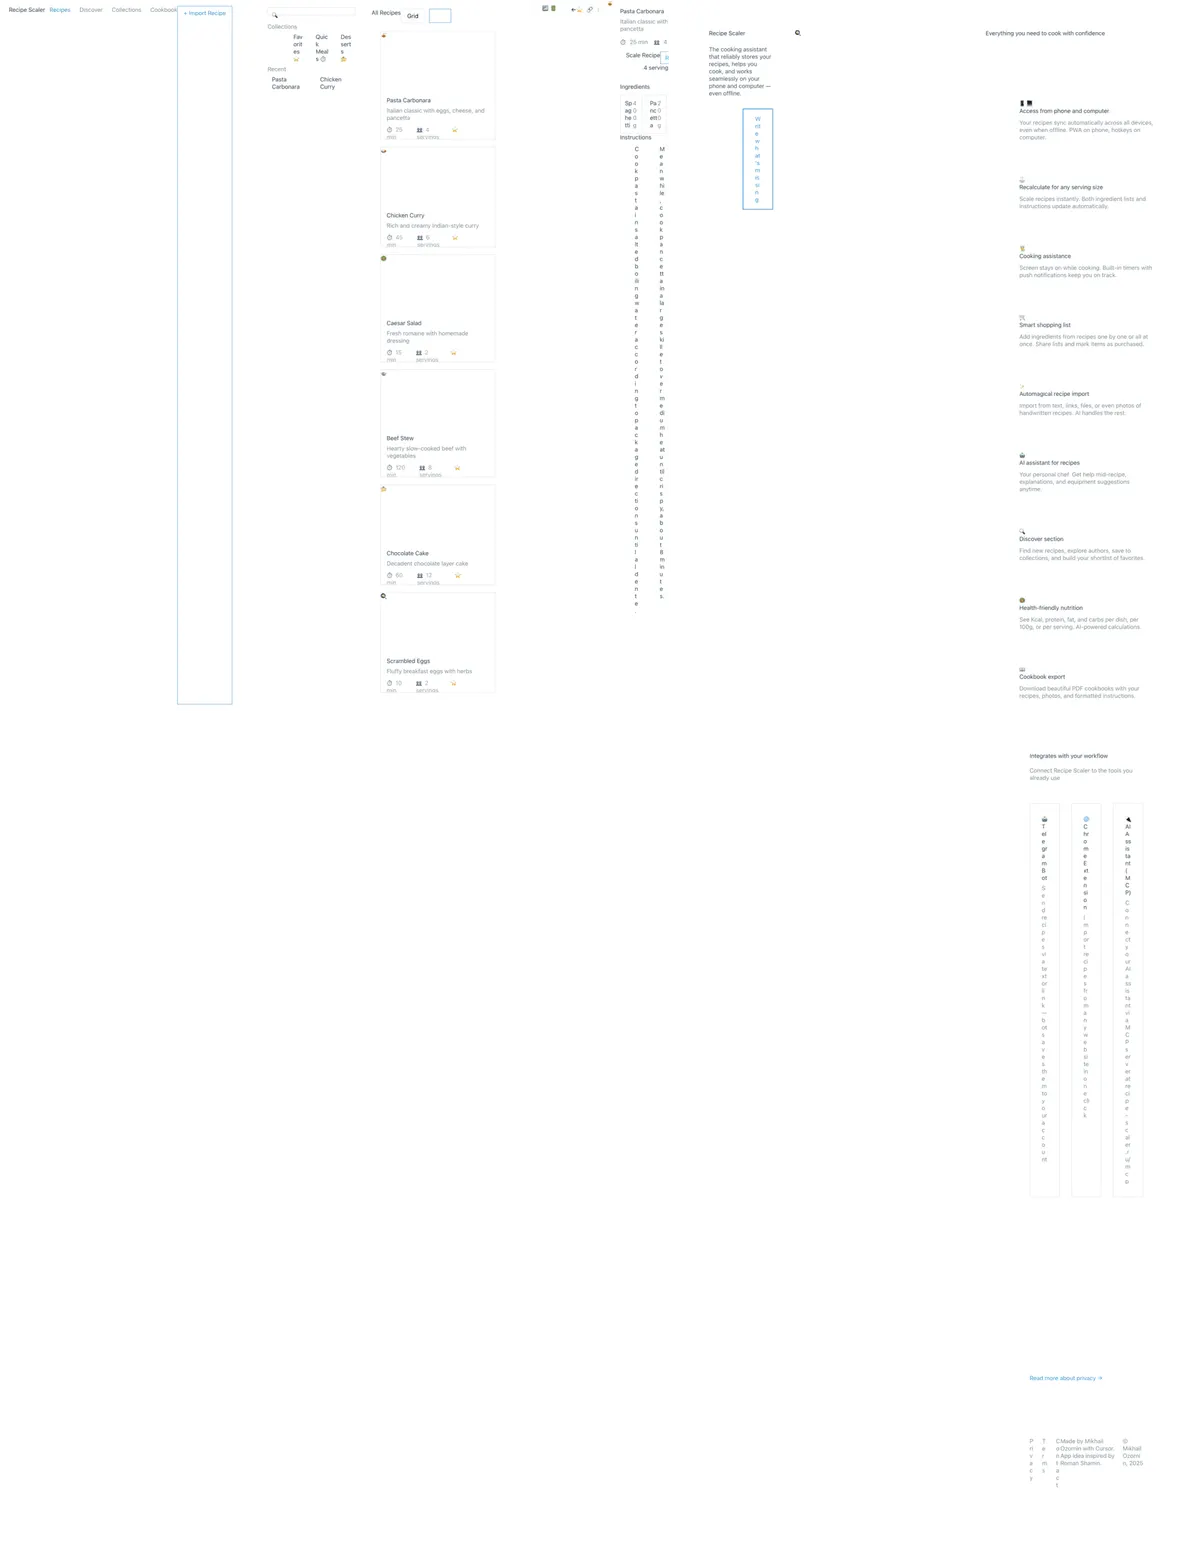
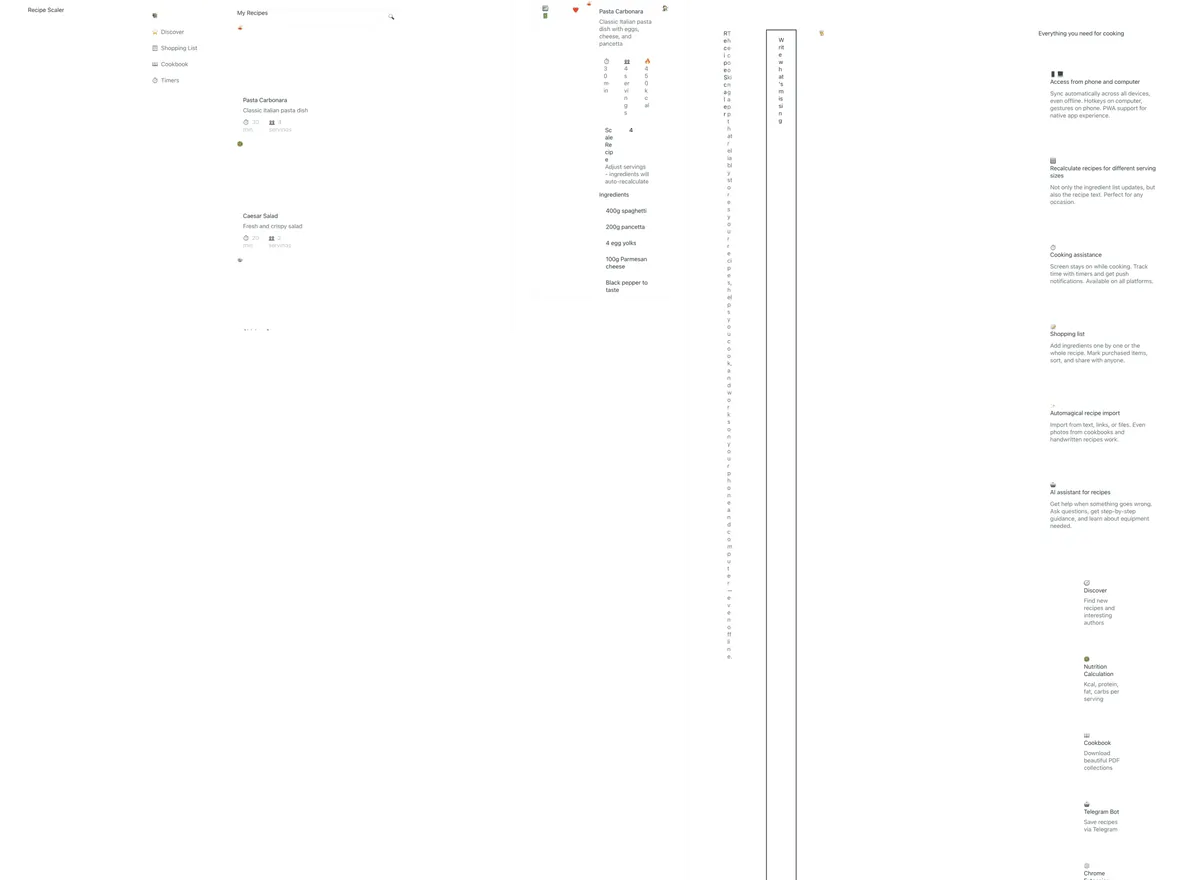
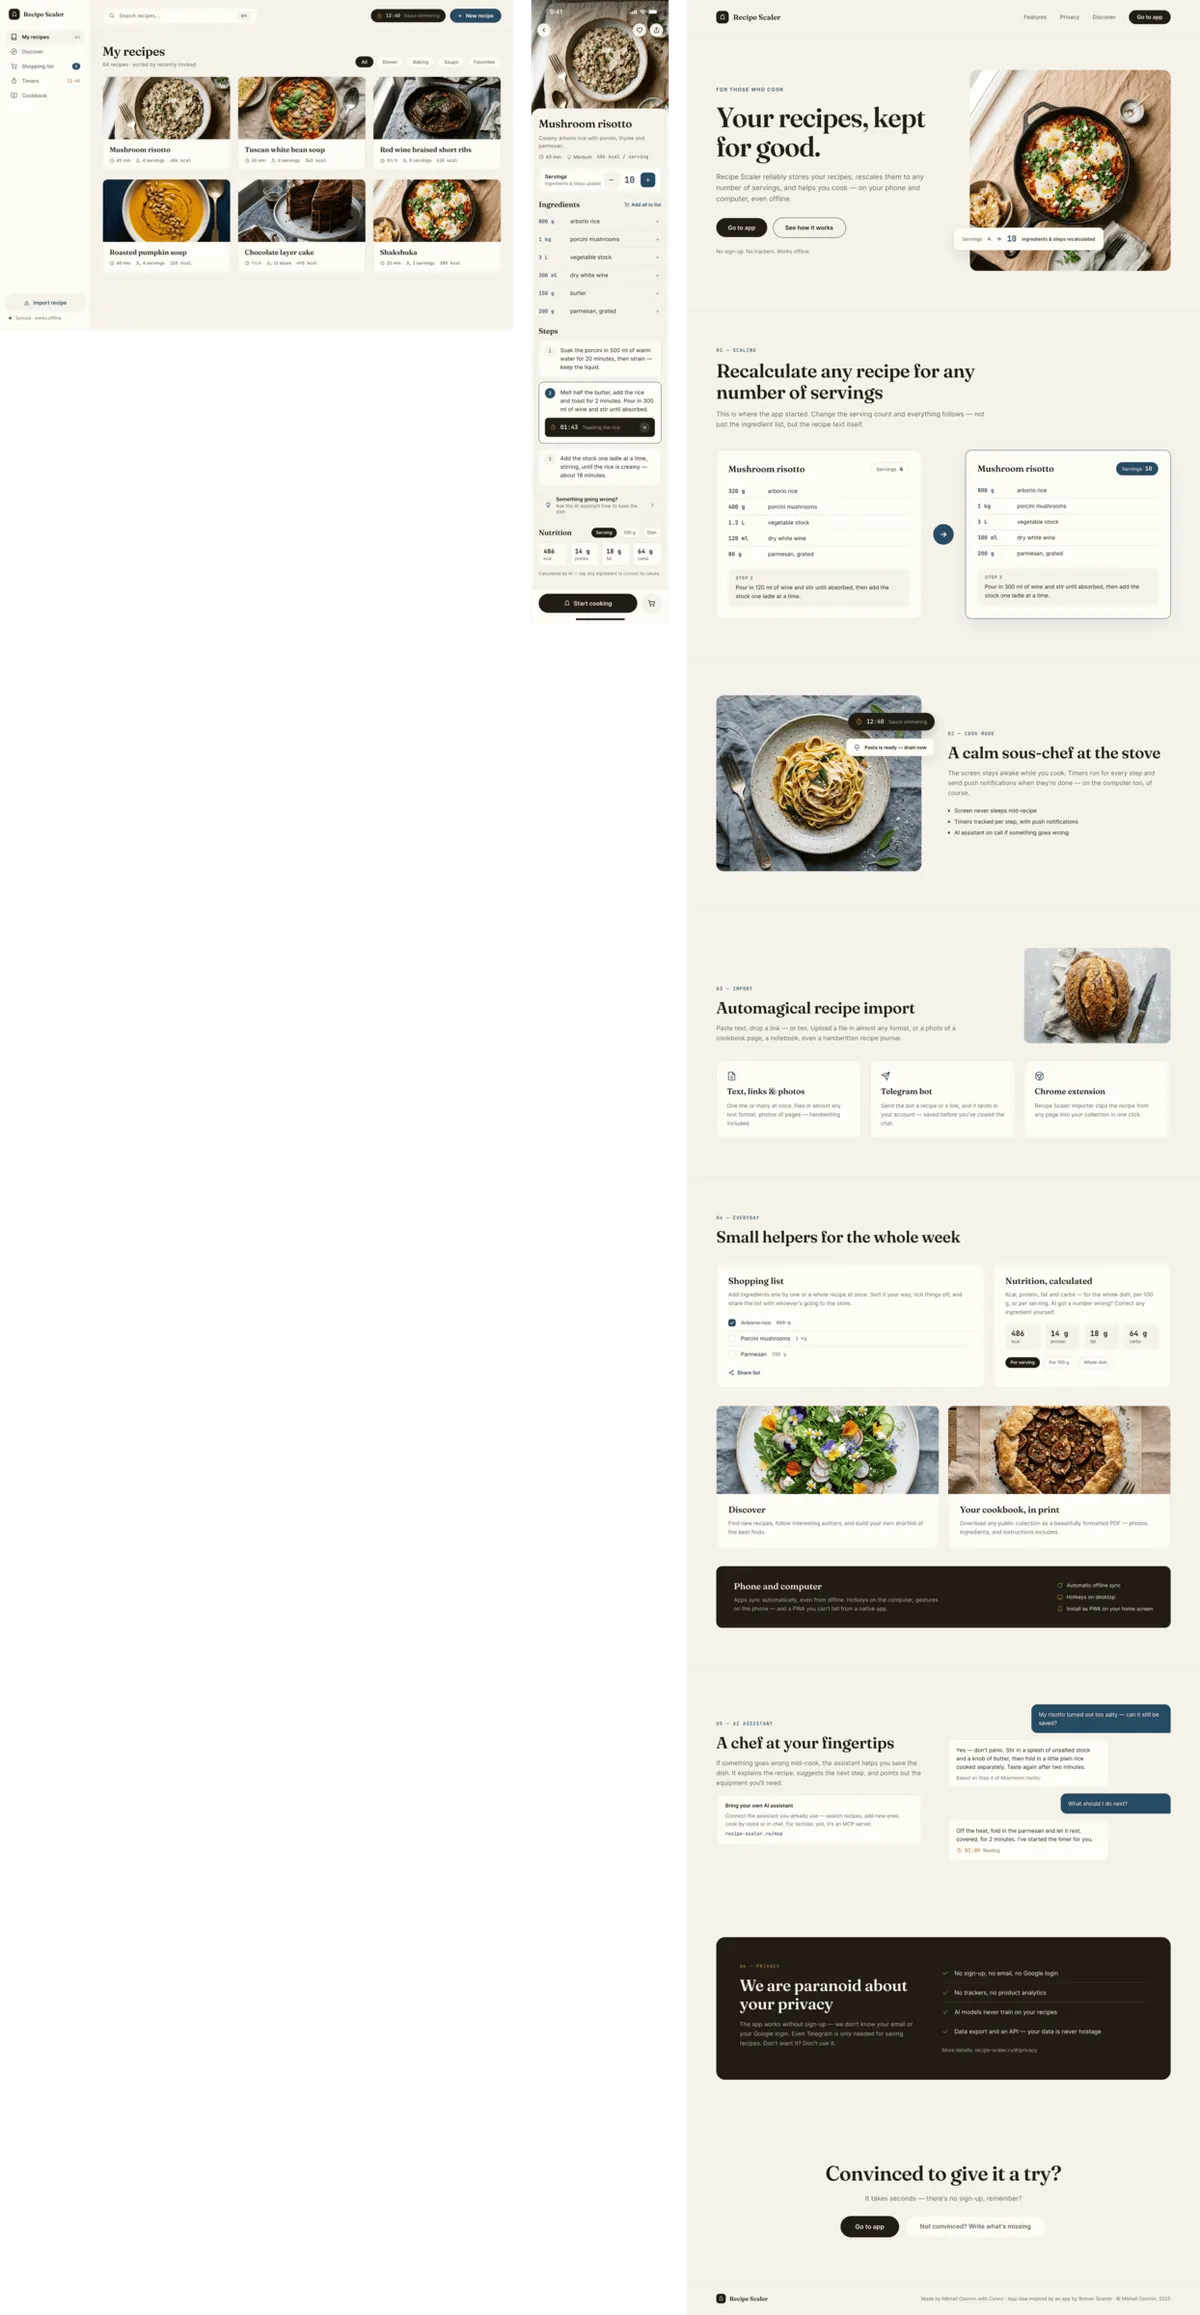
The promo page is weak, but mobile and desktop are very well structured and good (desktop especially). Honestly, not shockingly expensive (but it did cut corners on the promo page).
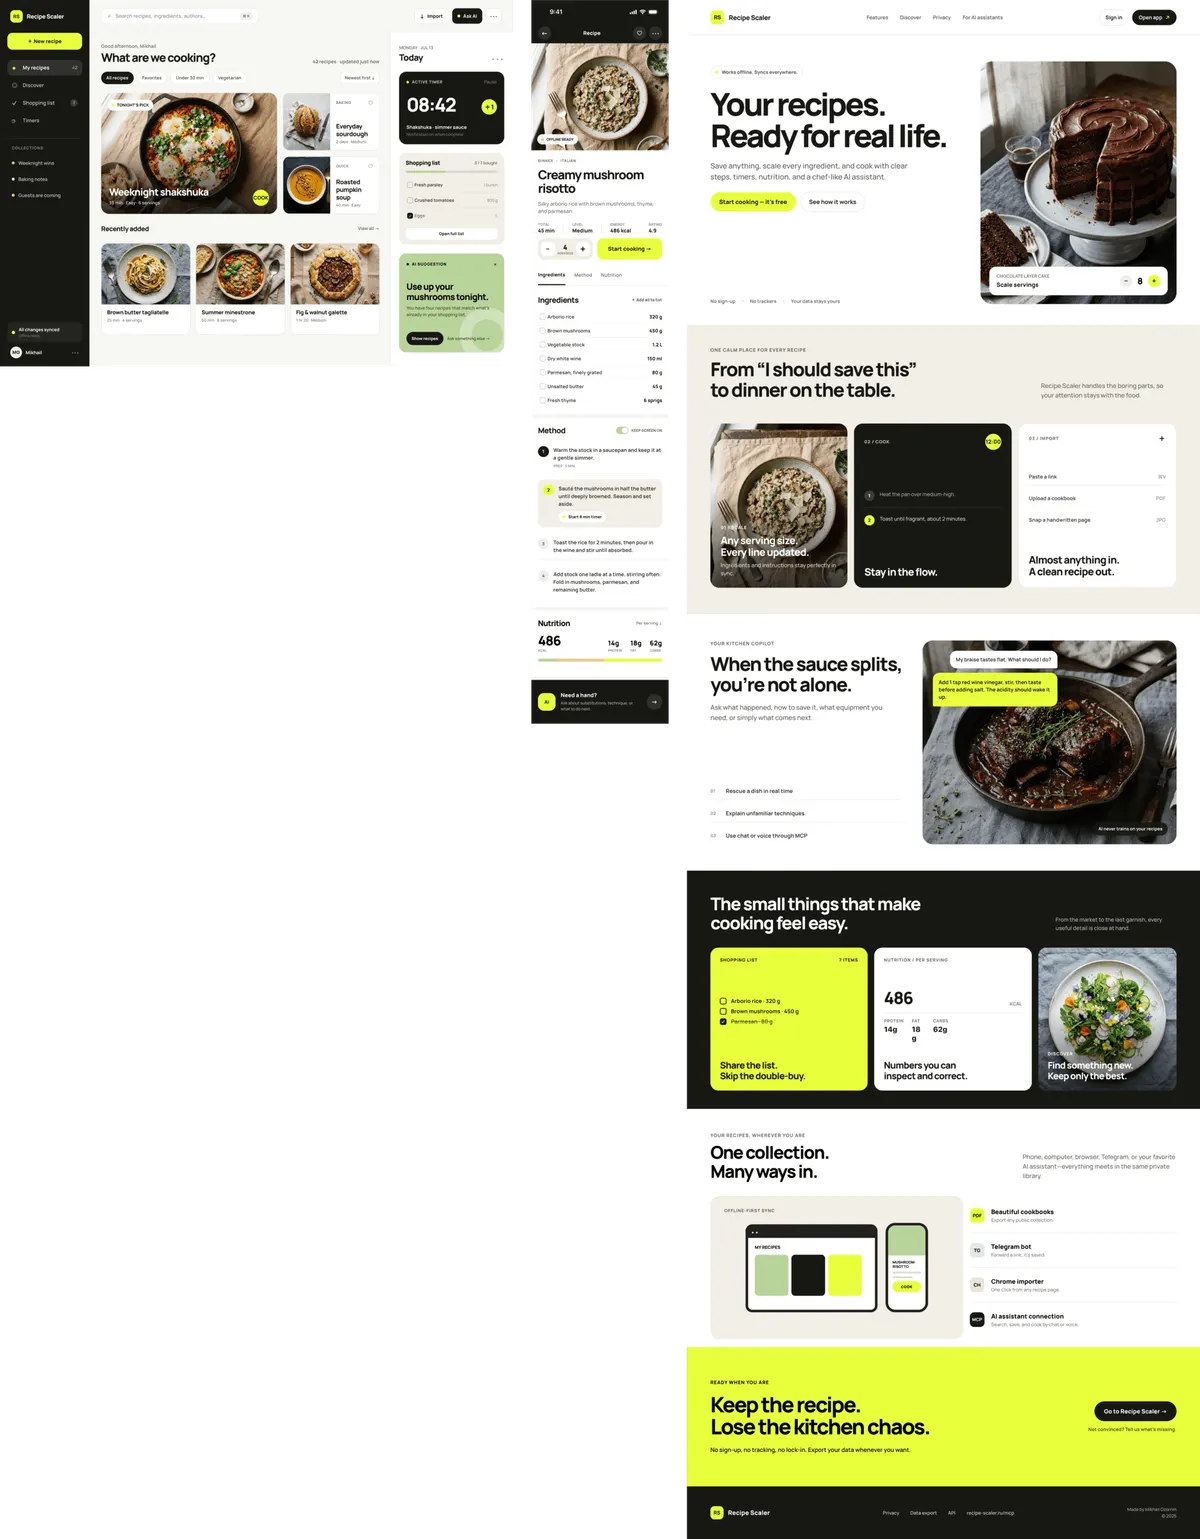
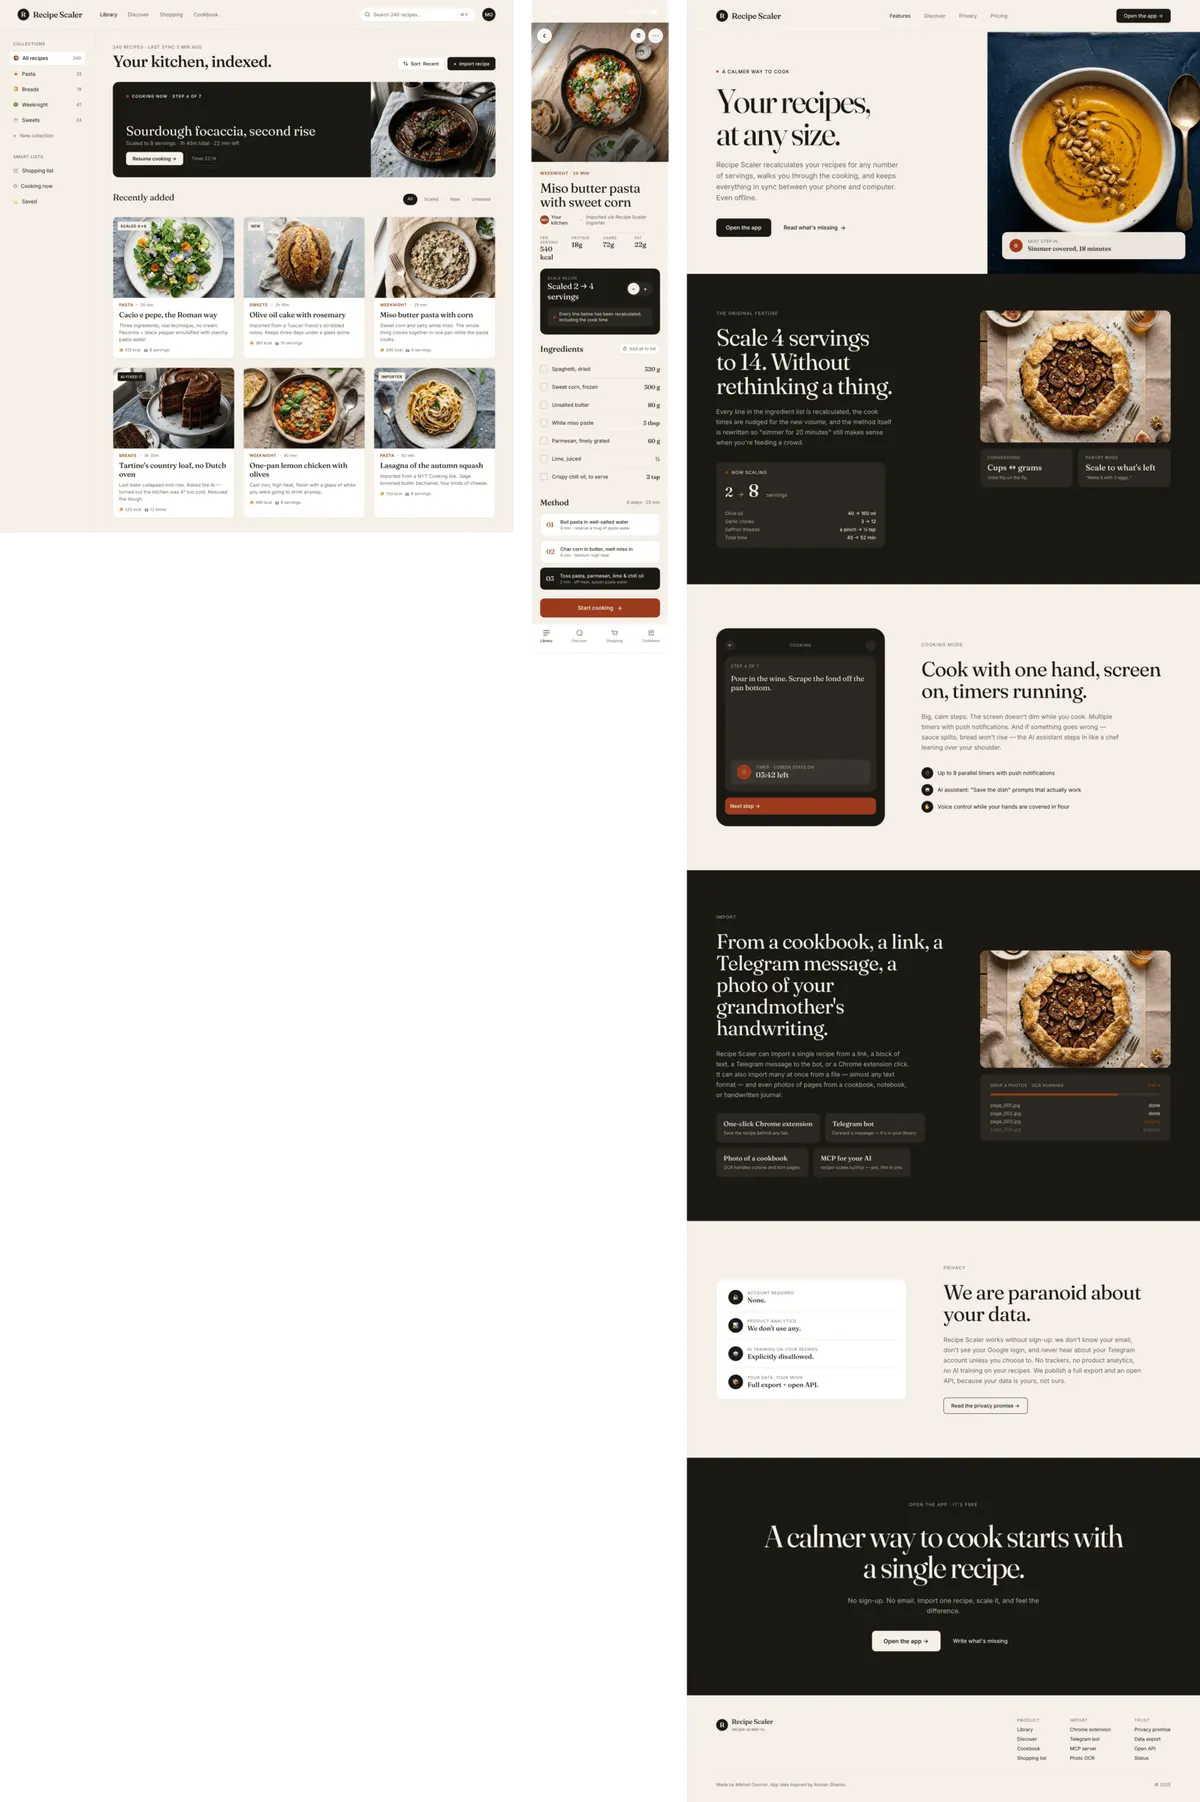
M2.7 → M3 — a huge step. From flop into top 3. Very similar in style to Opus
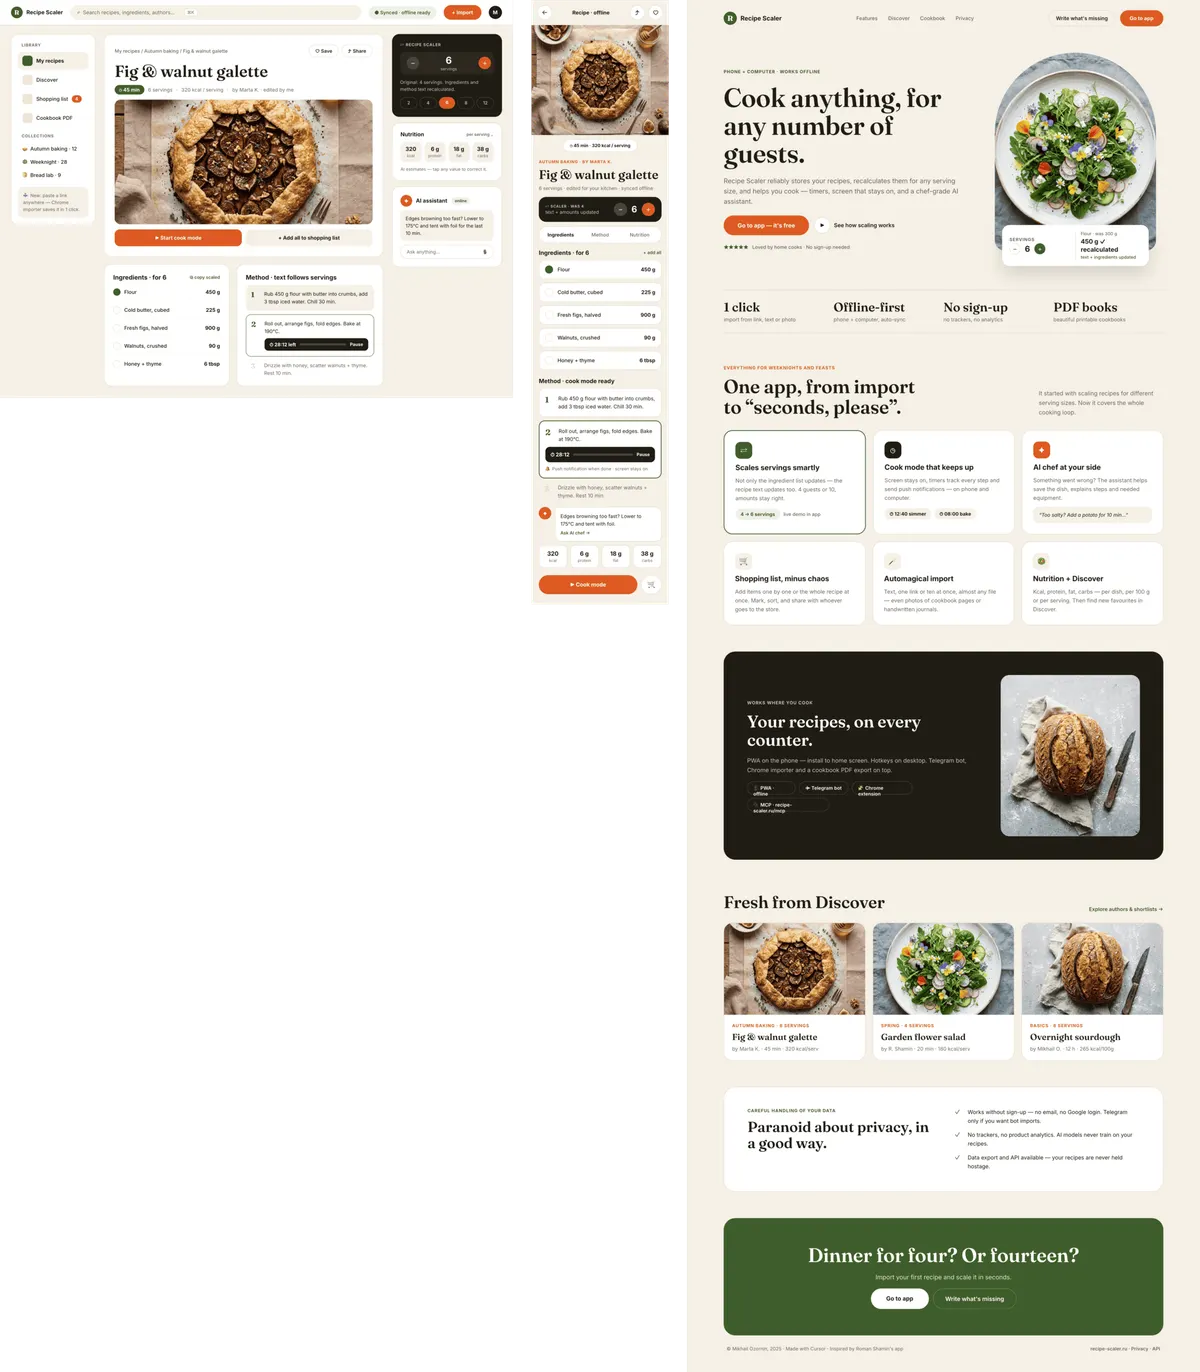
Nice, big progress for the model. Made very fast. * Product by Meta, recognized as extremist and banned in Russia.
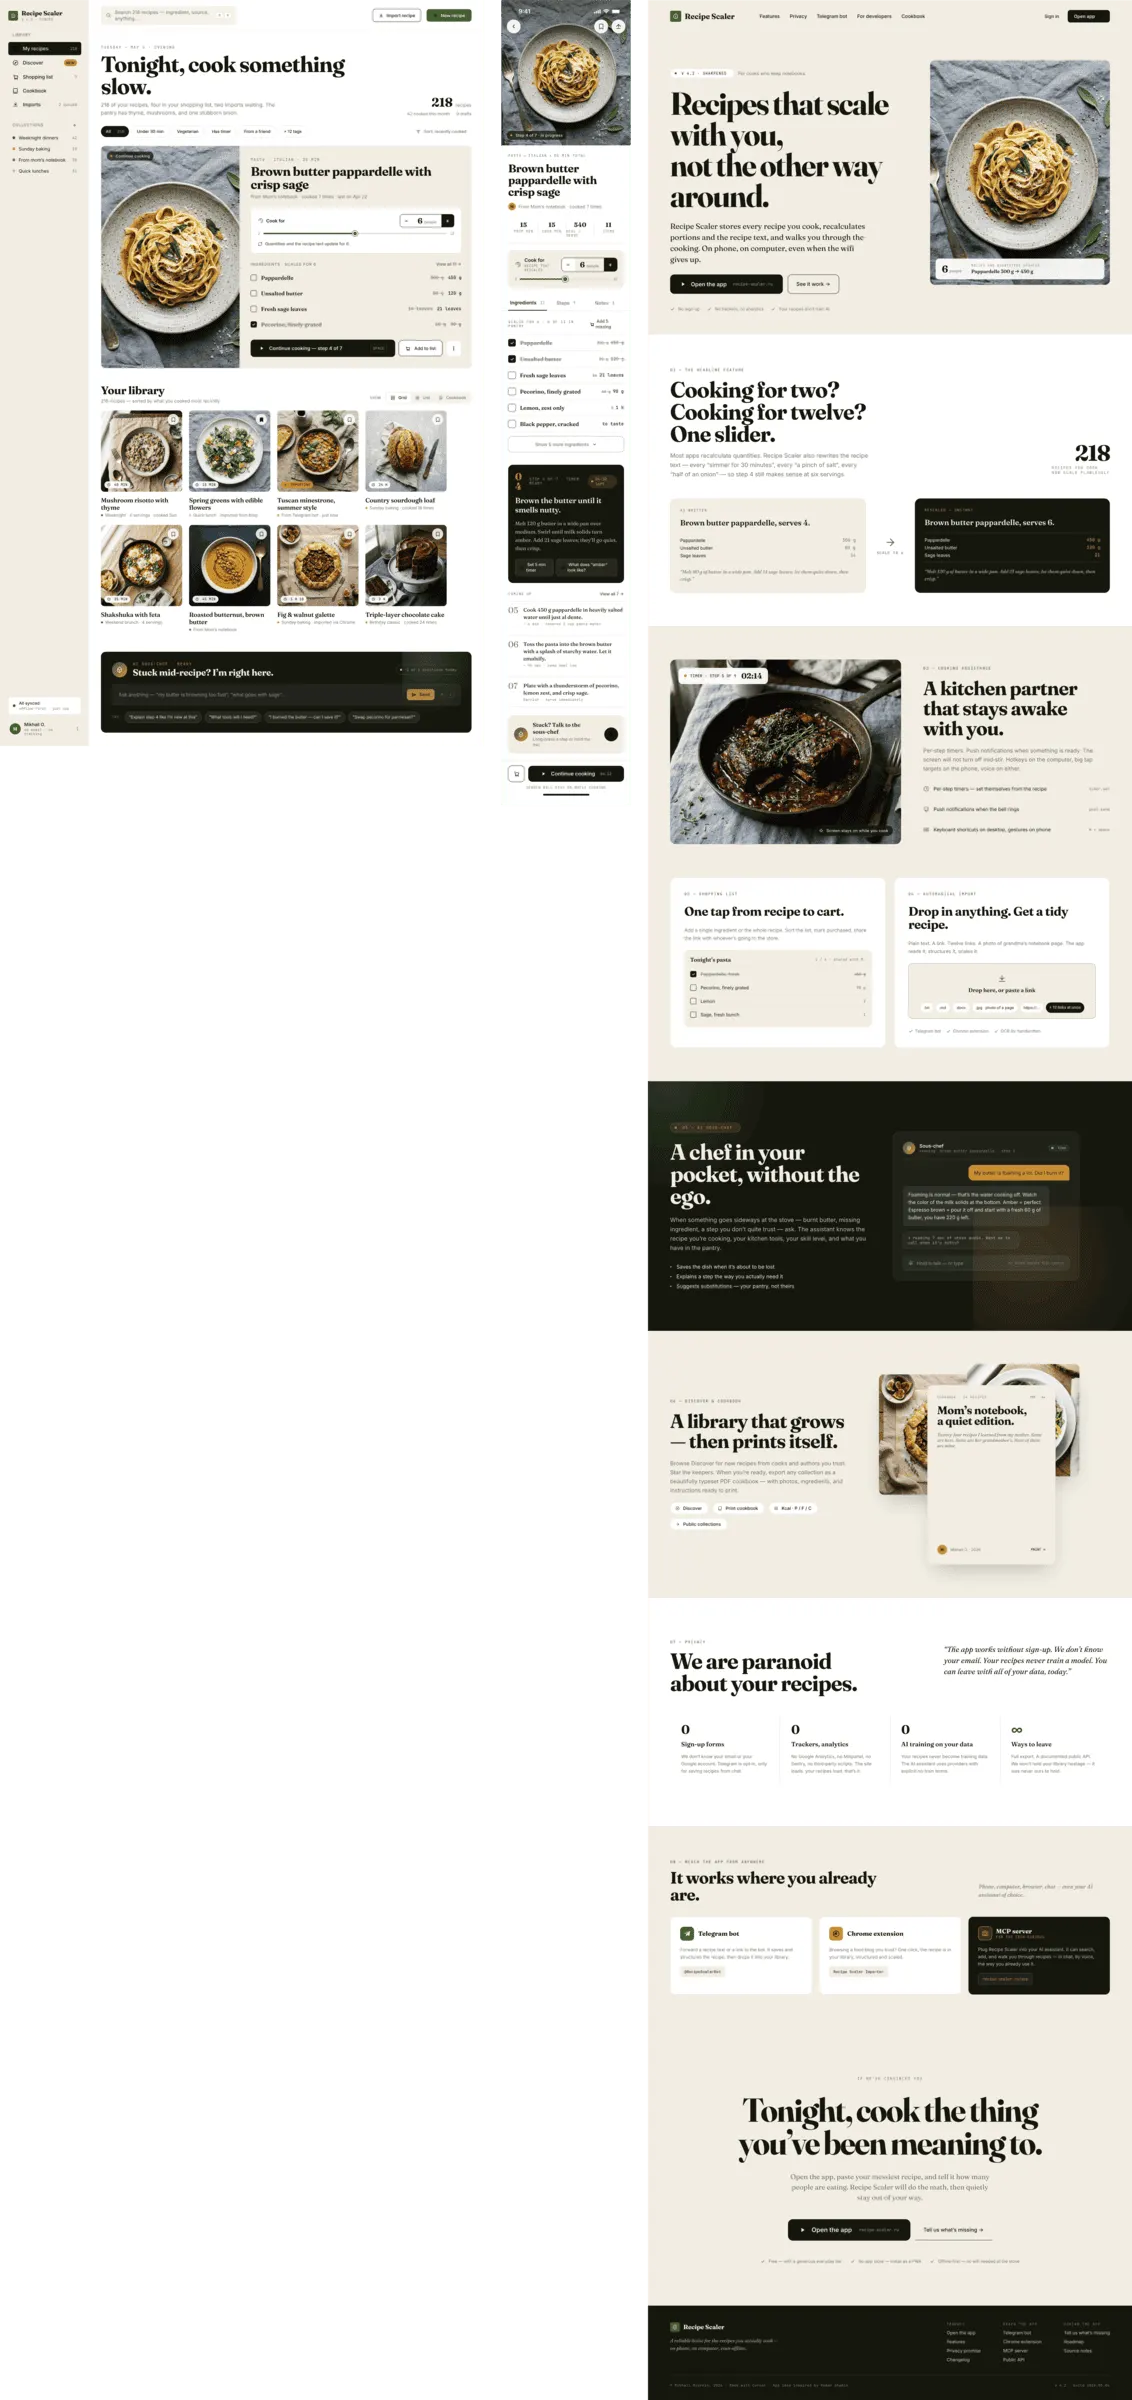
Twice as expensive as Opus 4.7 at Kilo. Checks itself a lot. The result is slightly better
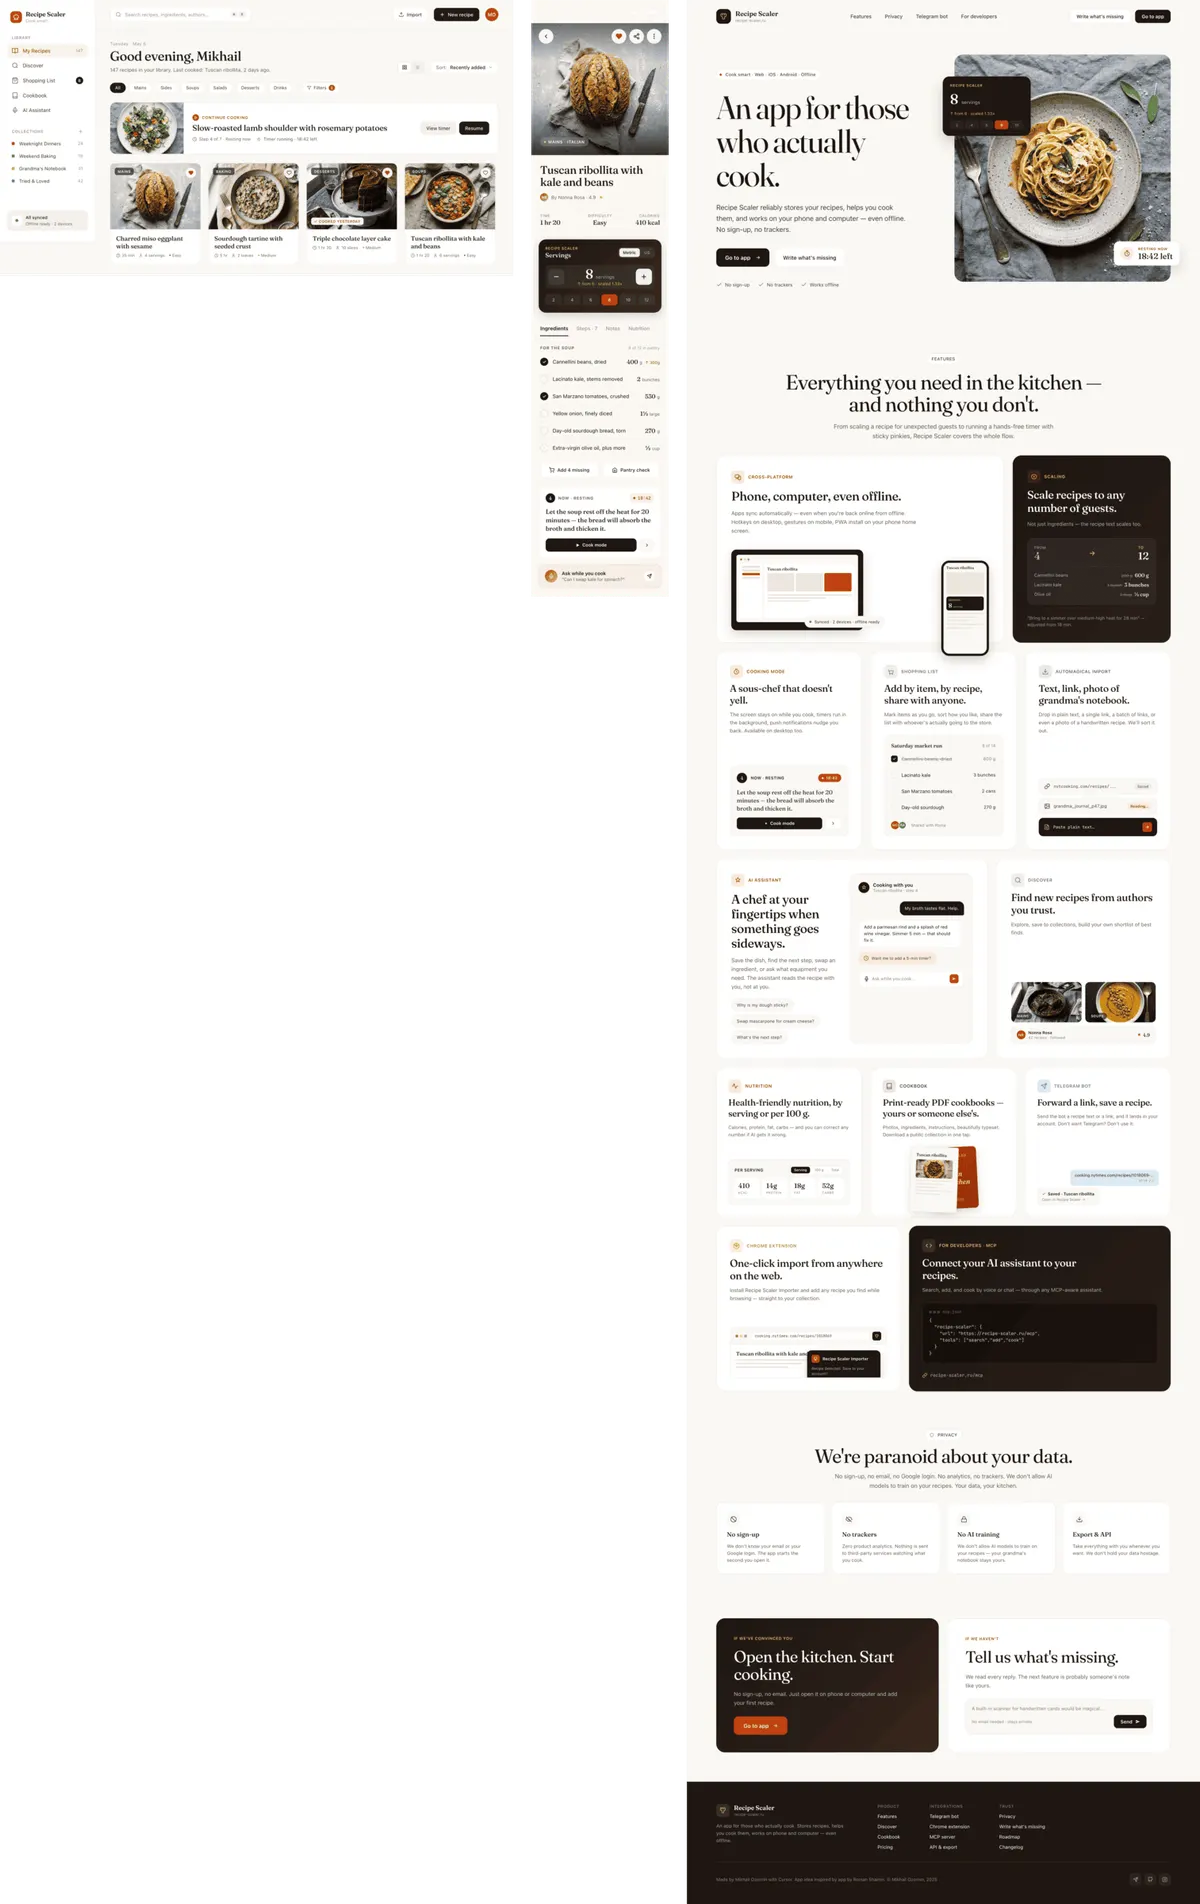
Typical Opus 4.7. Clean in places, interesting, from afar it's super-duper
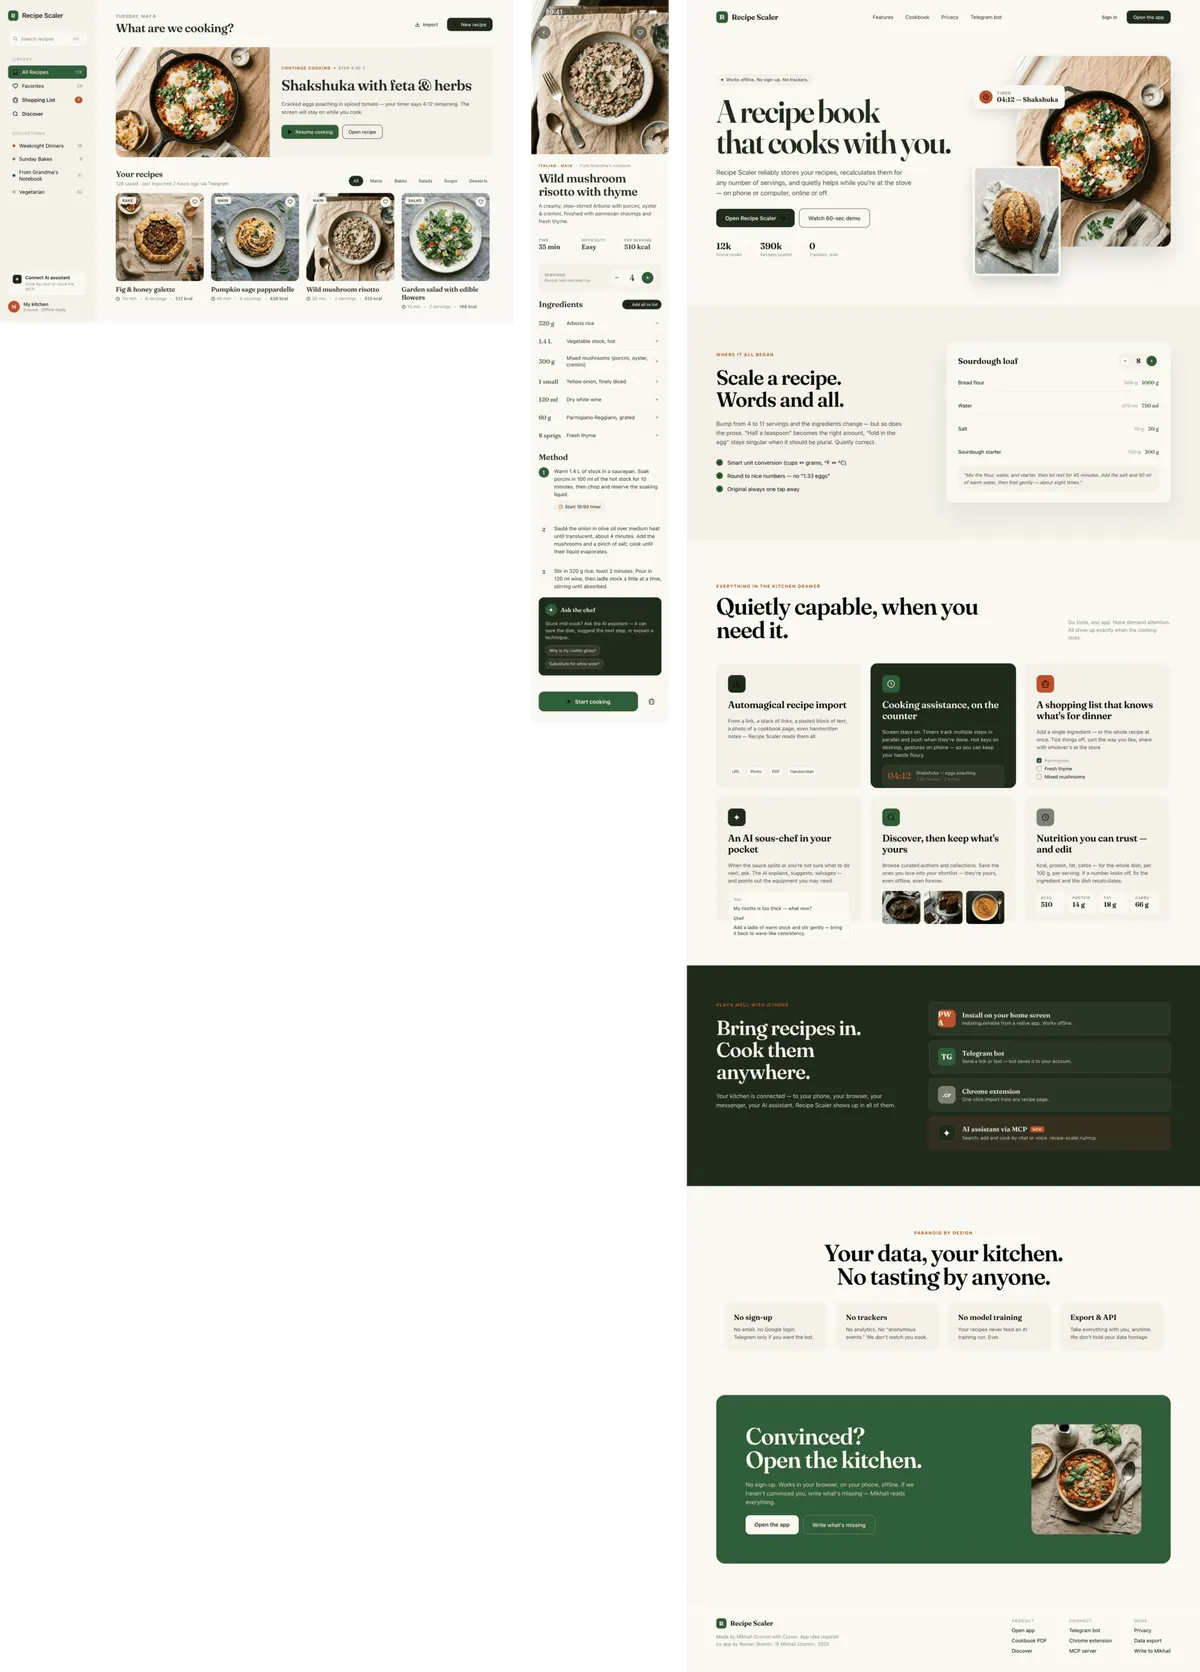
Keeps the Opus 4.7 style, simplifies the implementation
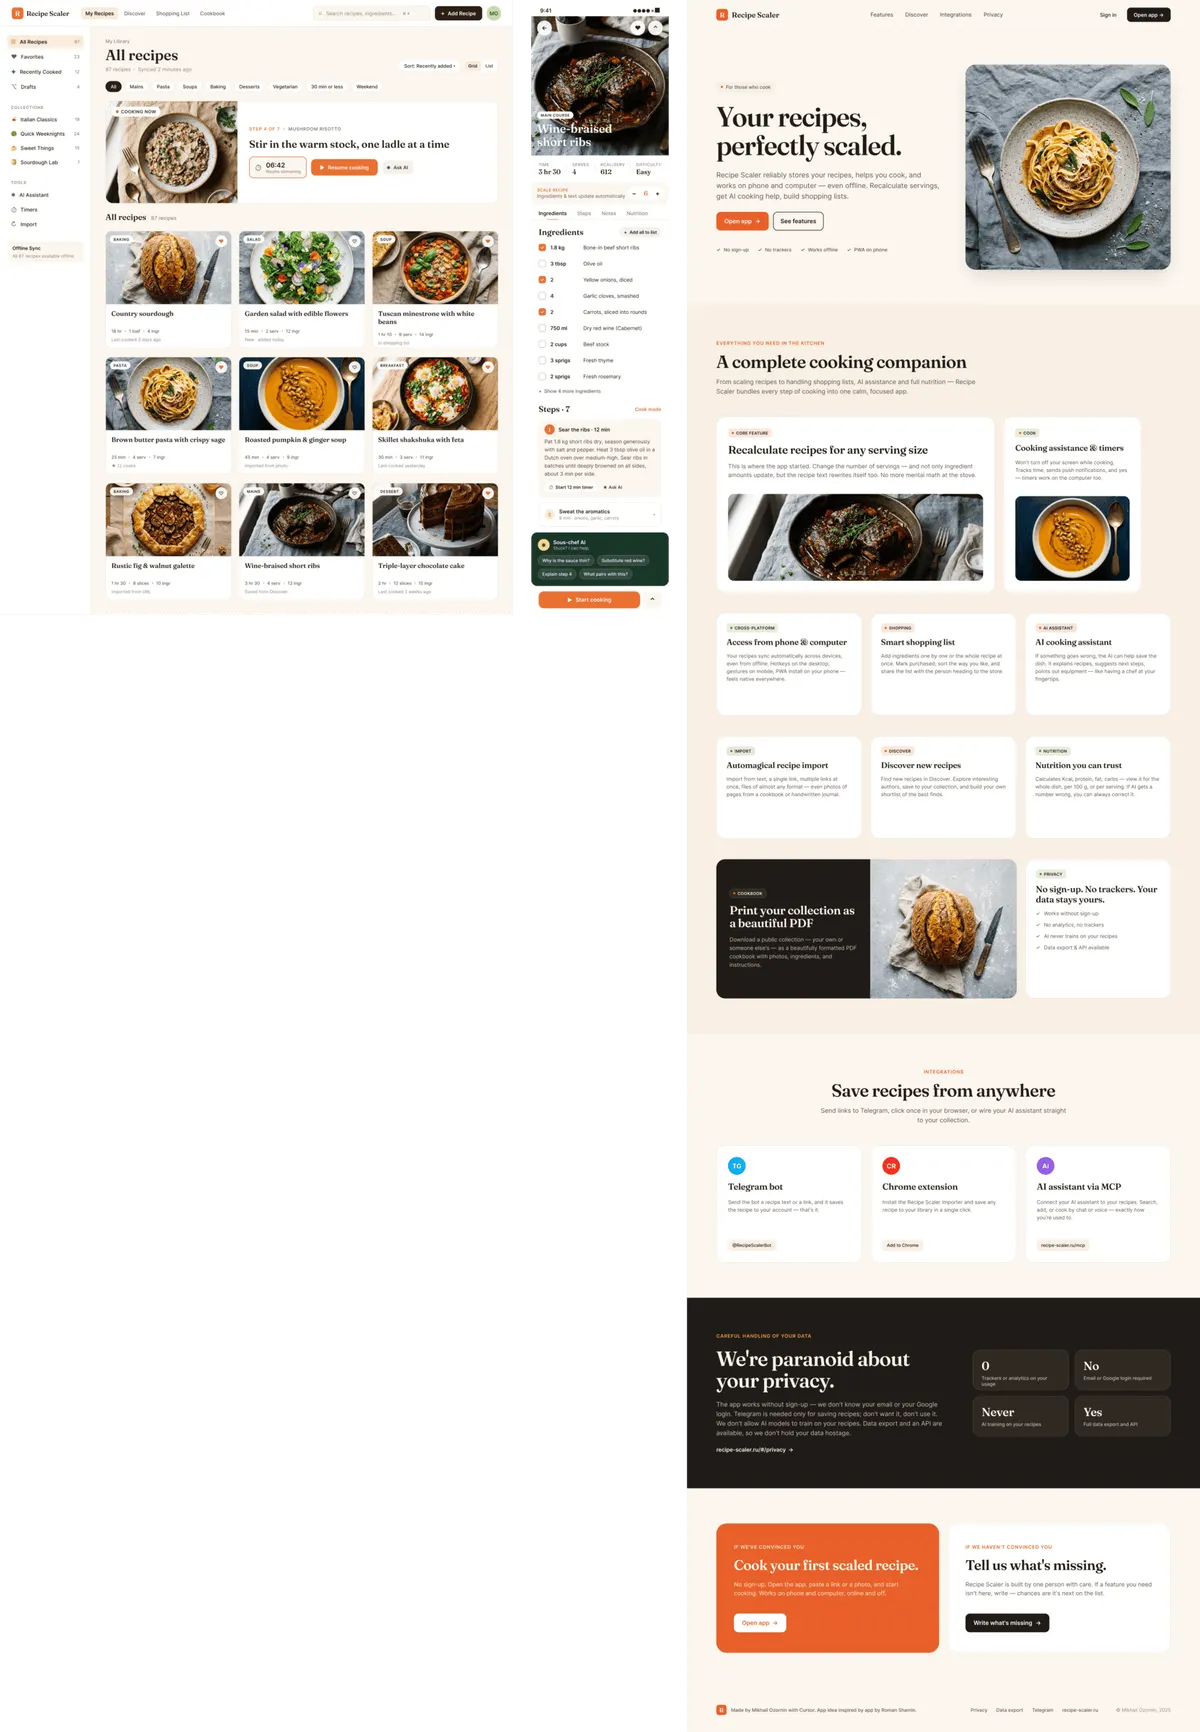
Opus in its style, especially from afar, but ate more than a full 5-hour quota
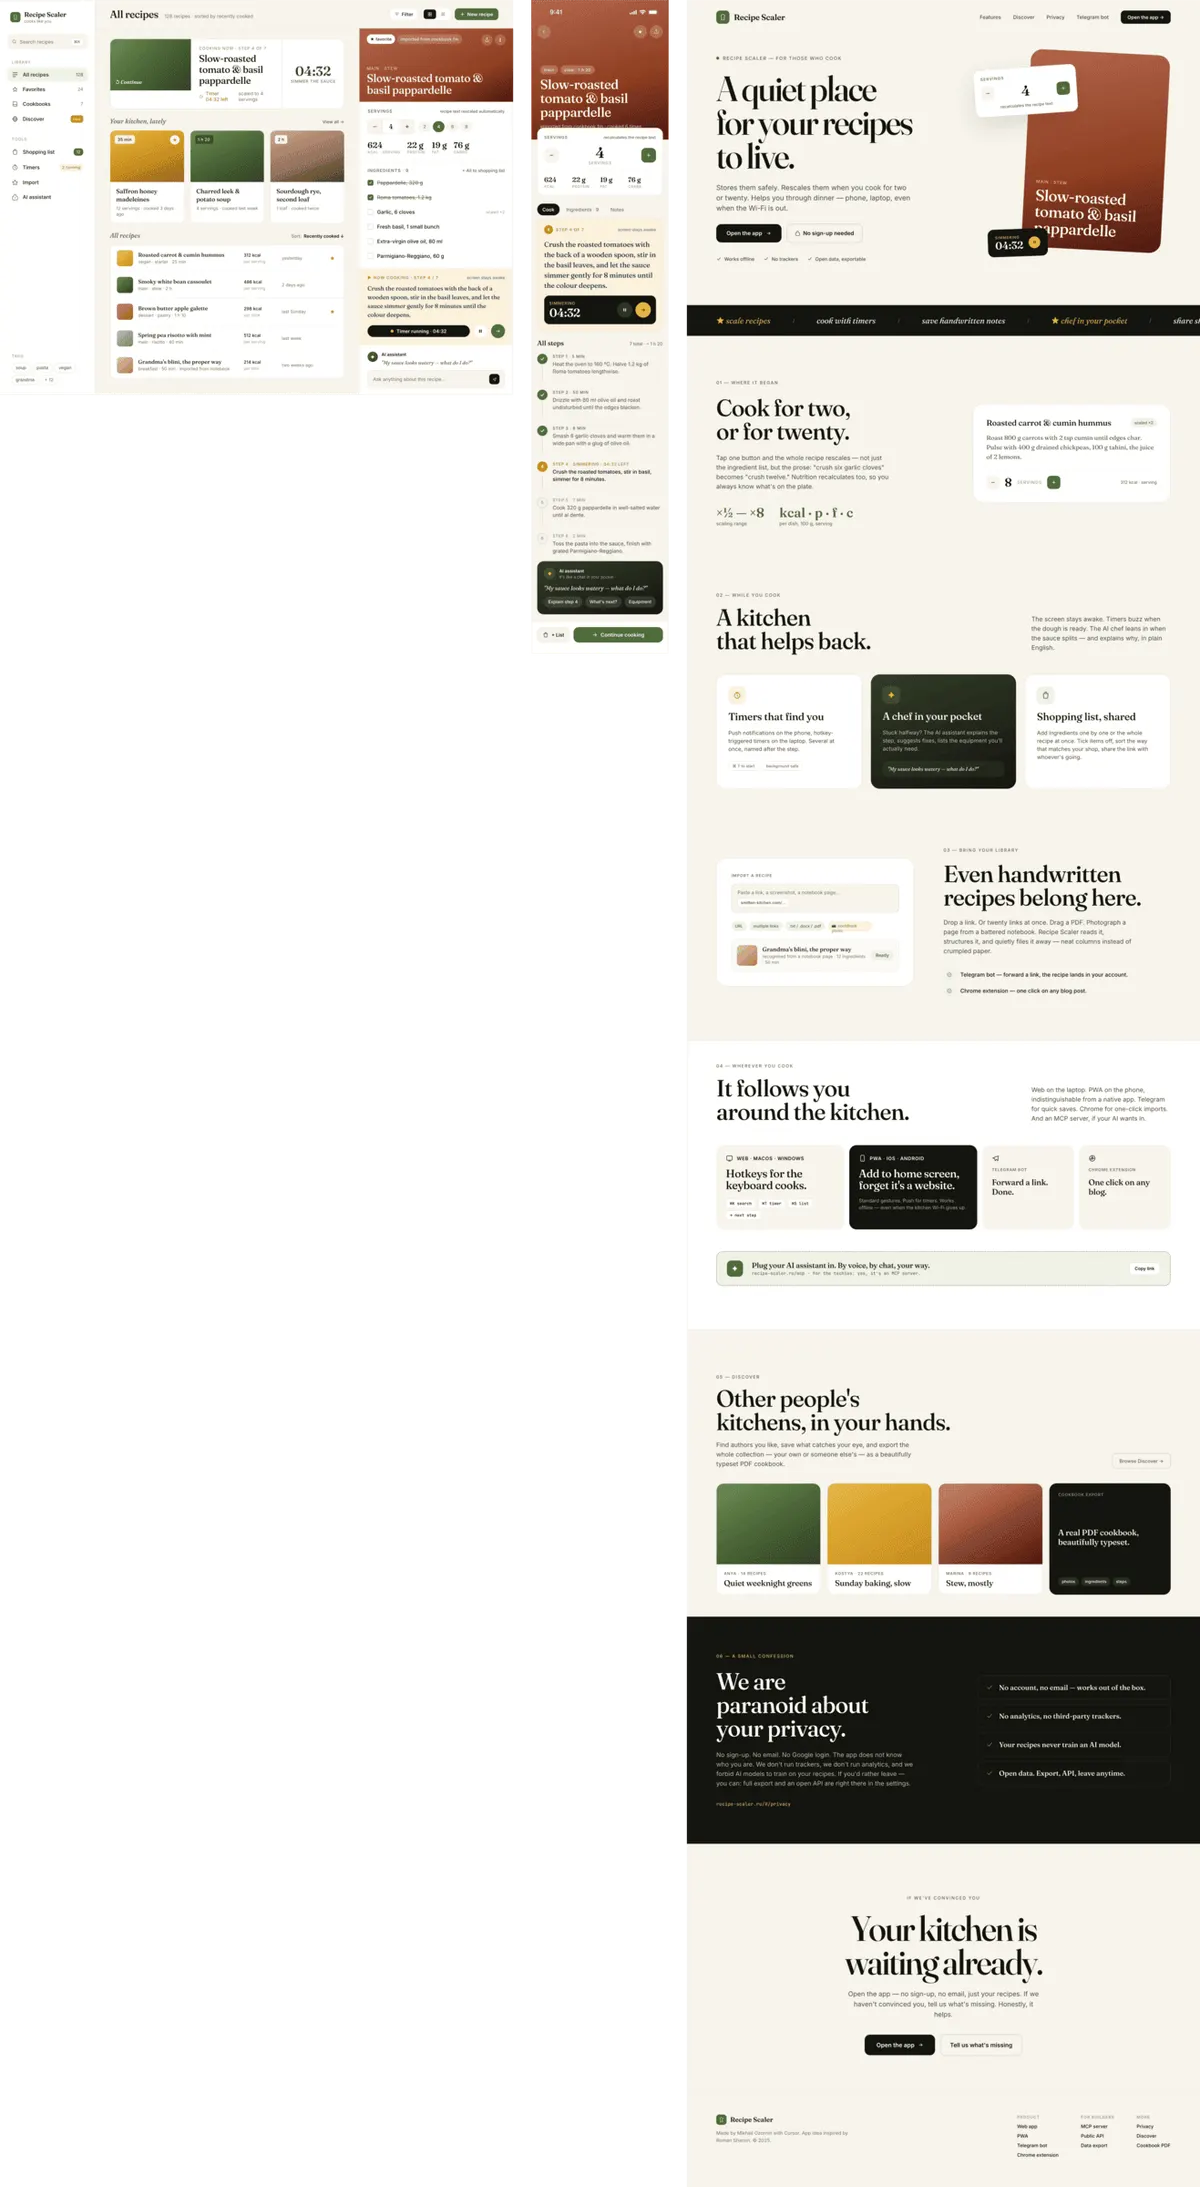
Quick. Expensive. Awesome.
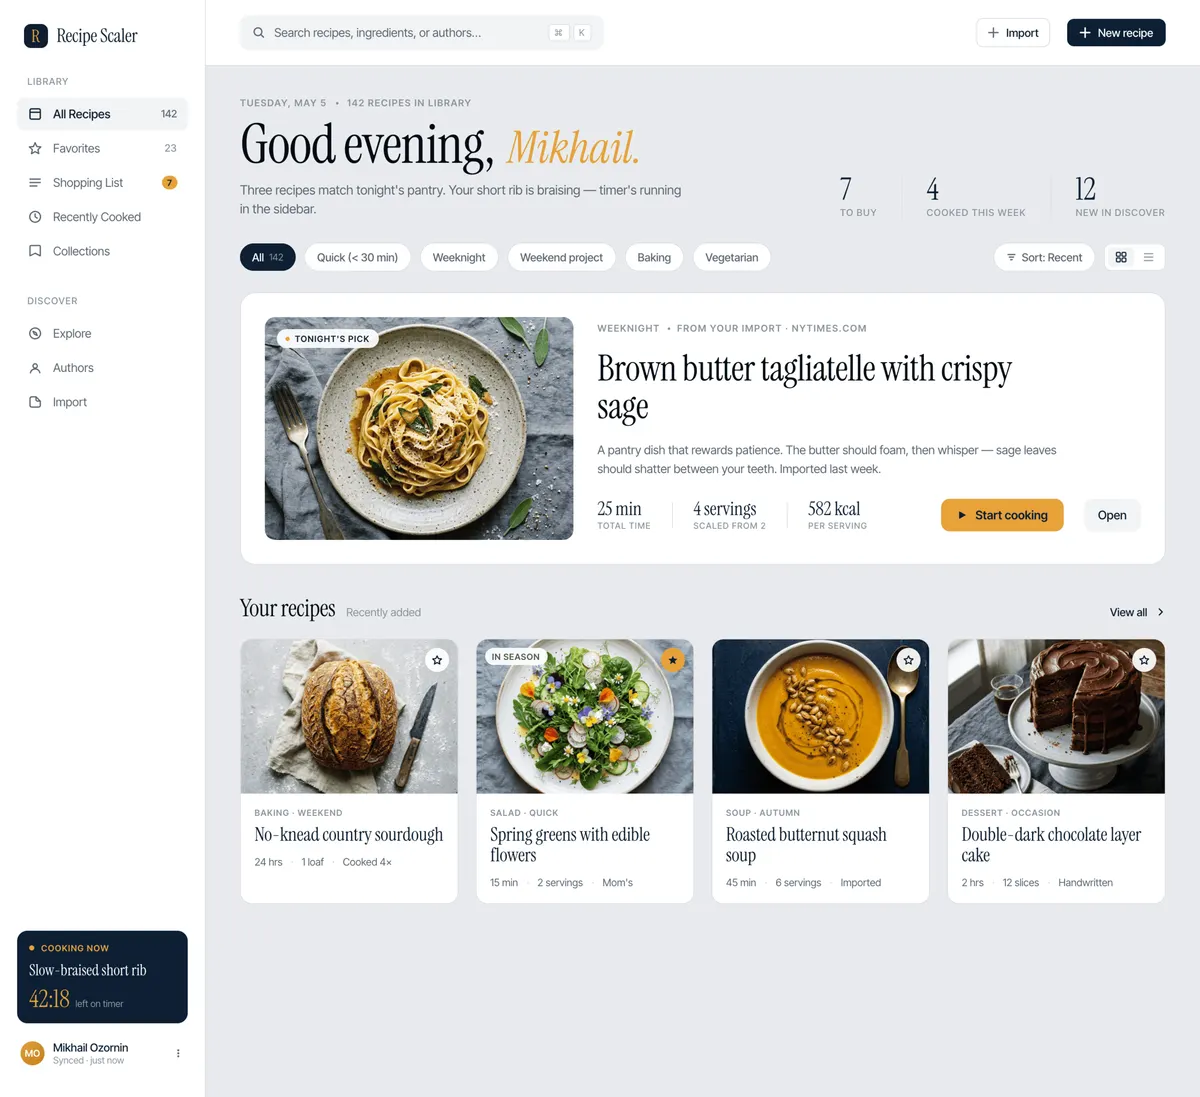
Not bad; after this screen Openrouter banned American SOTA models
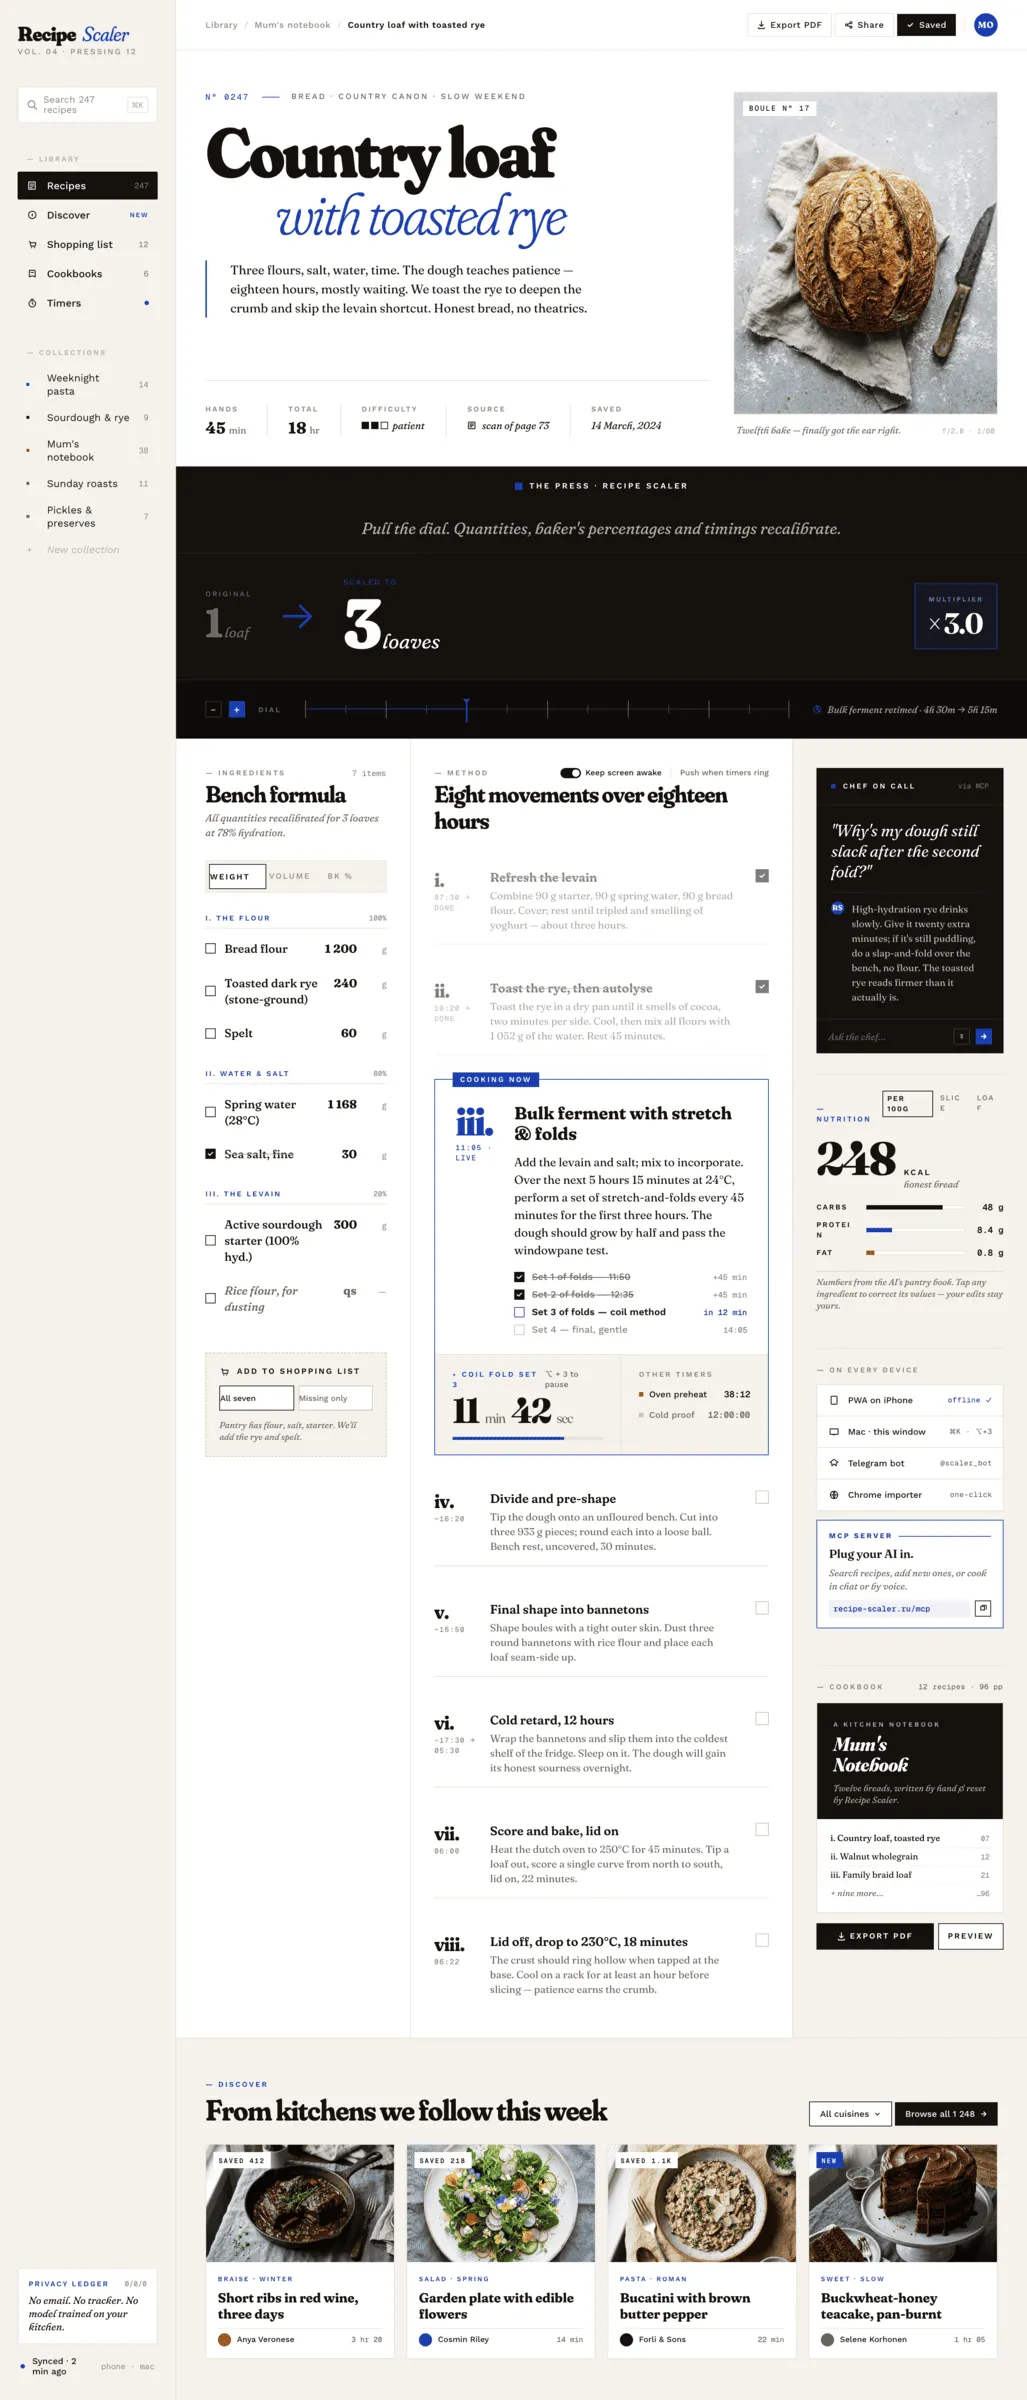
Opus with Frontend Design skill — desktop only in local asset set
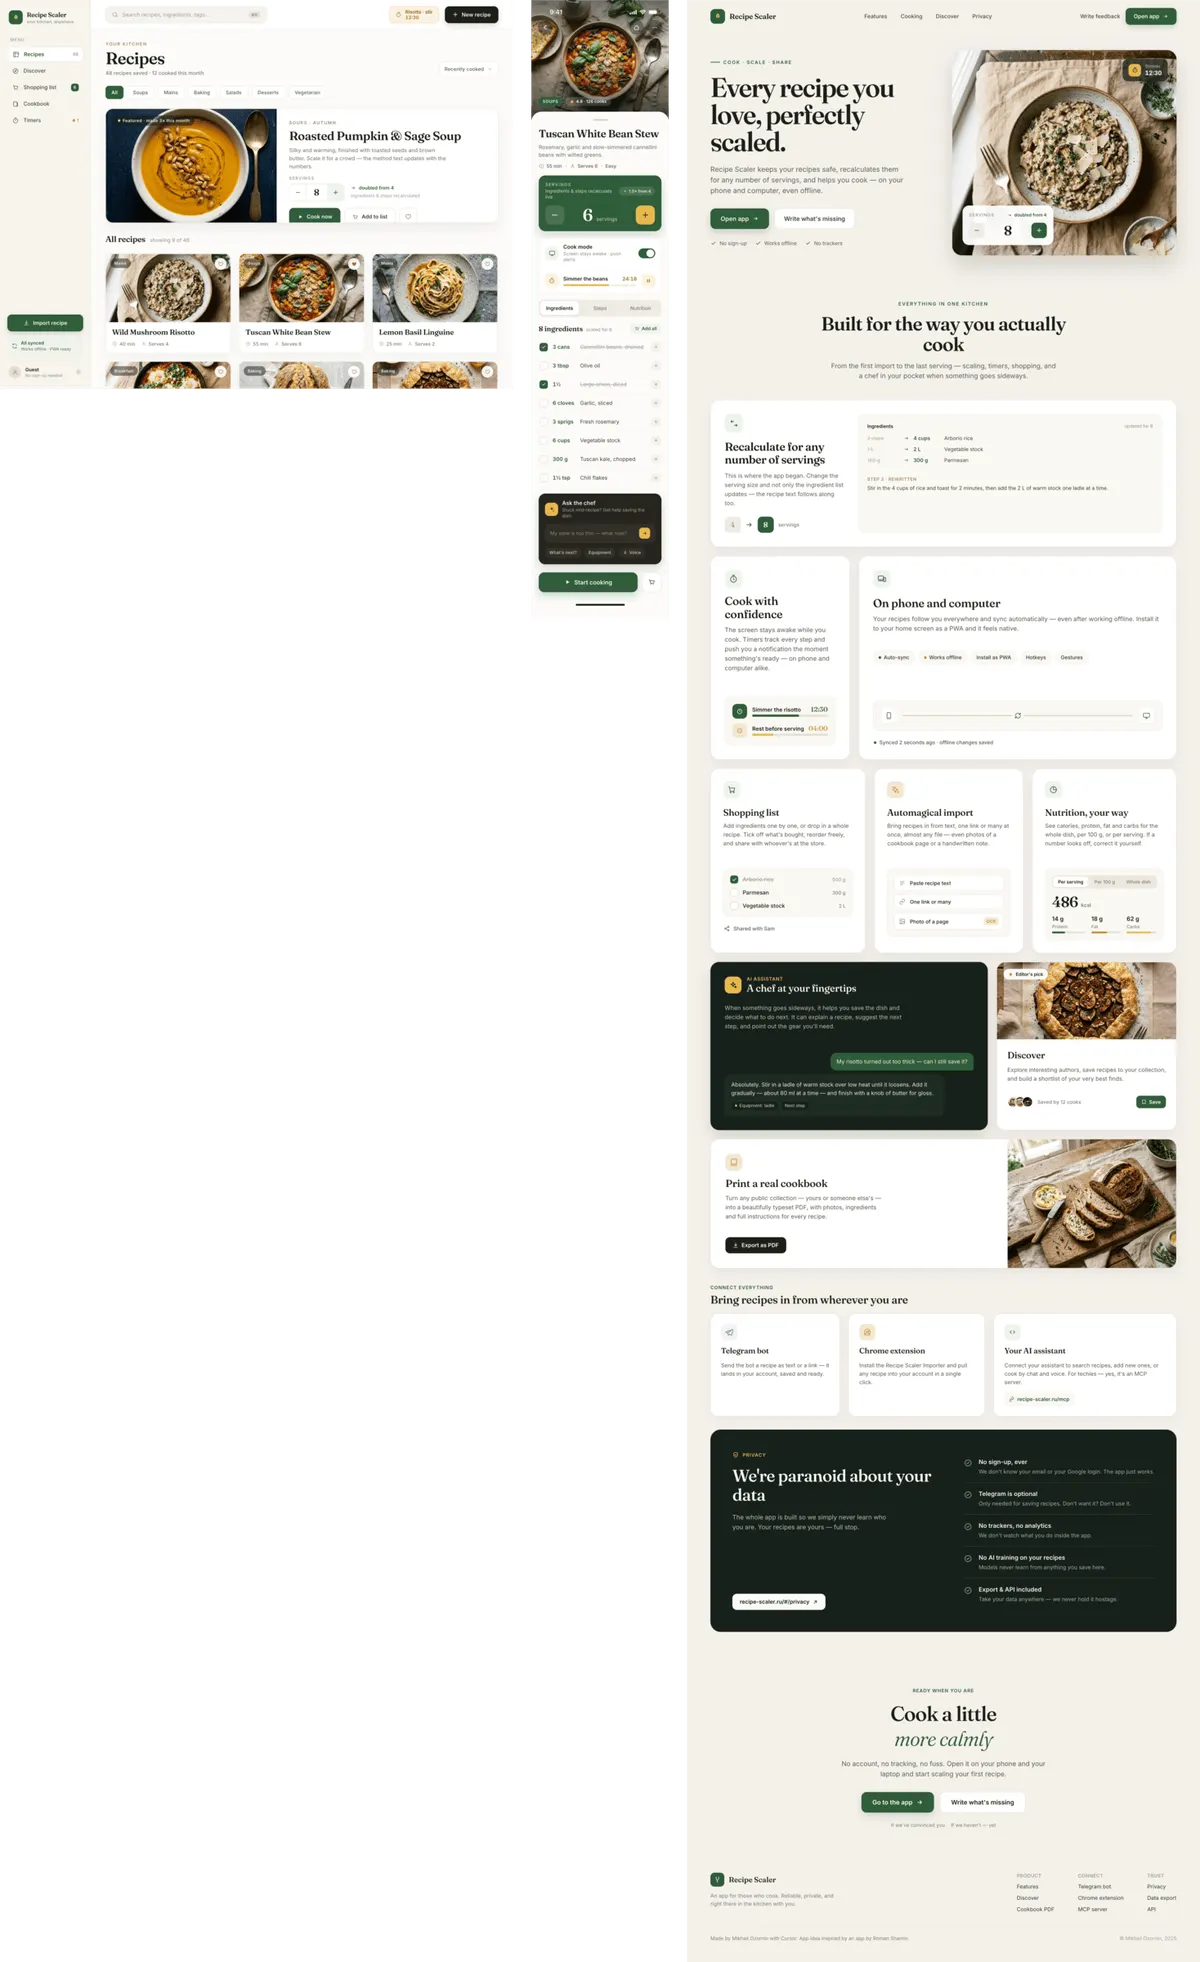
Burns more; not necessarily better than 4.7. Three screens used half of the already-doubled 5h pro quota.
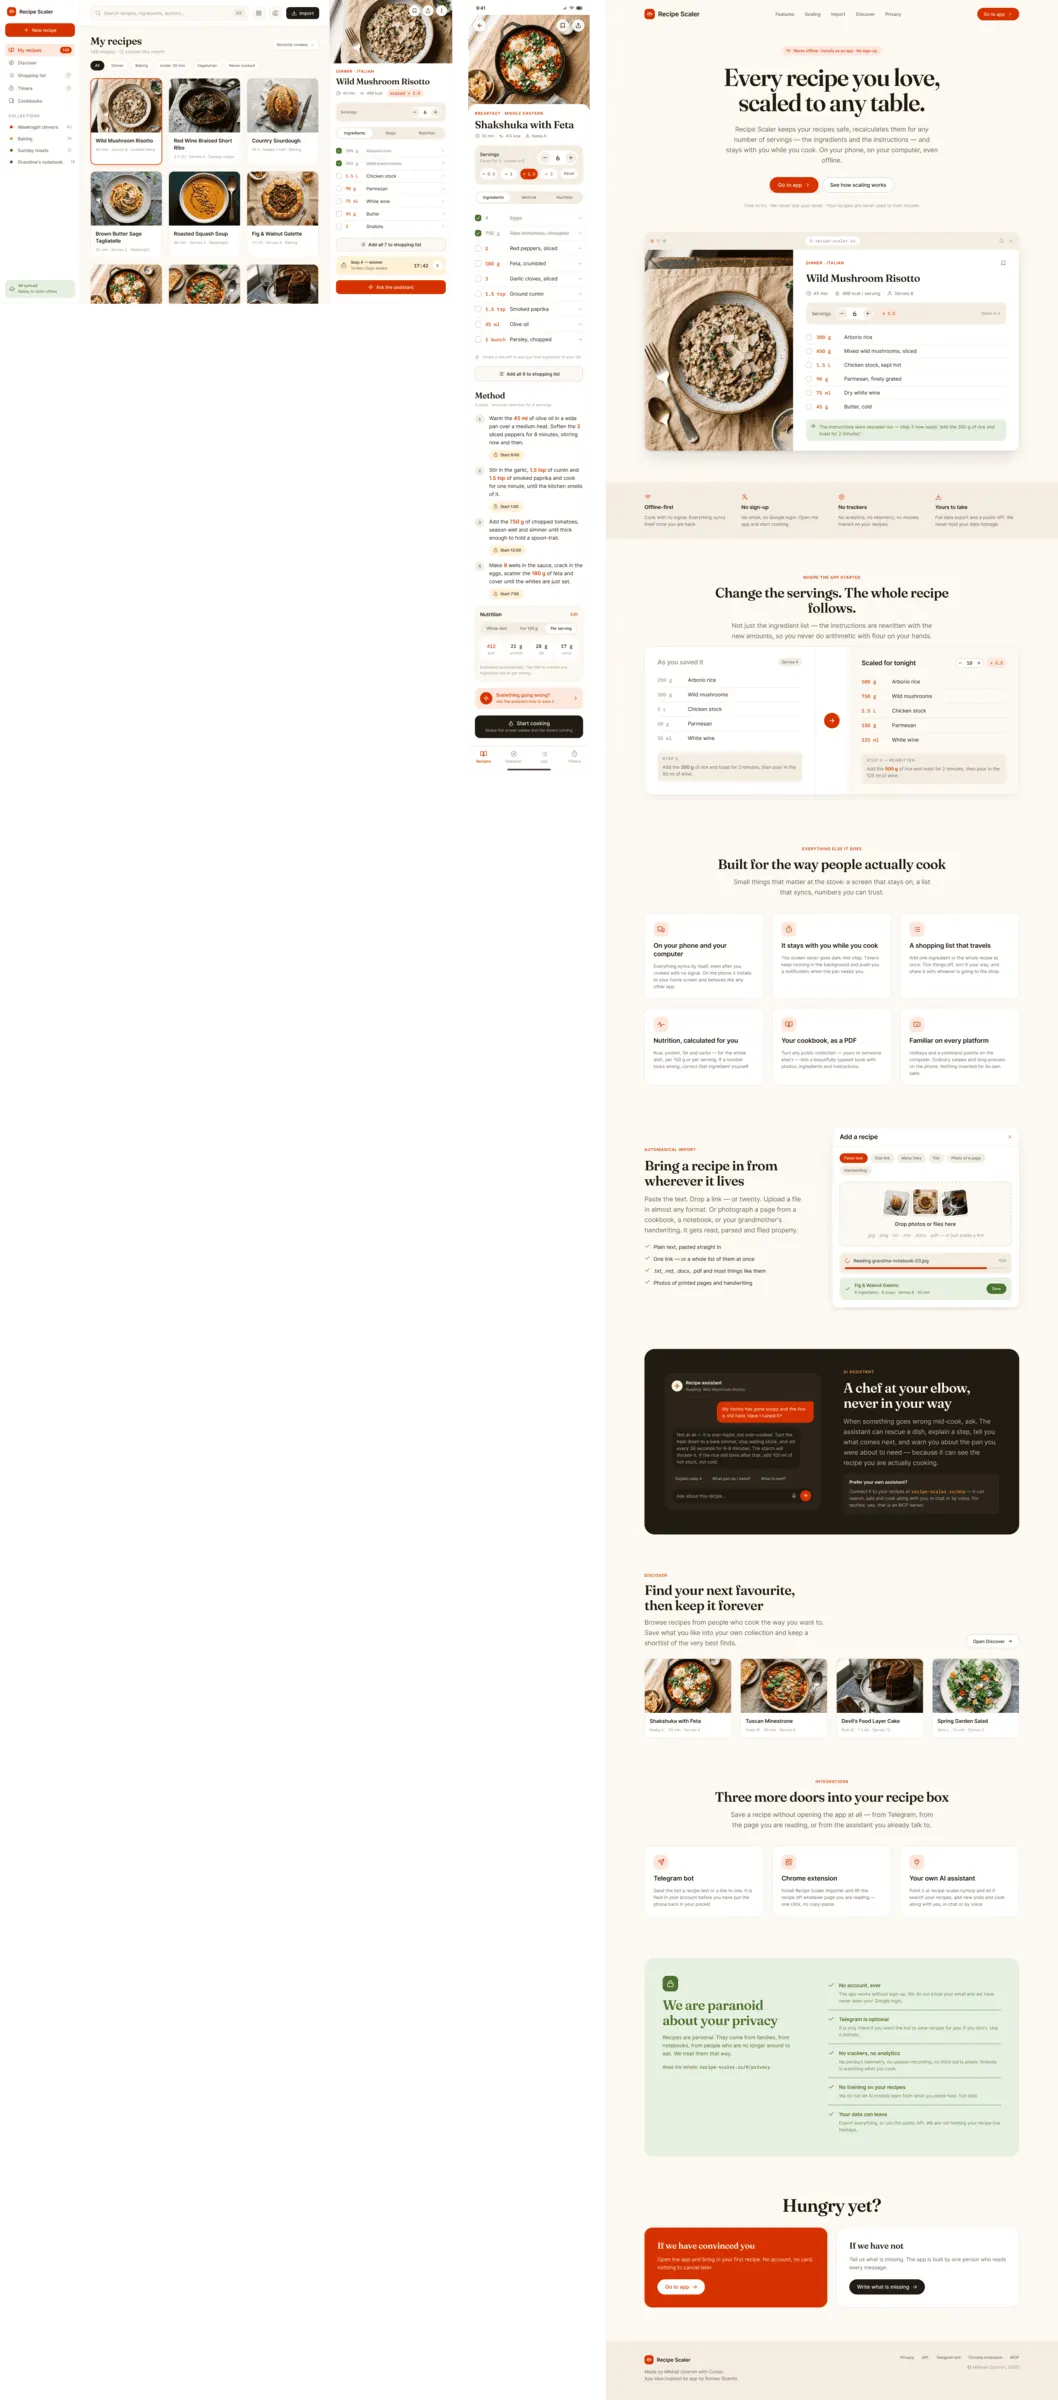
Typical Anthropic and Opus
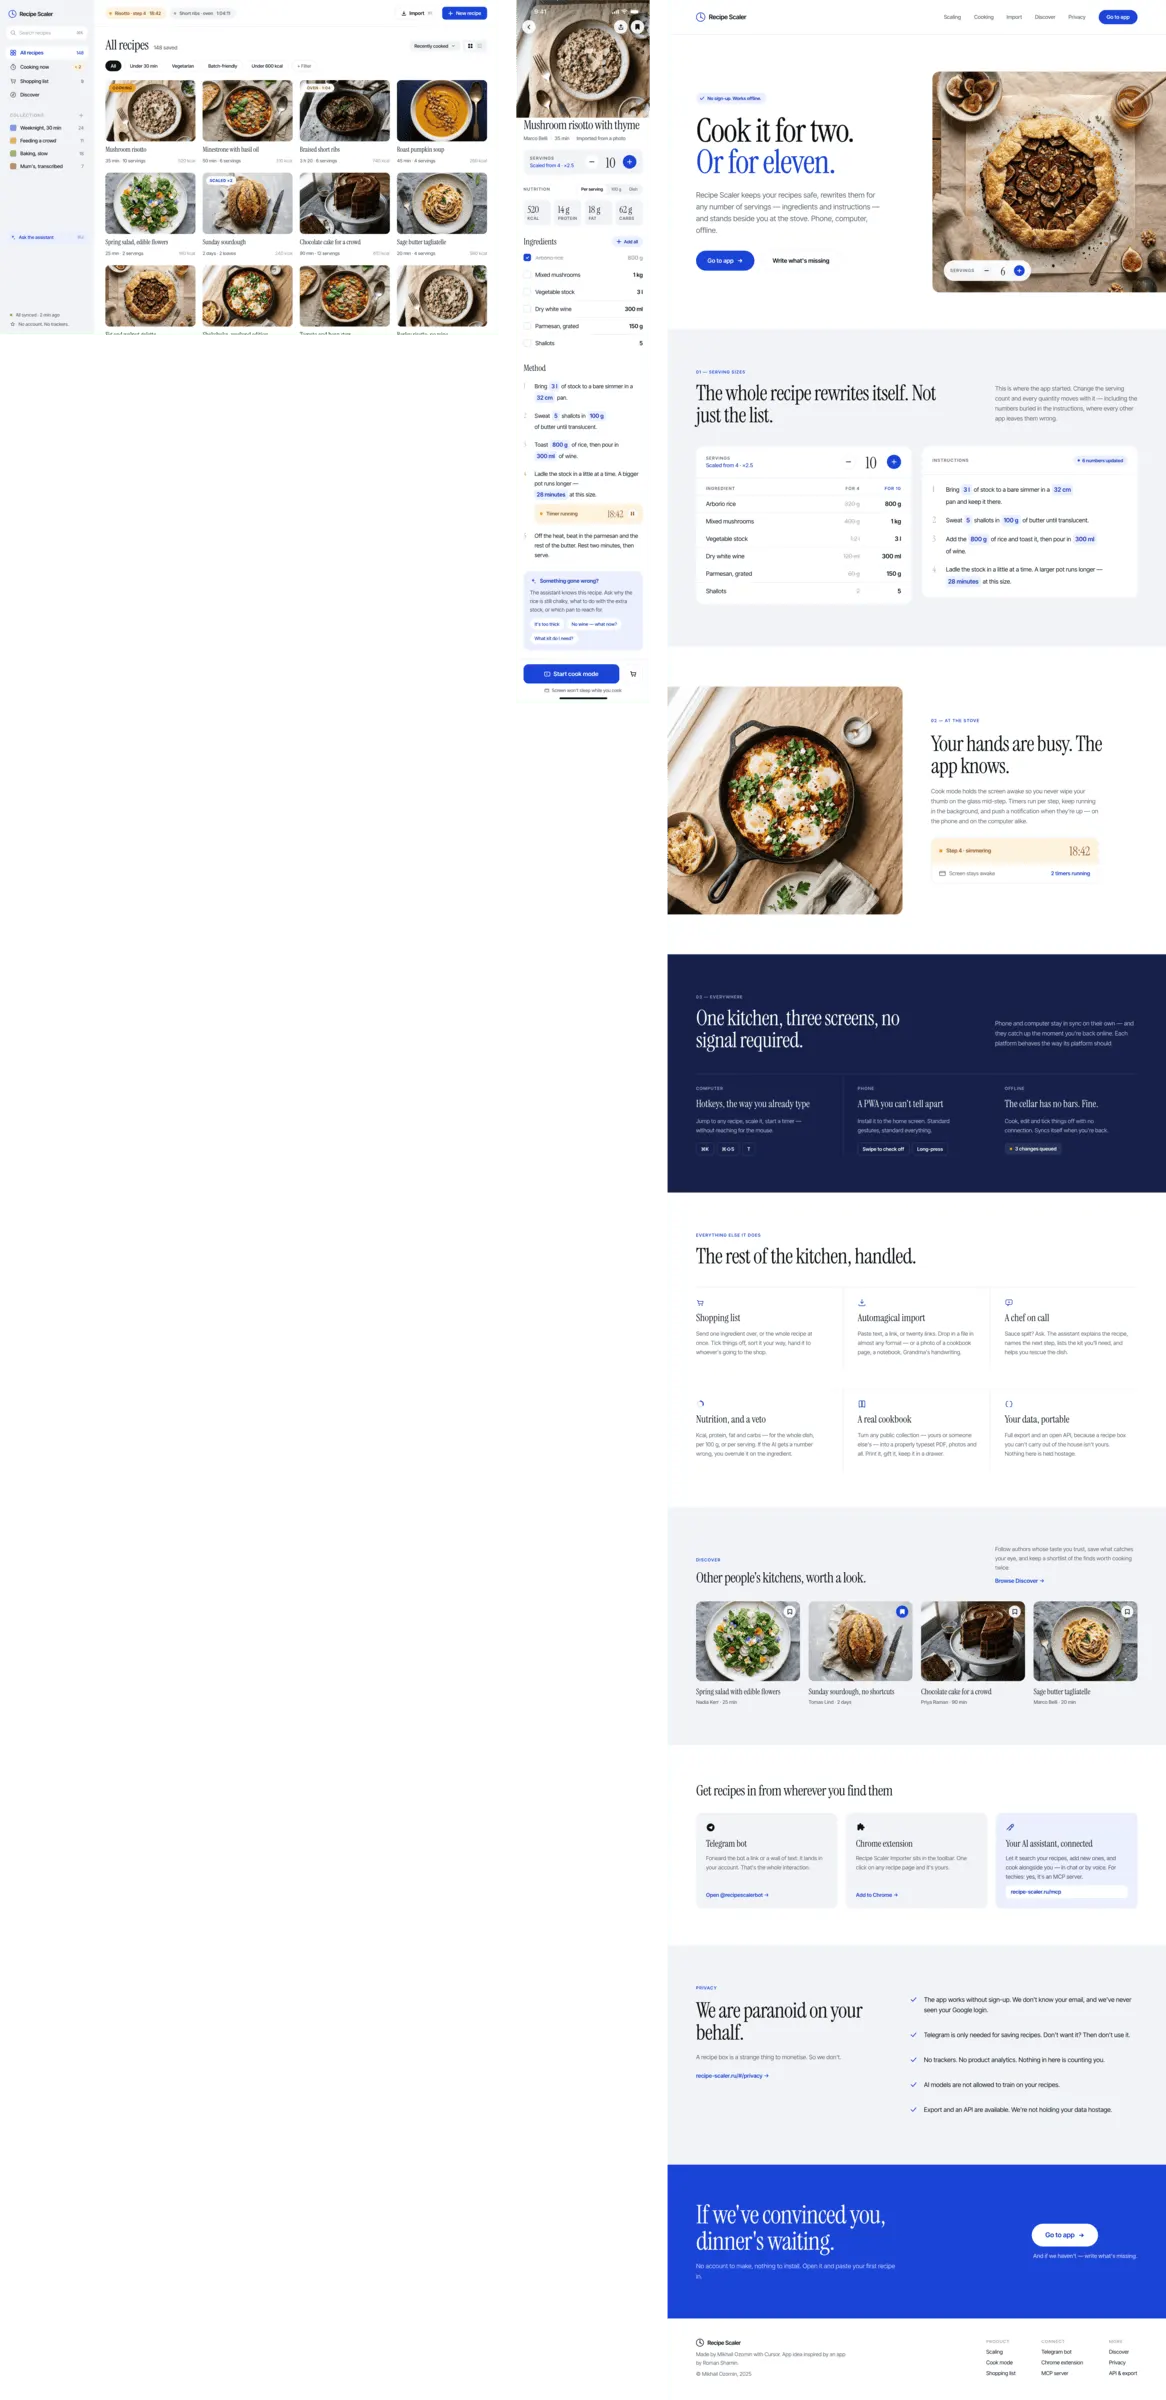
Typical Opus, very similar to previous generations. But the color is unusual — where’s the beige, Opus? :–)
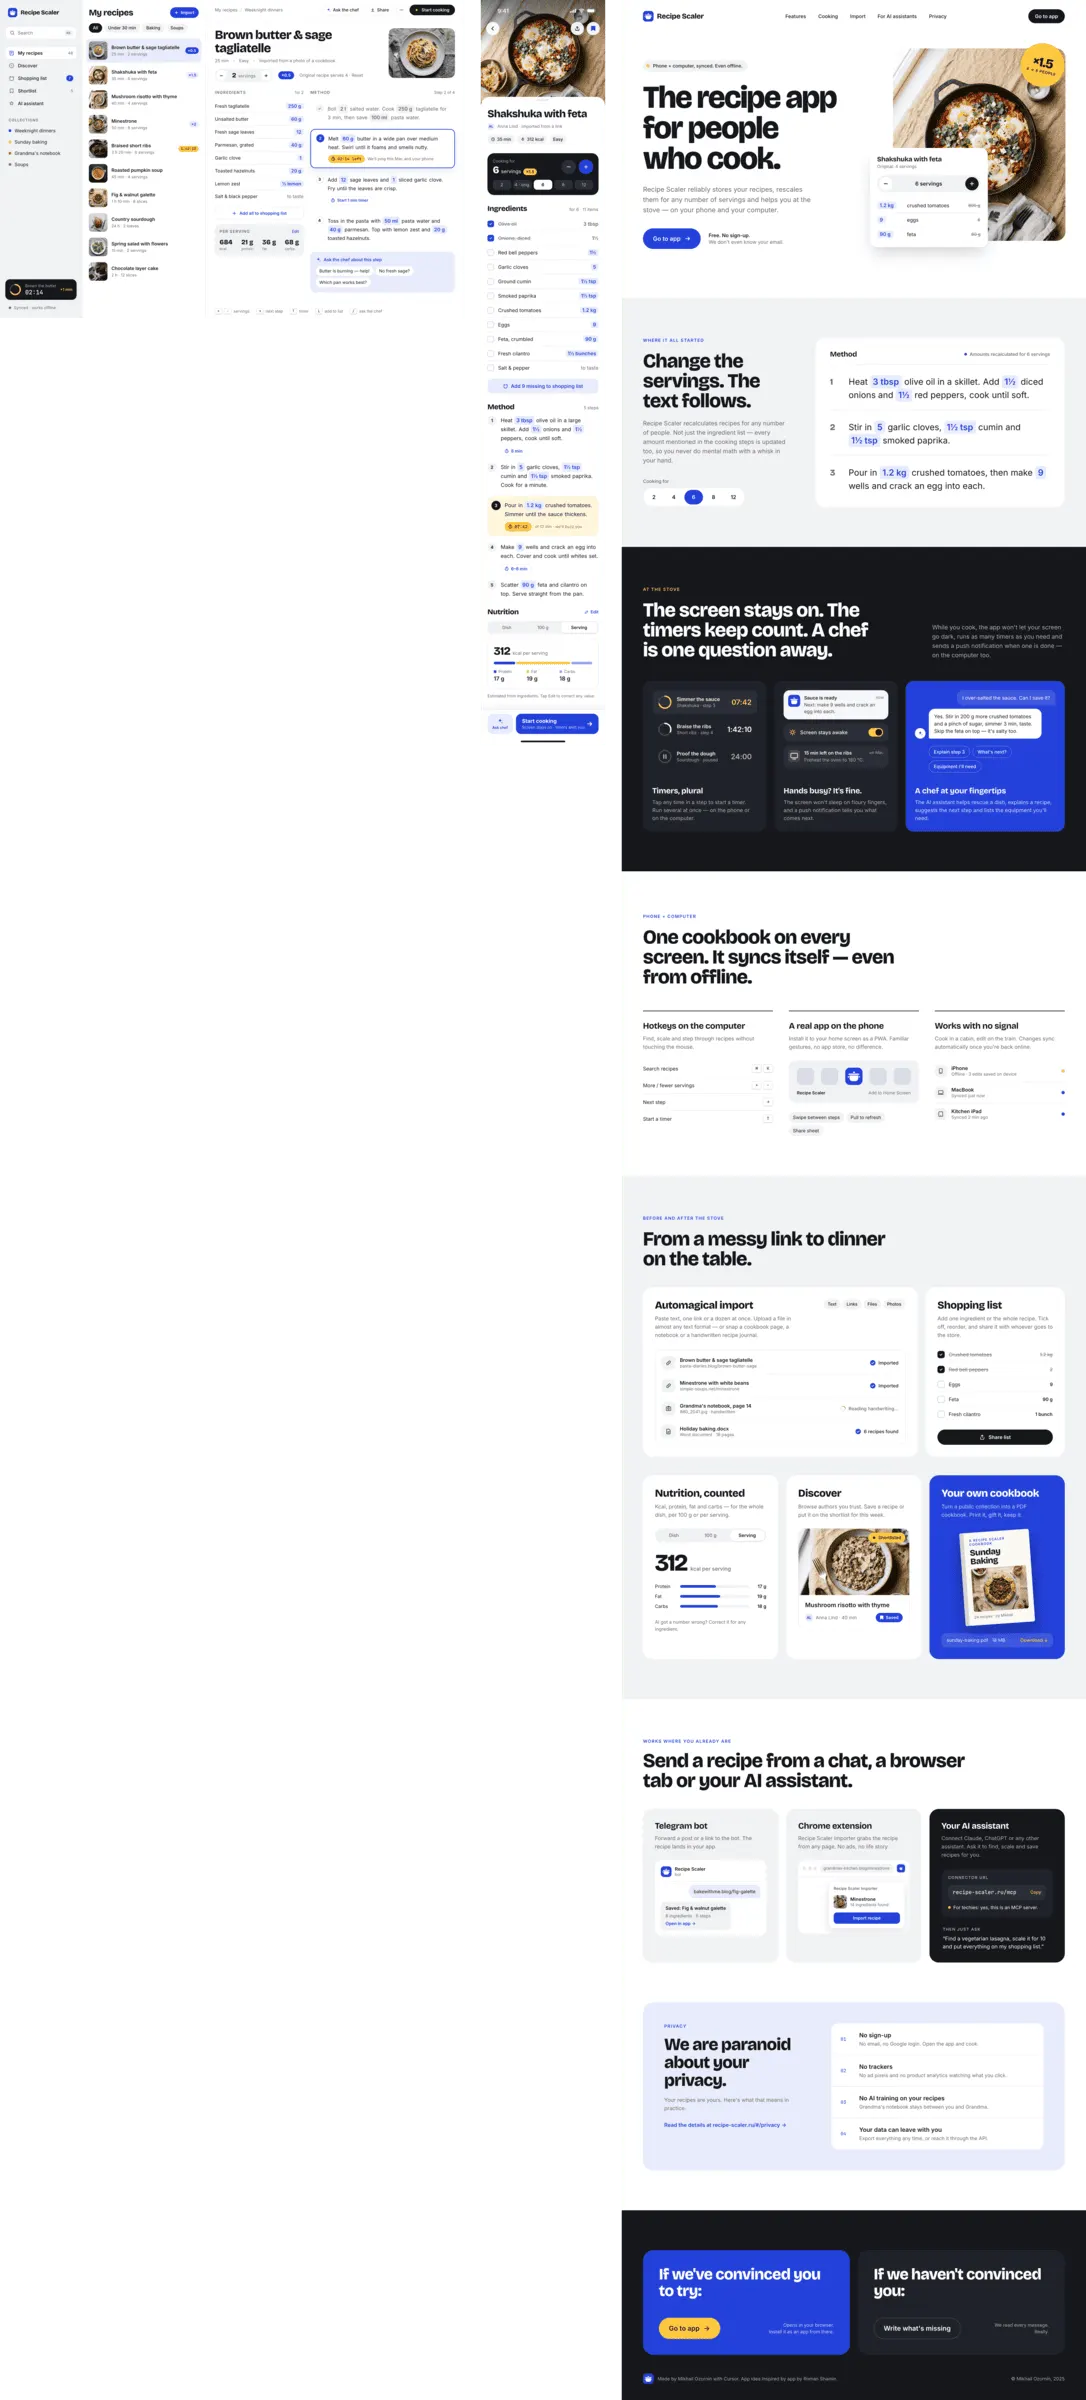
Very close to Opus 5.5 in Cursor. Probably a different set of skills and rules, since the copywriting here is noticeably weaker. But overall recognizable.
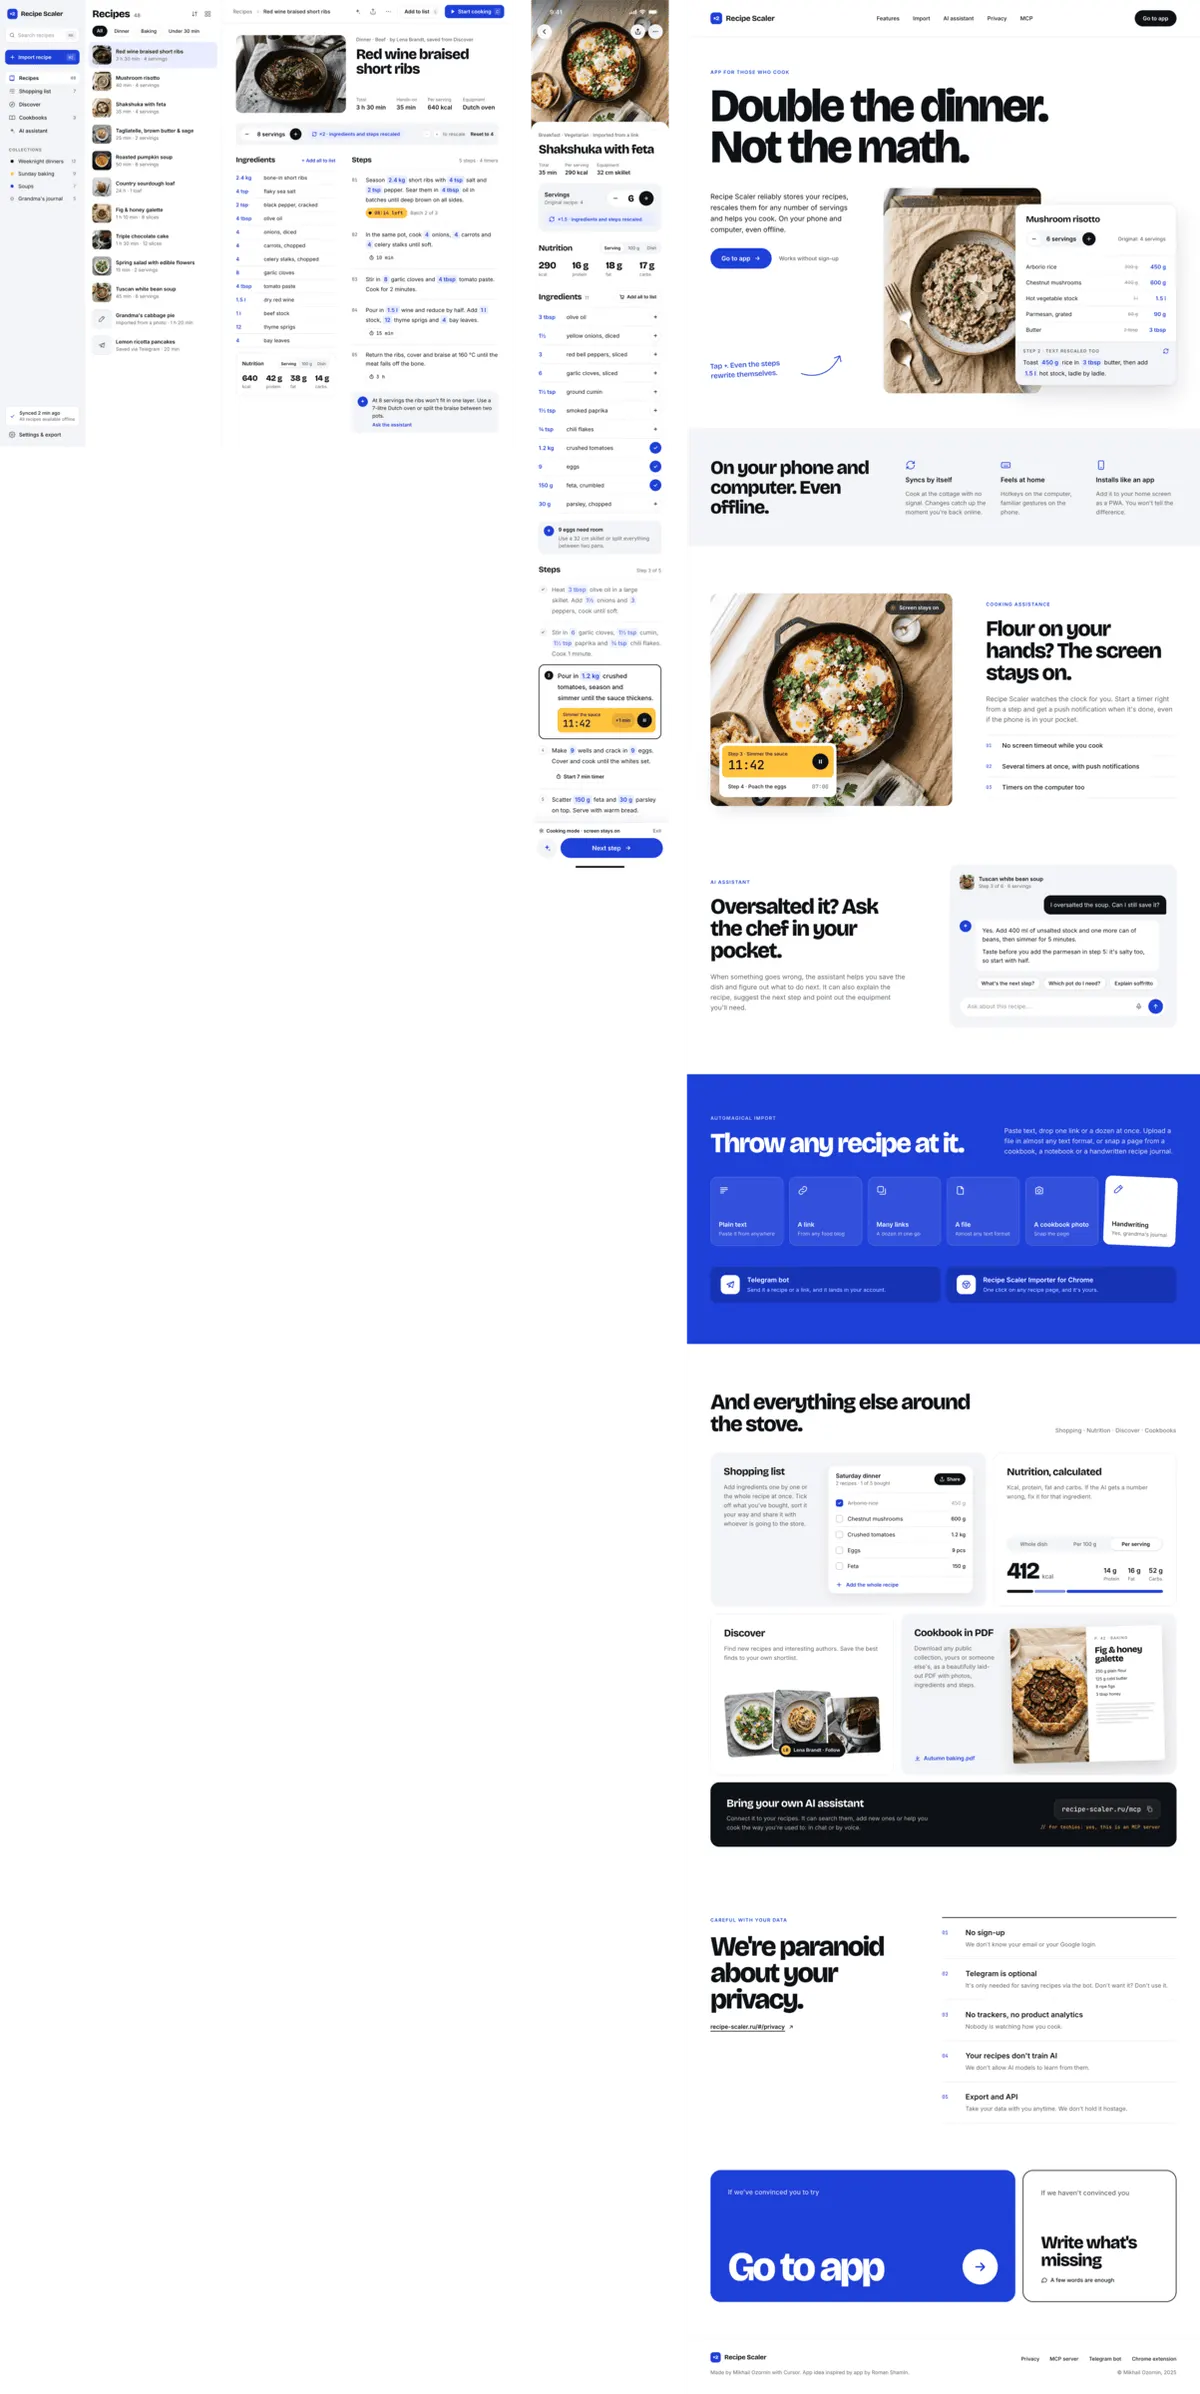
Really strong: right logic and accents, solid layout, visually precise, good copy (finally!). Looks like work by a very decent designer. There are small flaws, but I'm impressed.
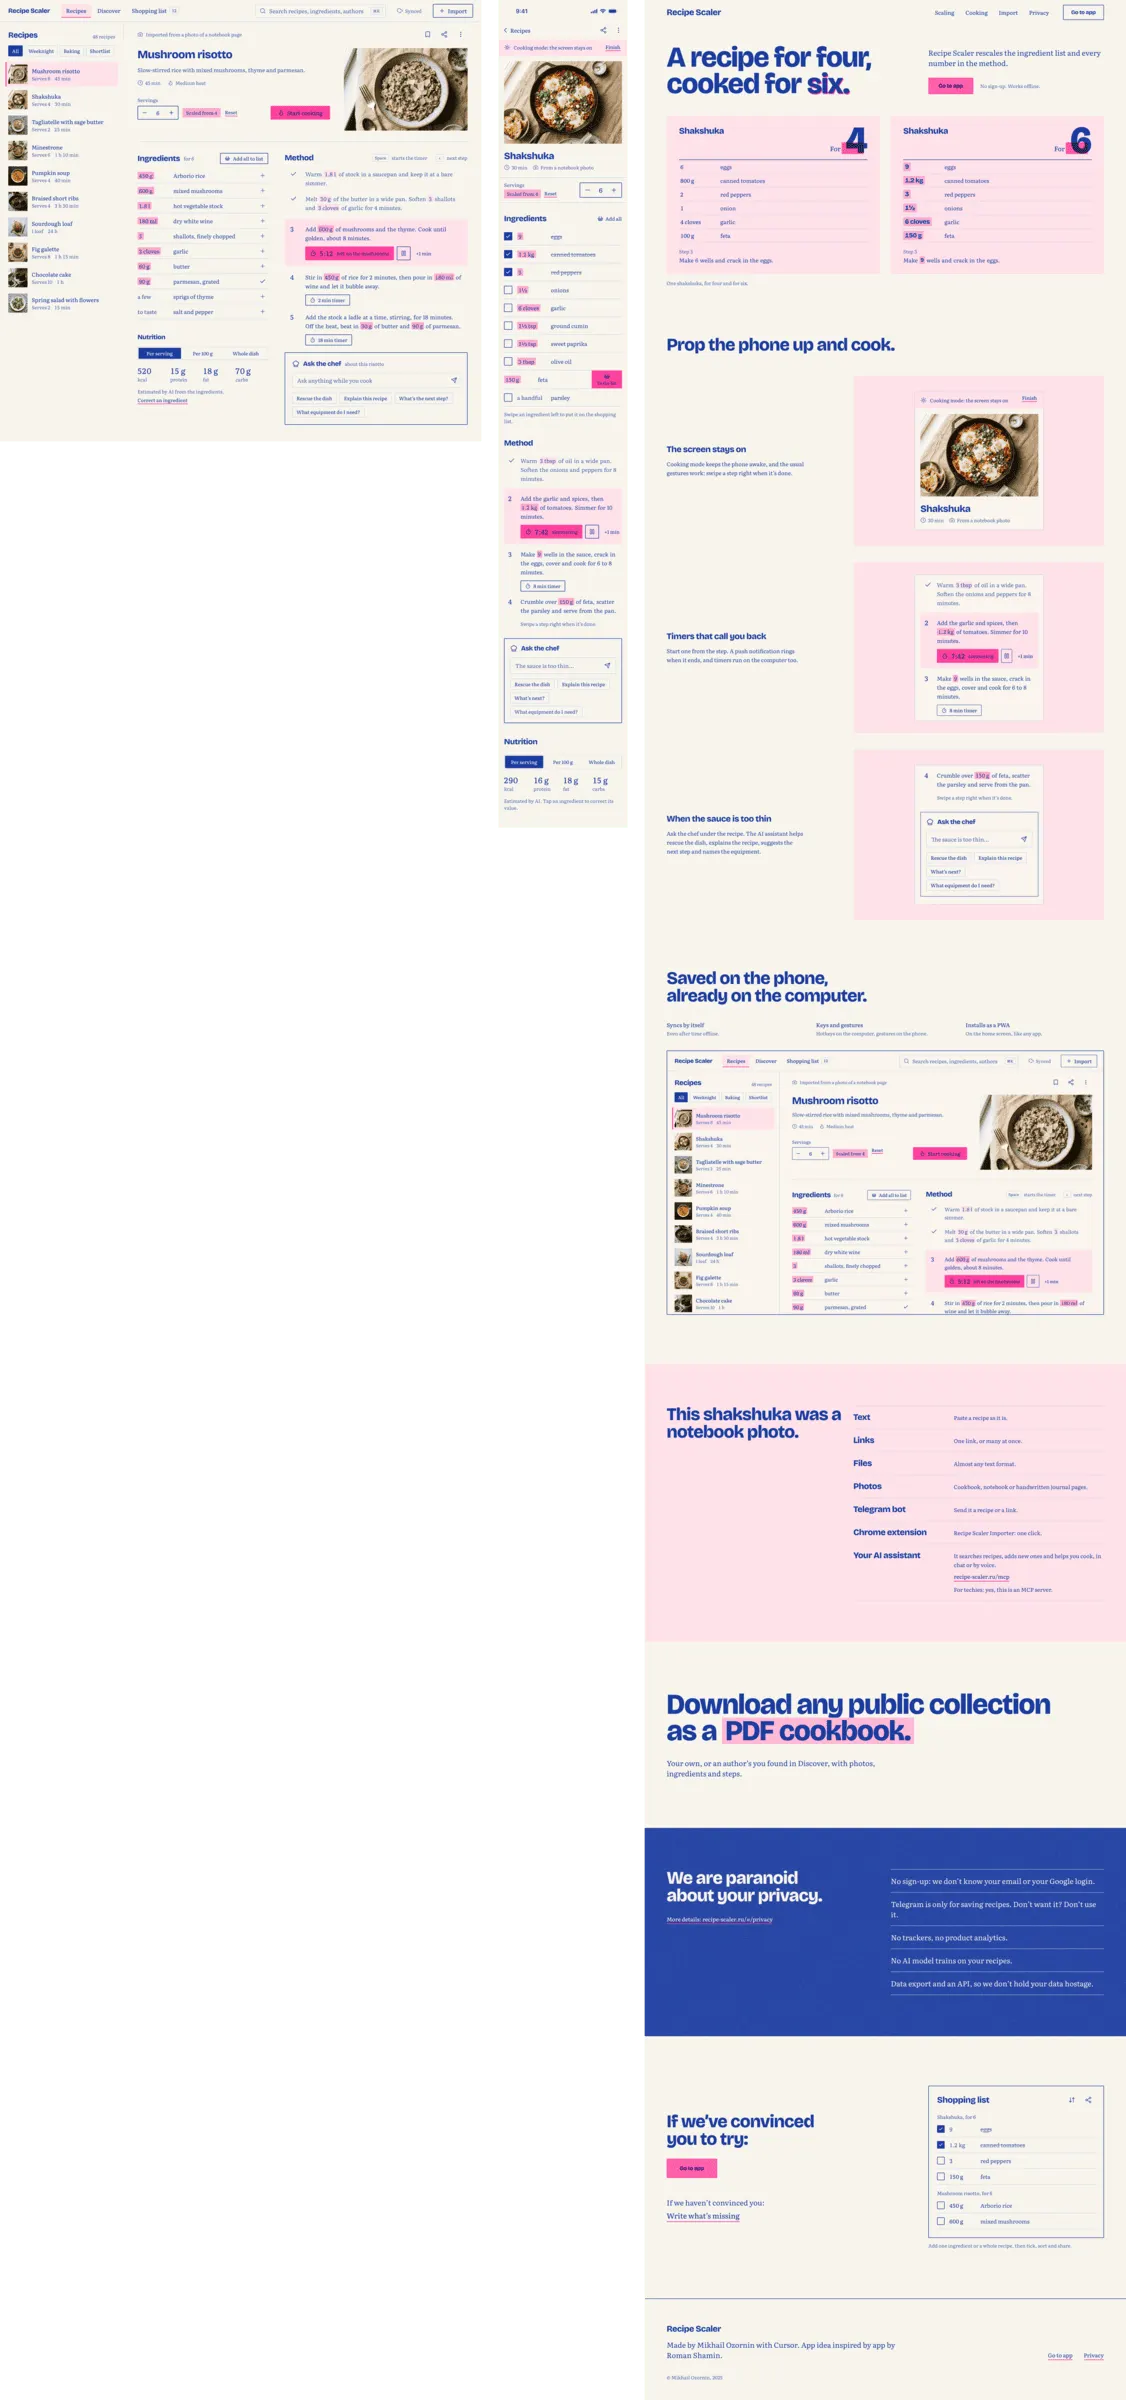
I did not turn off my main claude-md file, so extra verification loops may have run. The extra time and tokens may have come from it. Haiku tokens in this session: 15.6M.
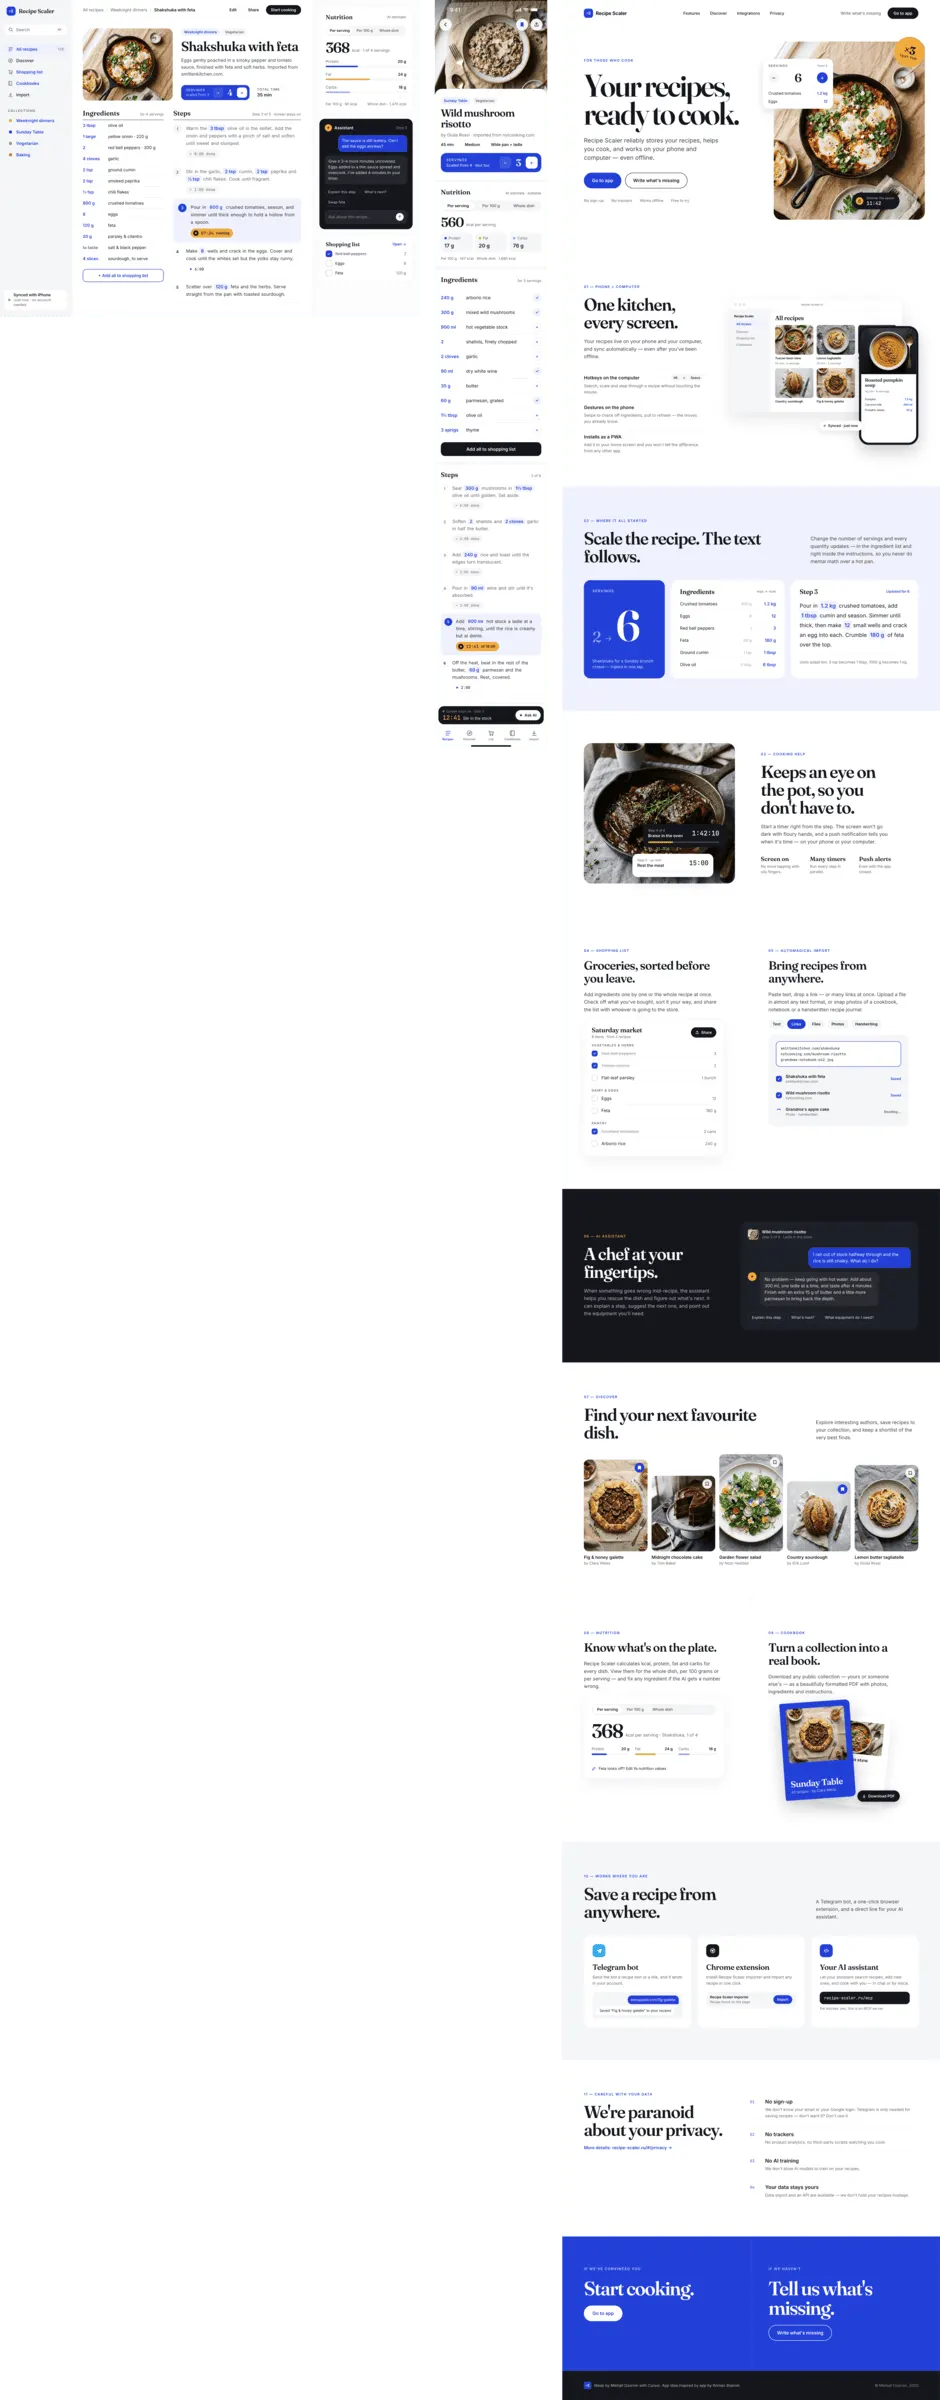
It really looks like Grok is running on Opus 5.5 right now. Very similar style, though the quality isn't xhigh — maybe the reasoning is lower.
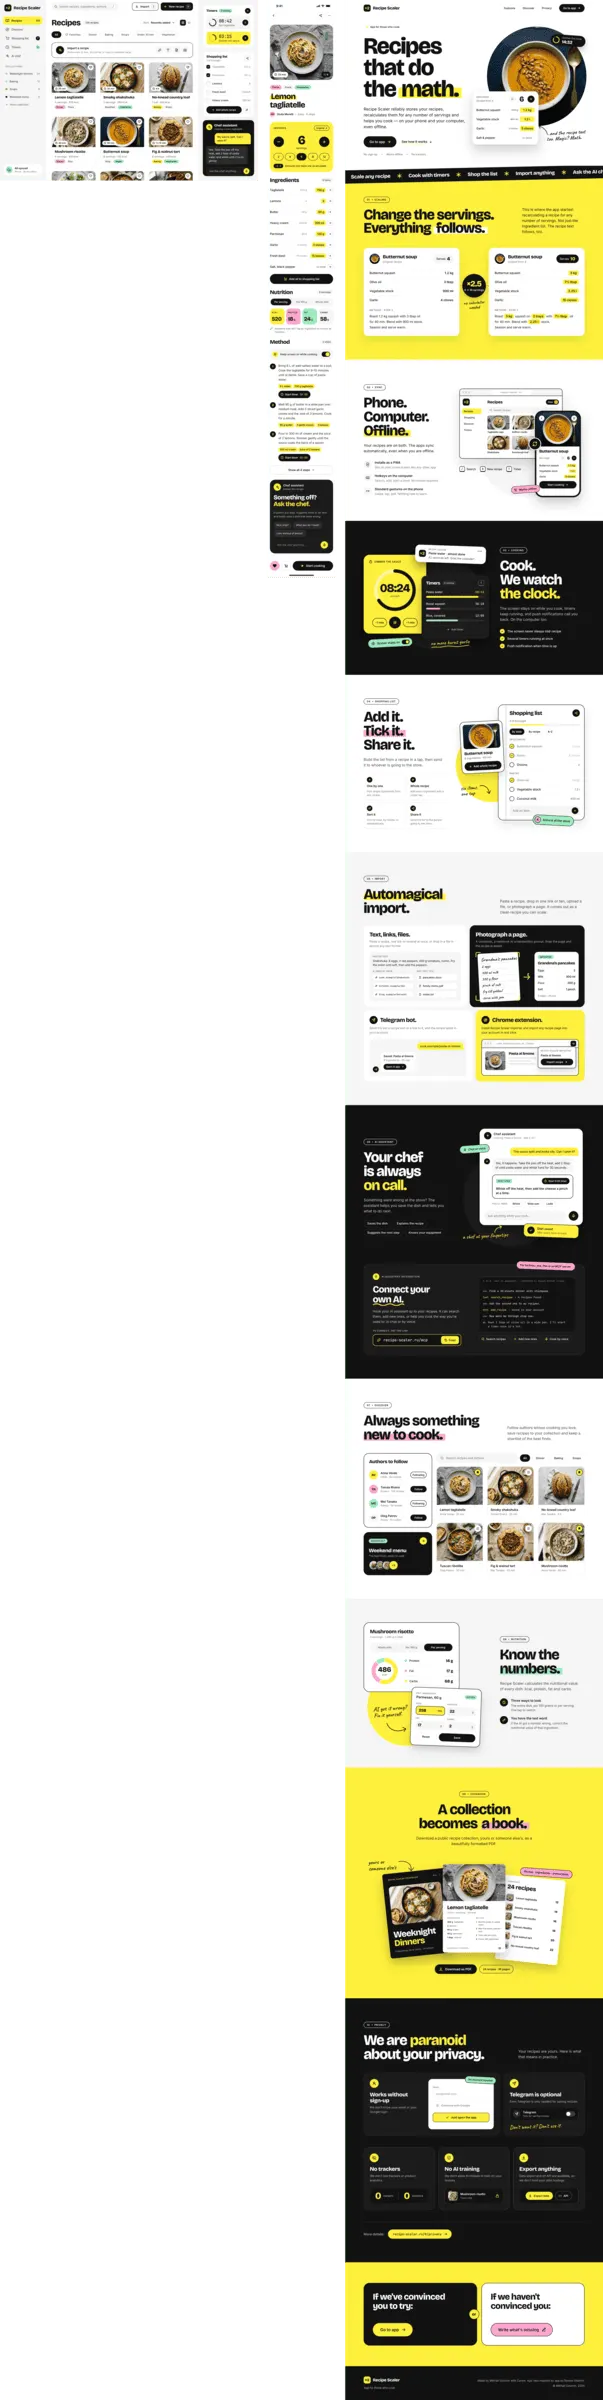
Incredibly slow, but it's max. Very good. Pleasant to look at, interesting to watch.
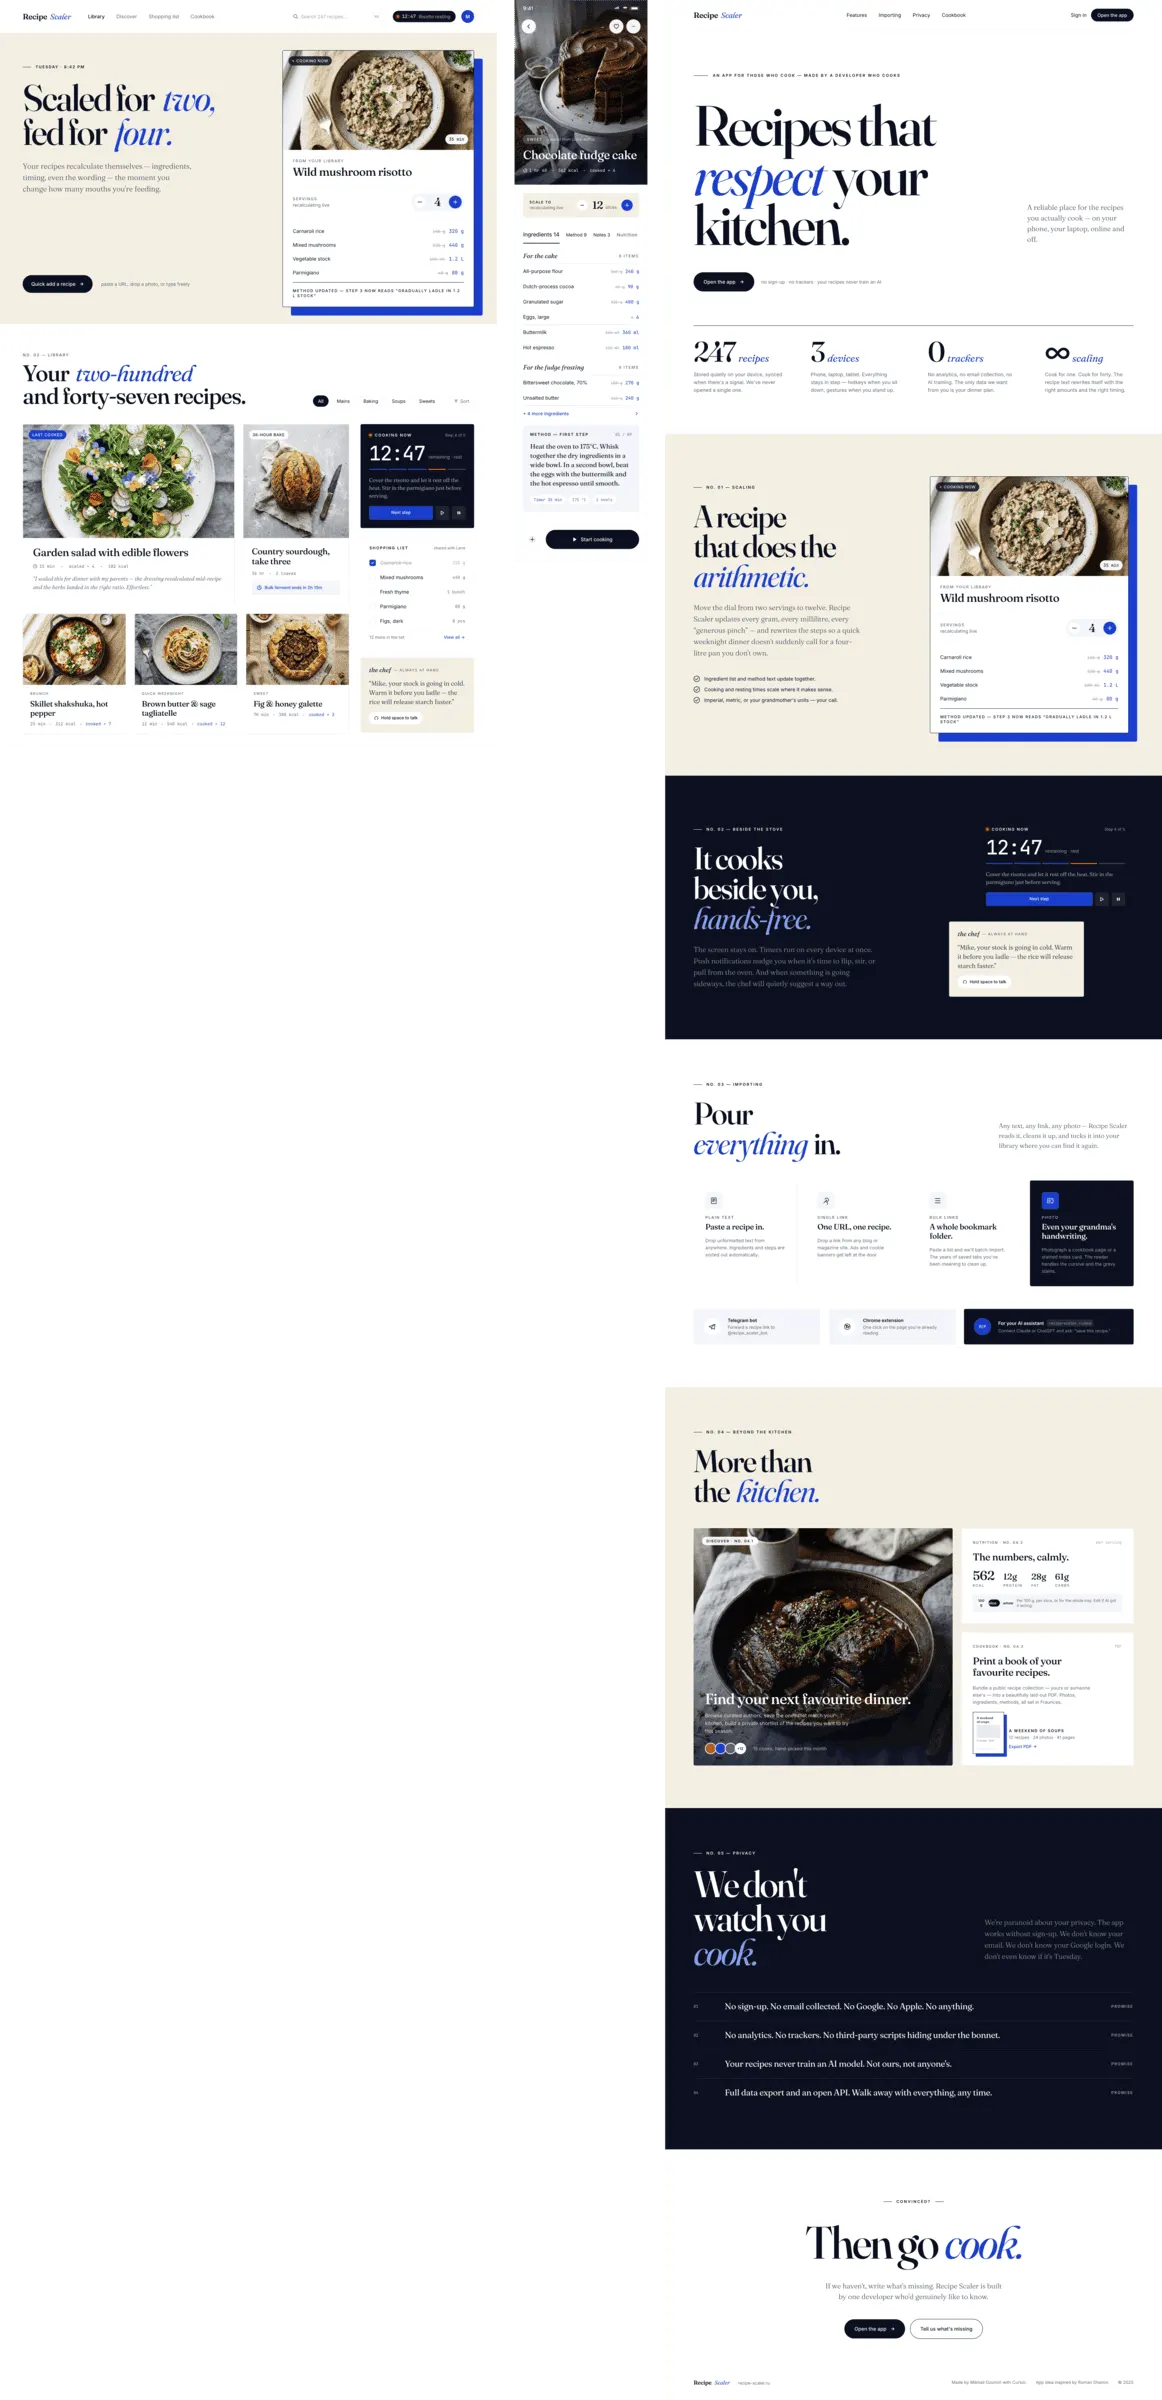
A surprisingly good result for Auto mode. The style choice is like from Opus
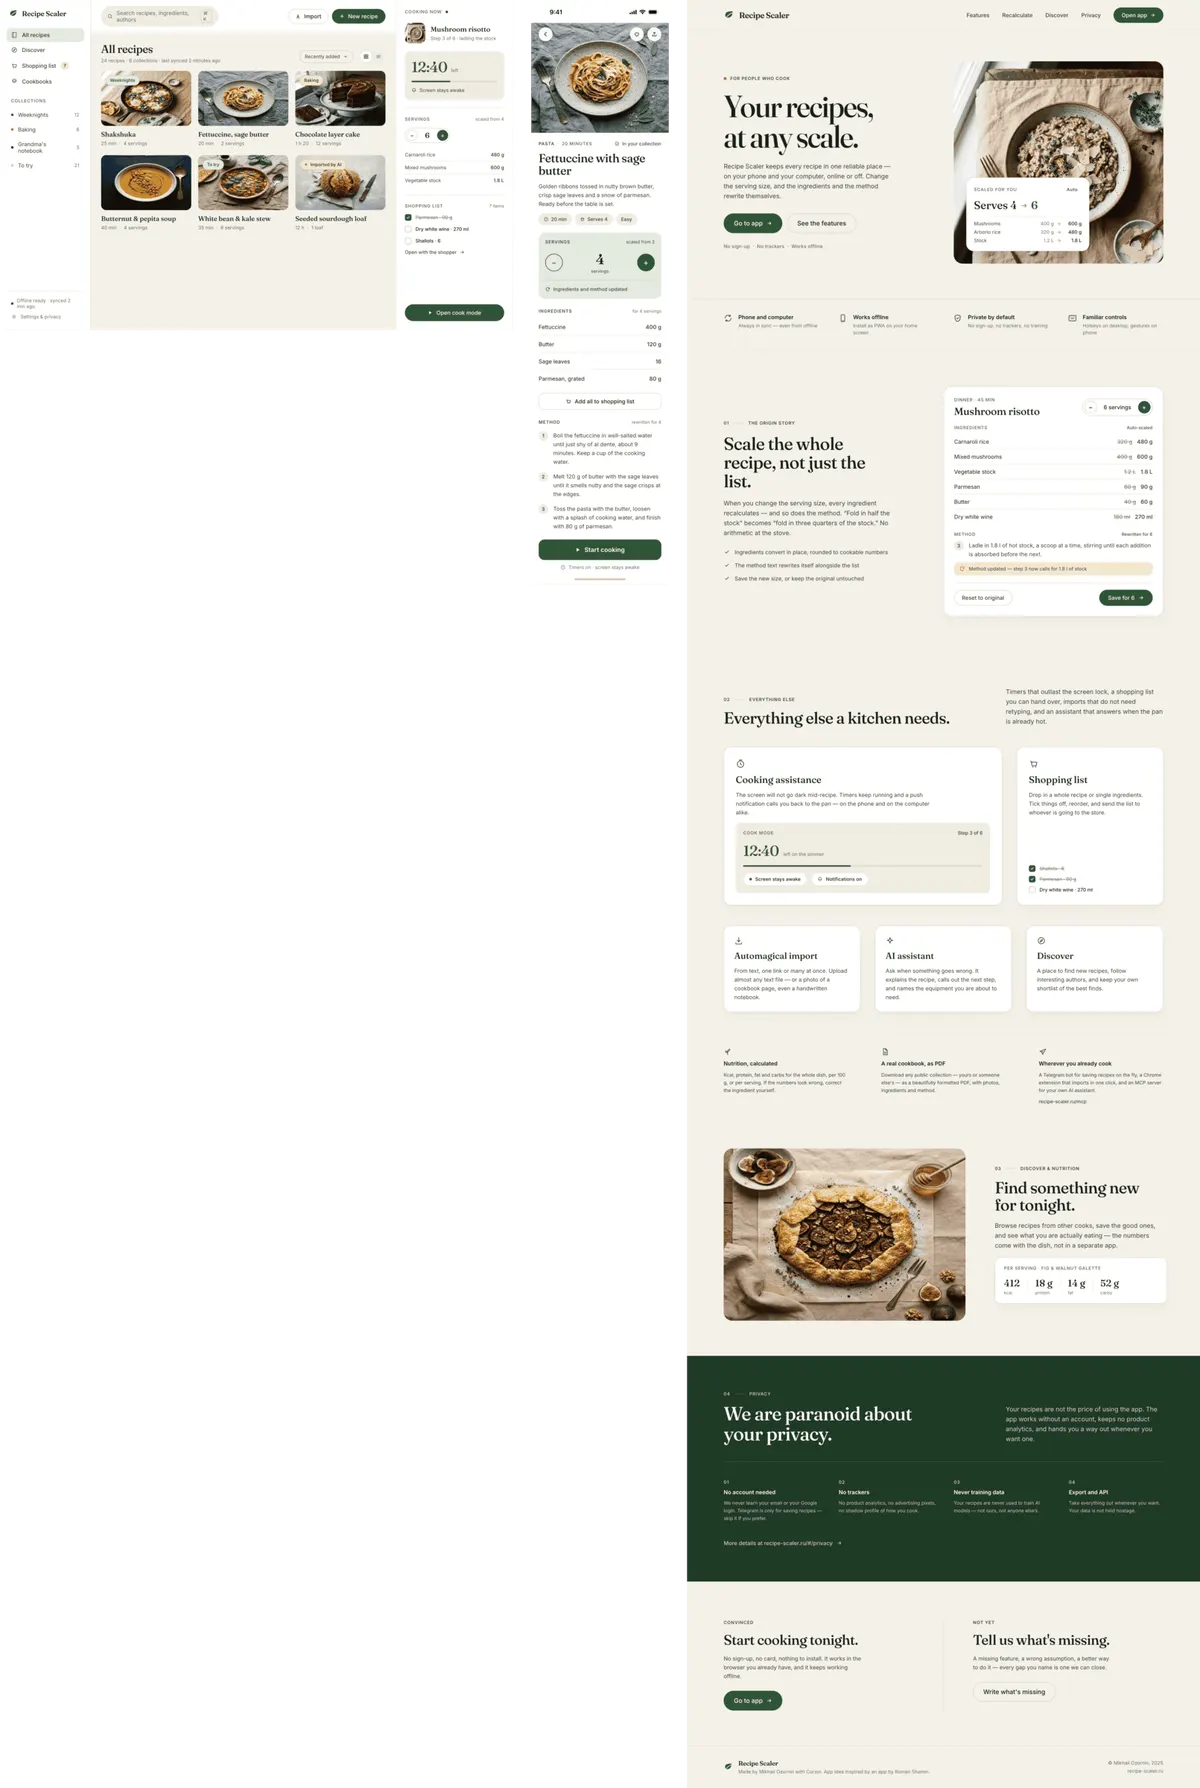
Slow, partly because the model did not read the images itself and instead reached for the available zai MCP server to analyse them. That would make sense for regular DeepSeek, but this one has vision. Lots of re-checking, as if I had typed /goal make the most fantastic design ever.
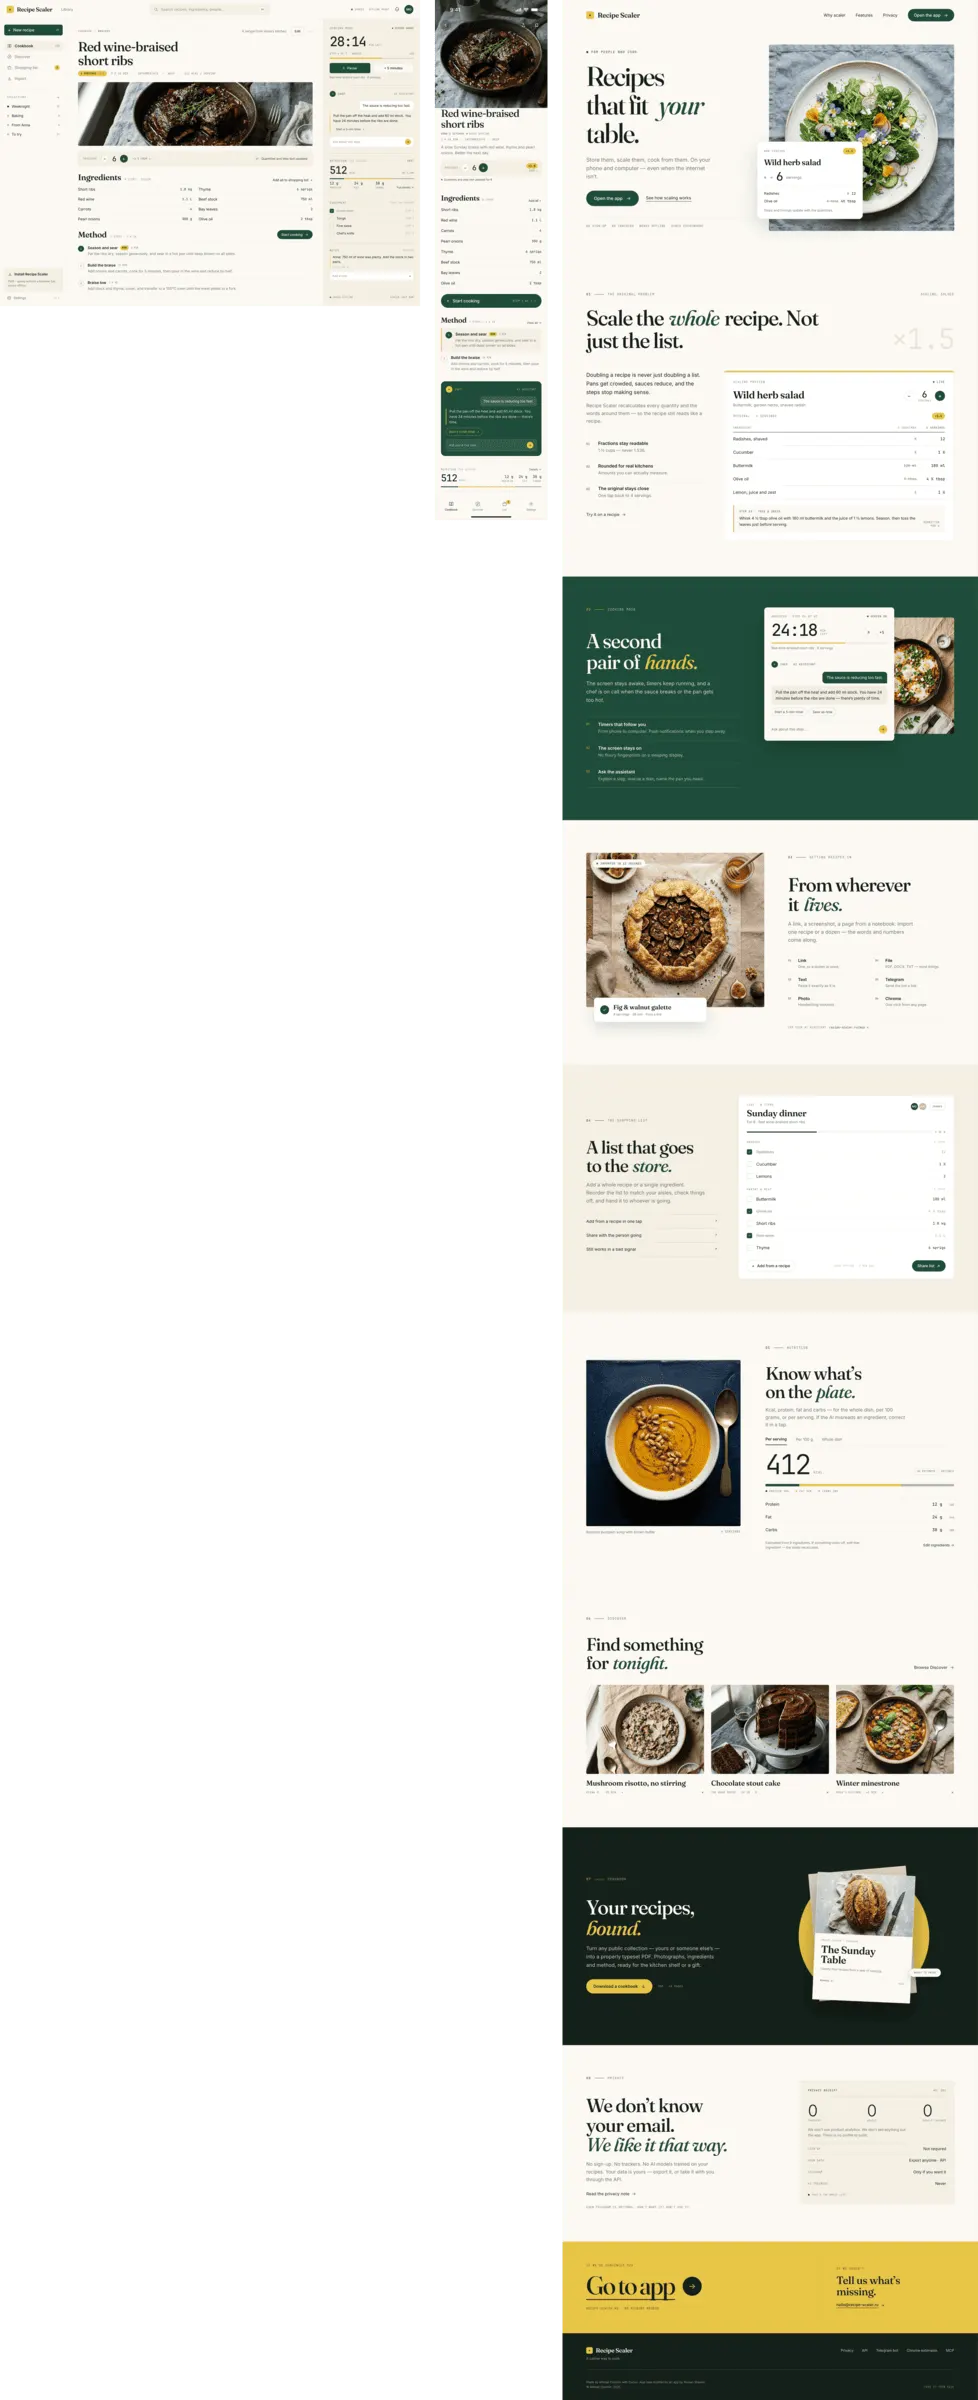
Cheap, but still weak design-wise. Fast, yet the total time ended up long: unlike the stealth models released around the same time, DeepSeek built a long, complex page on 21.6M tokens. Visually weak and the desktop is overloaded, but the desktop-interface task was understood correctly. Insane cache hit rate — 99.29%.
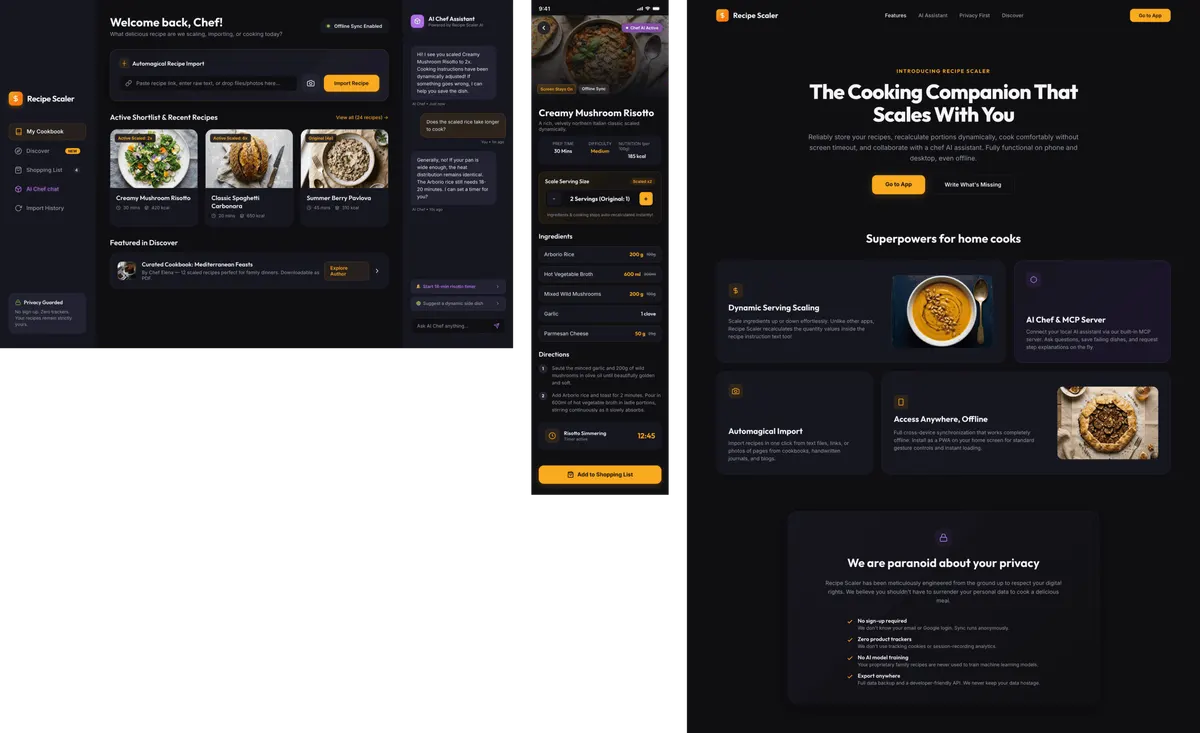
Noticeably better than Gemini 3.1 Pro. The only one who decided to do a dark mode.
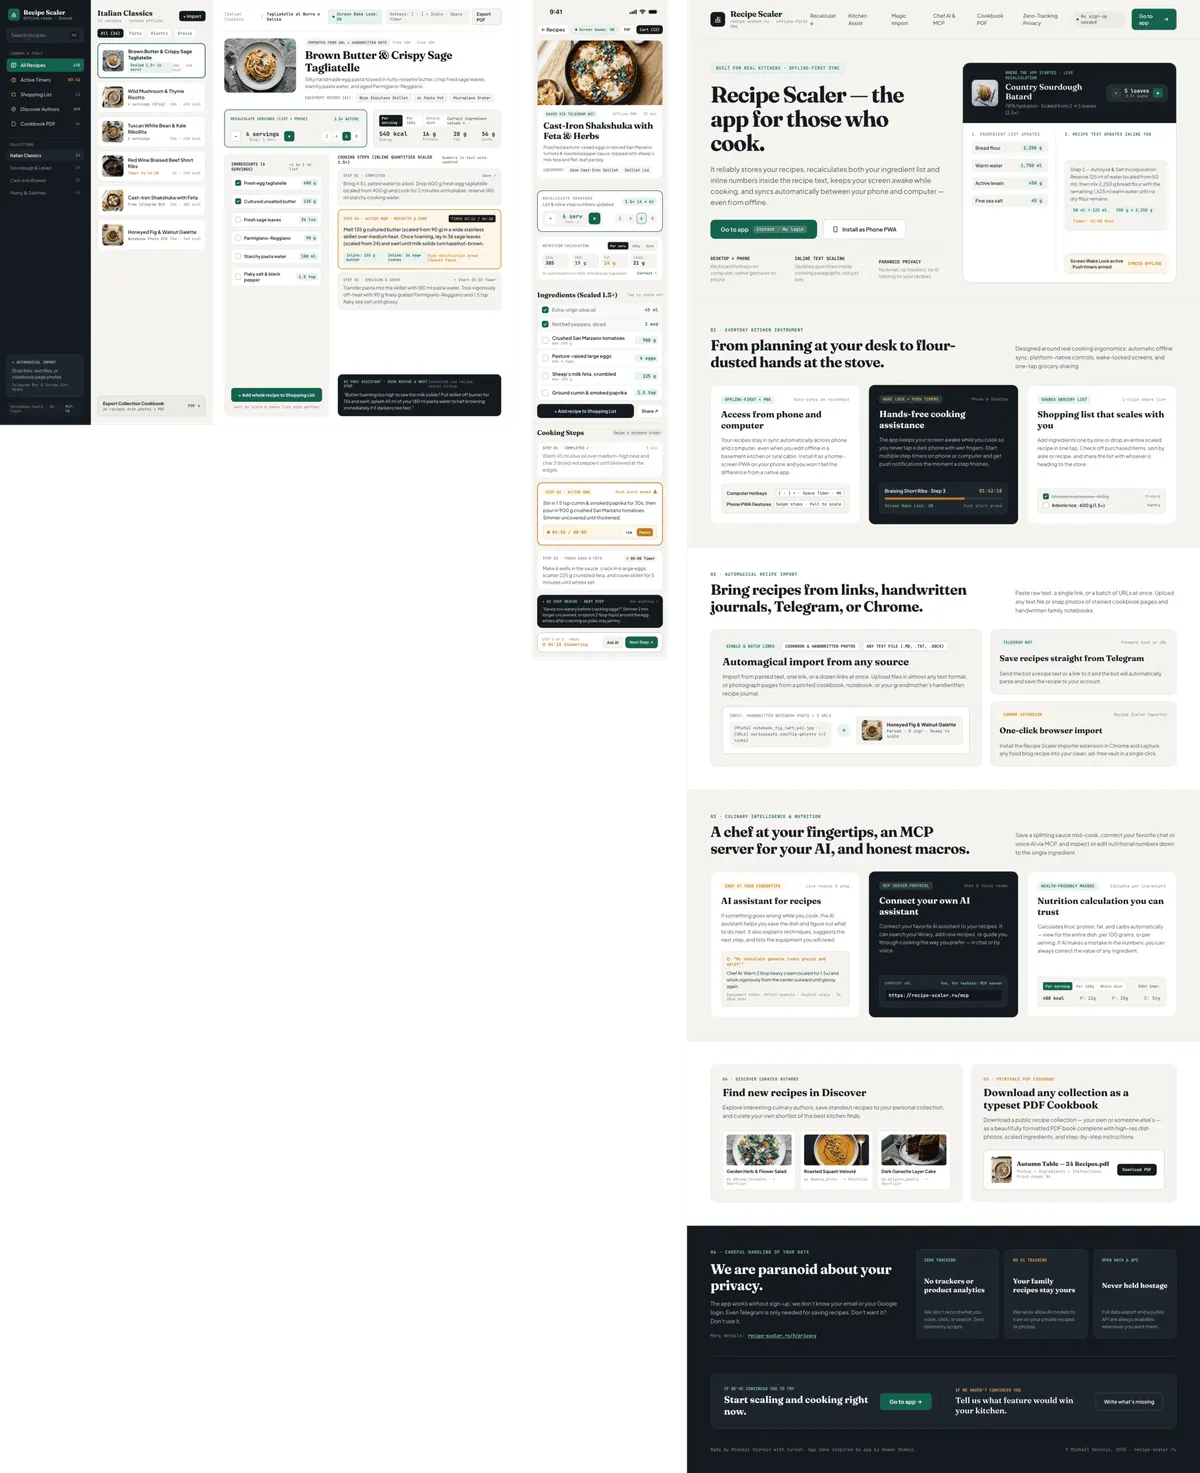
Very AI-sloppy overall. Feels trained on B2B products — packed with everything, built a spaceship, wildly overloaded everywhere. The “interface” concept is generally clear, though. The promo page is very bad.
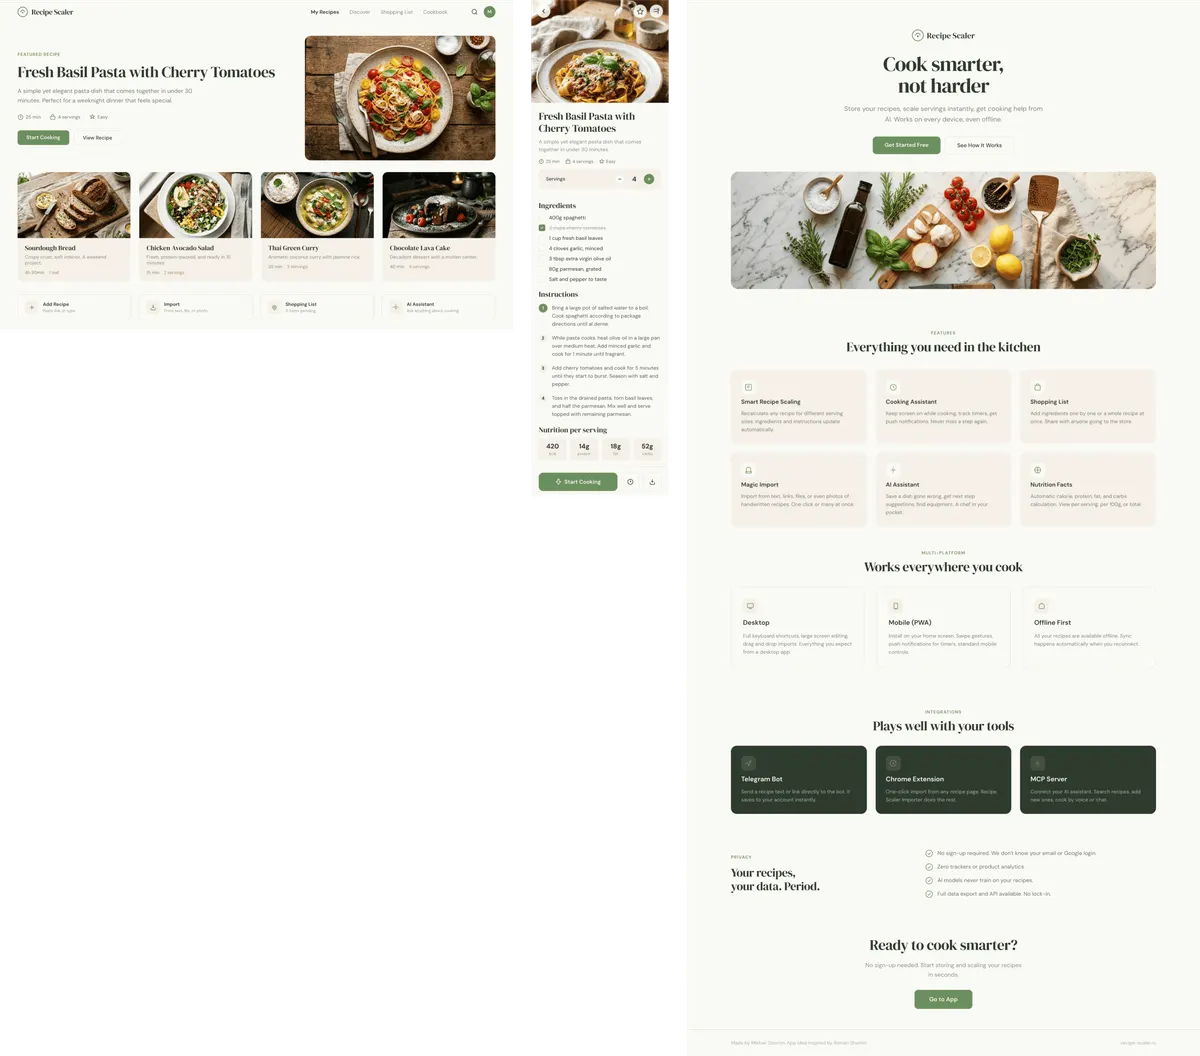
Unlike Cursor, Opencode got something out of GLM — OK for its price
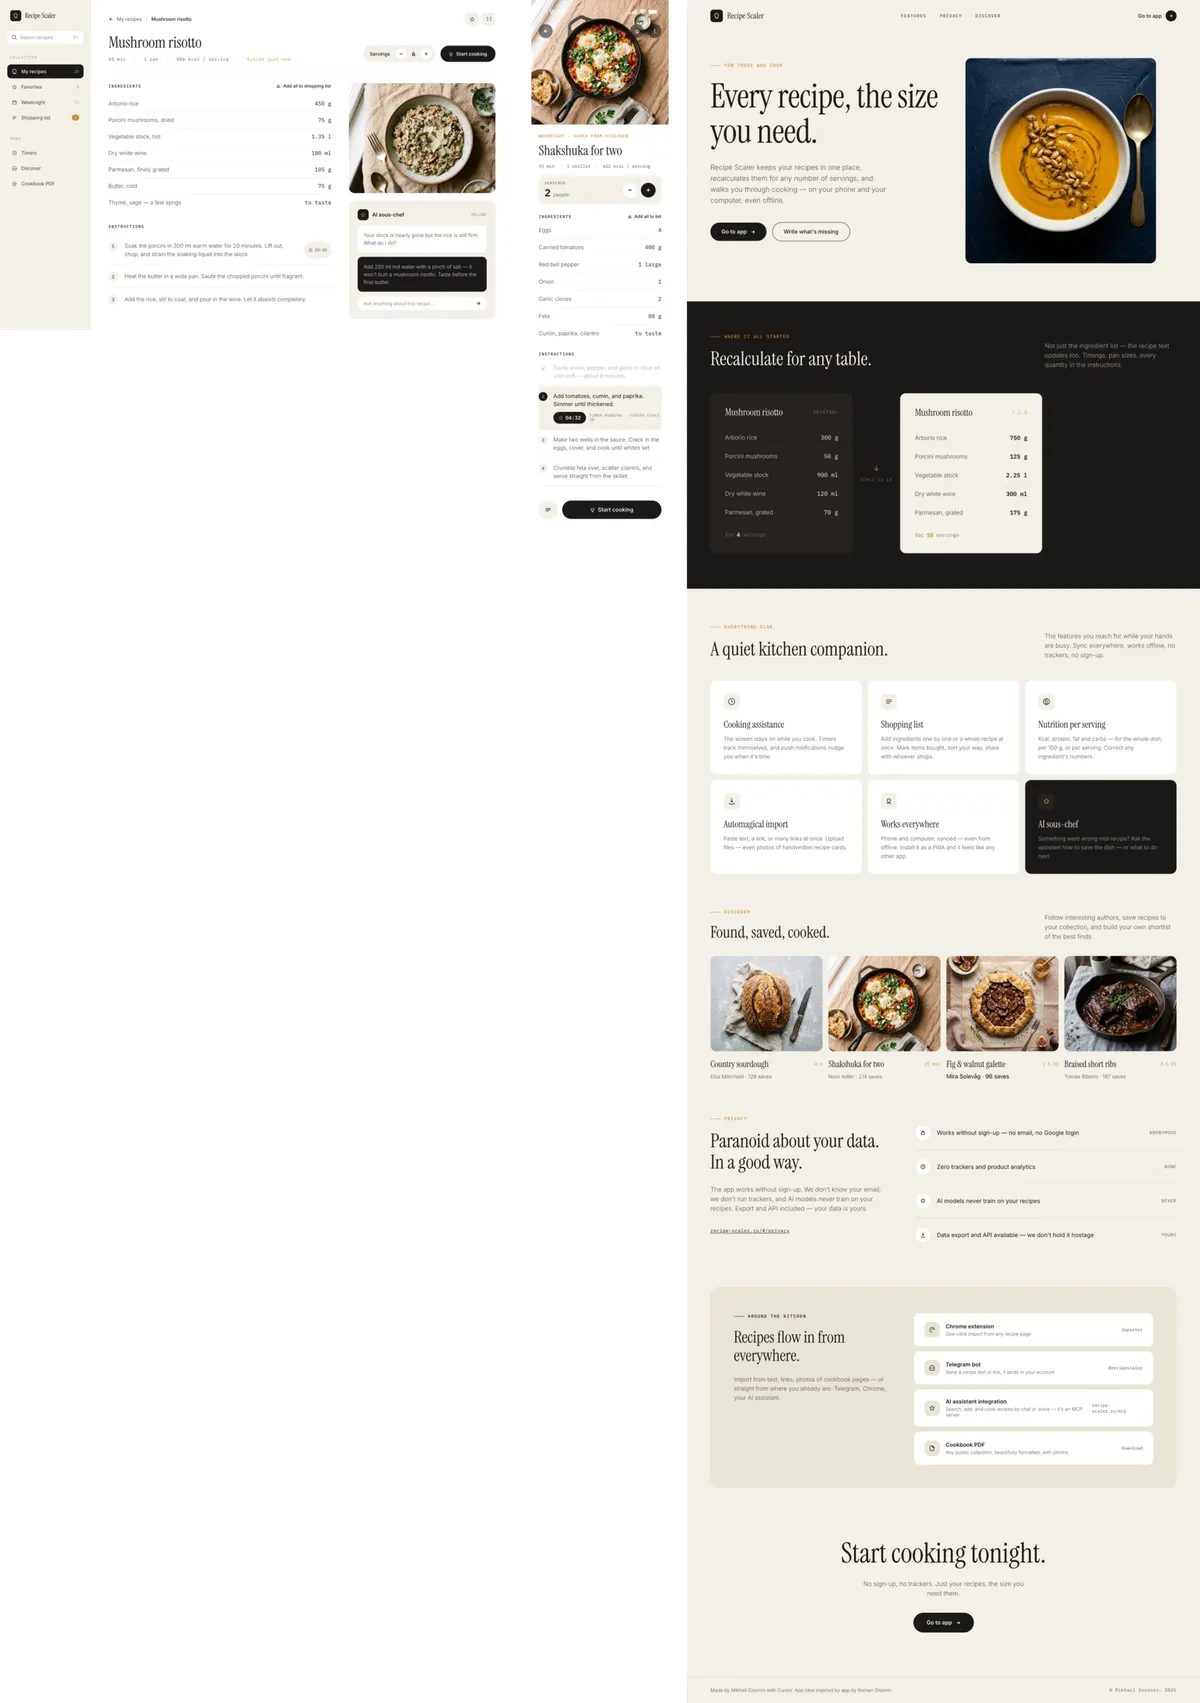
Clearly much better than GLM 5.2, which couldn't even use tools properly for me (will rerun it). Spent the first 10 minutes studying images via zai MCP; the model isn't multimodal.
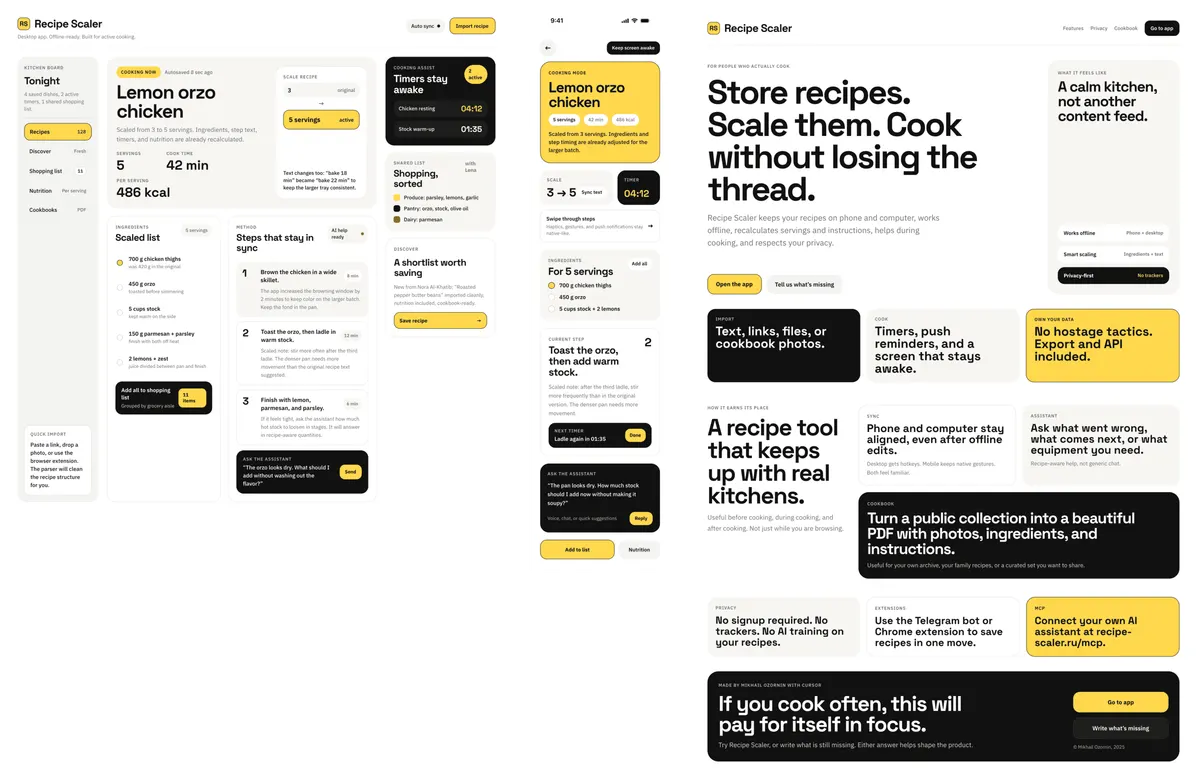
Surprisingly, I like this variant even more than GPT 5.5
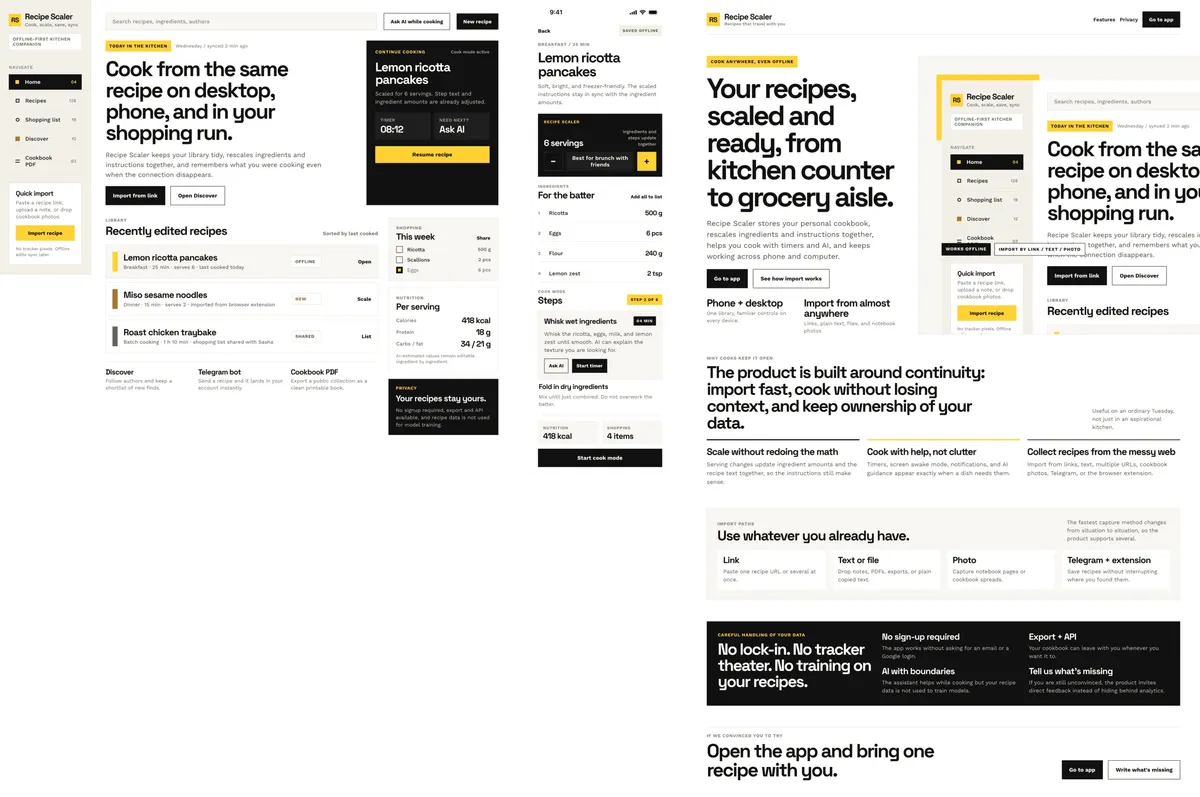
The agent is different, the model is recognizable. Slightly better than in Codex
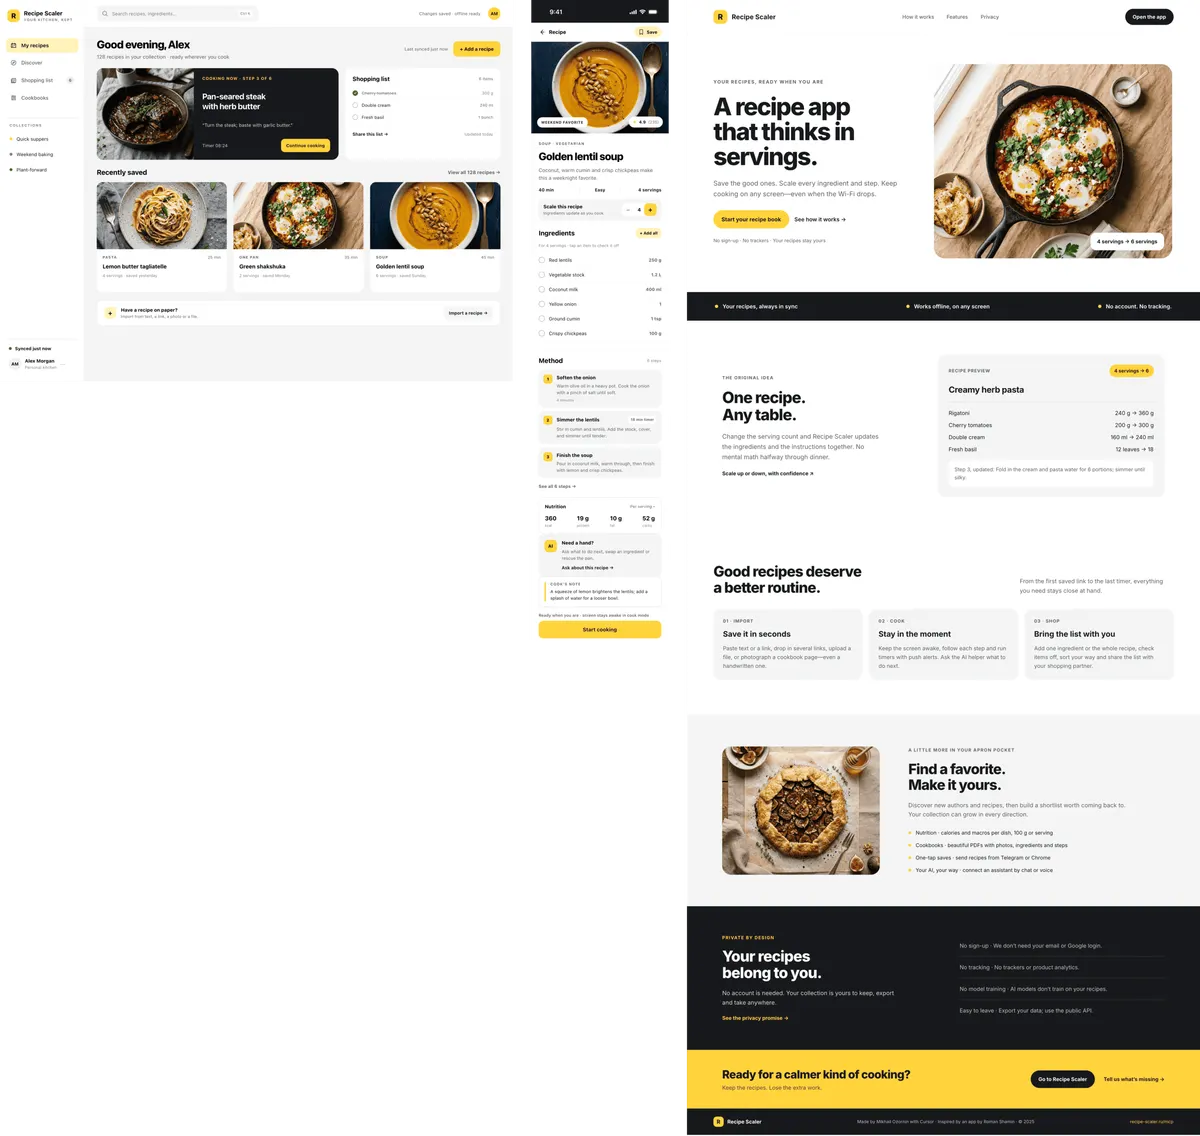
For Luna's price — a delight. Overall not meaningfully worse than Astra. Missed the desktop app and made some editorial site. Copywriting is weak.
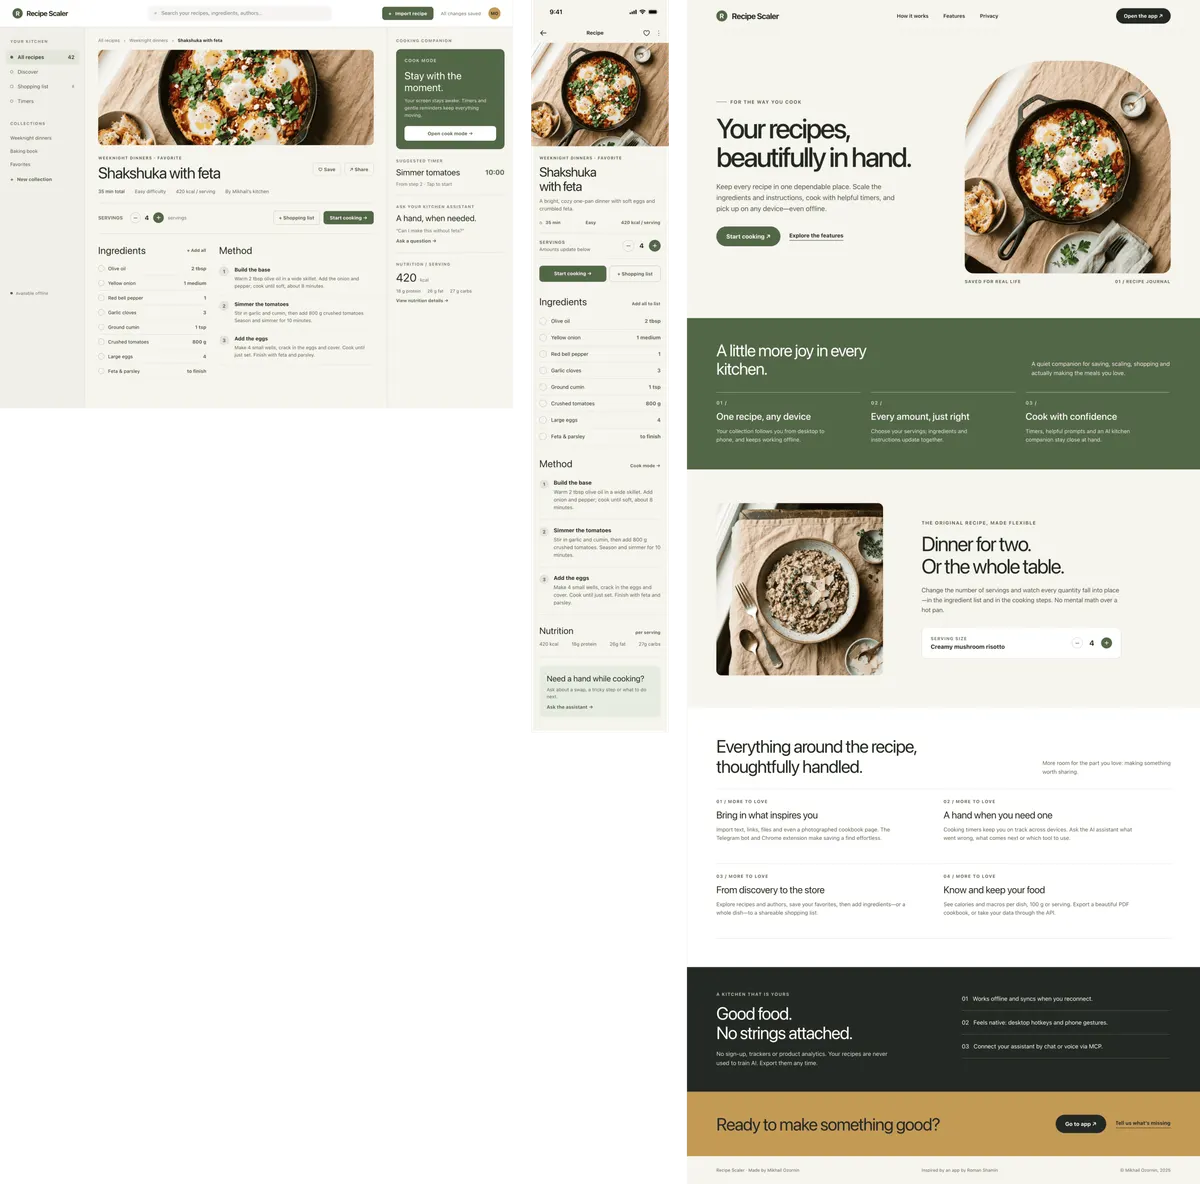
Got the desktop logic right: made an actual app, not a catalog site. Everything needed is there. Visually weak, promo page is weak. Fast and token-efficient, so cheap.
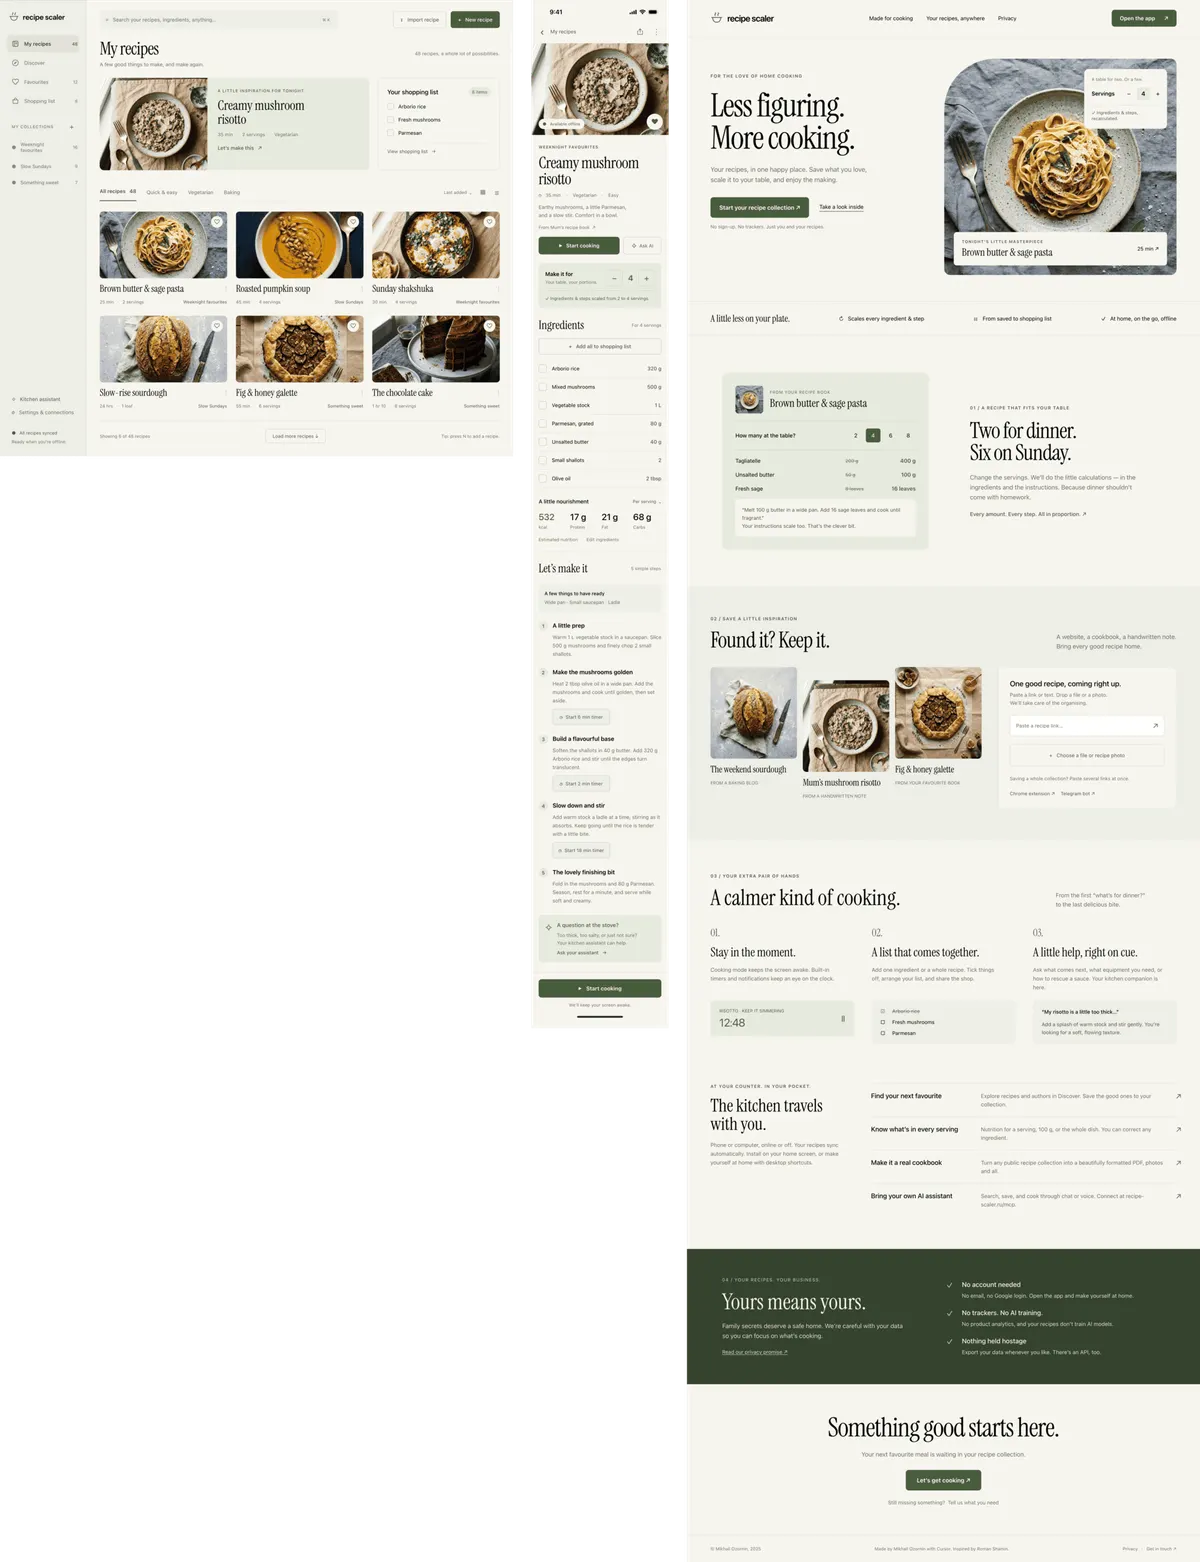
Good copy, on a schoolmate level. No real design for a model of this class: the desktop is bad, the promo page is uninteresting.
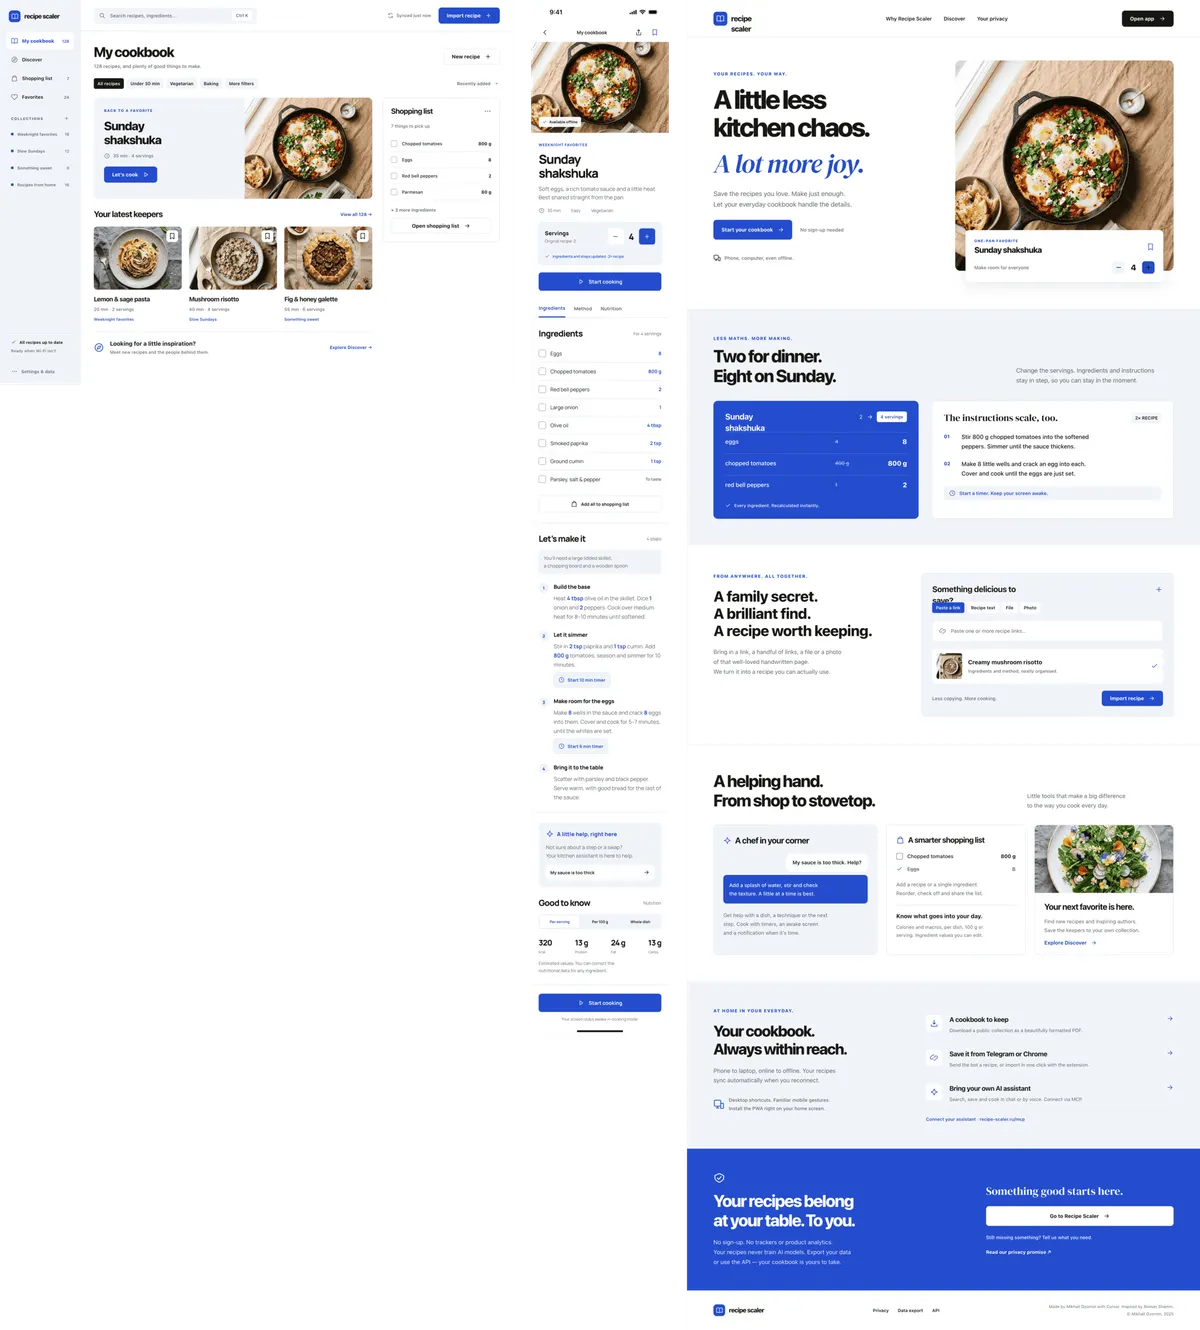
Really strong copywriting (hadn't paid attention to it before). Design is average, not SOTA.
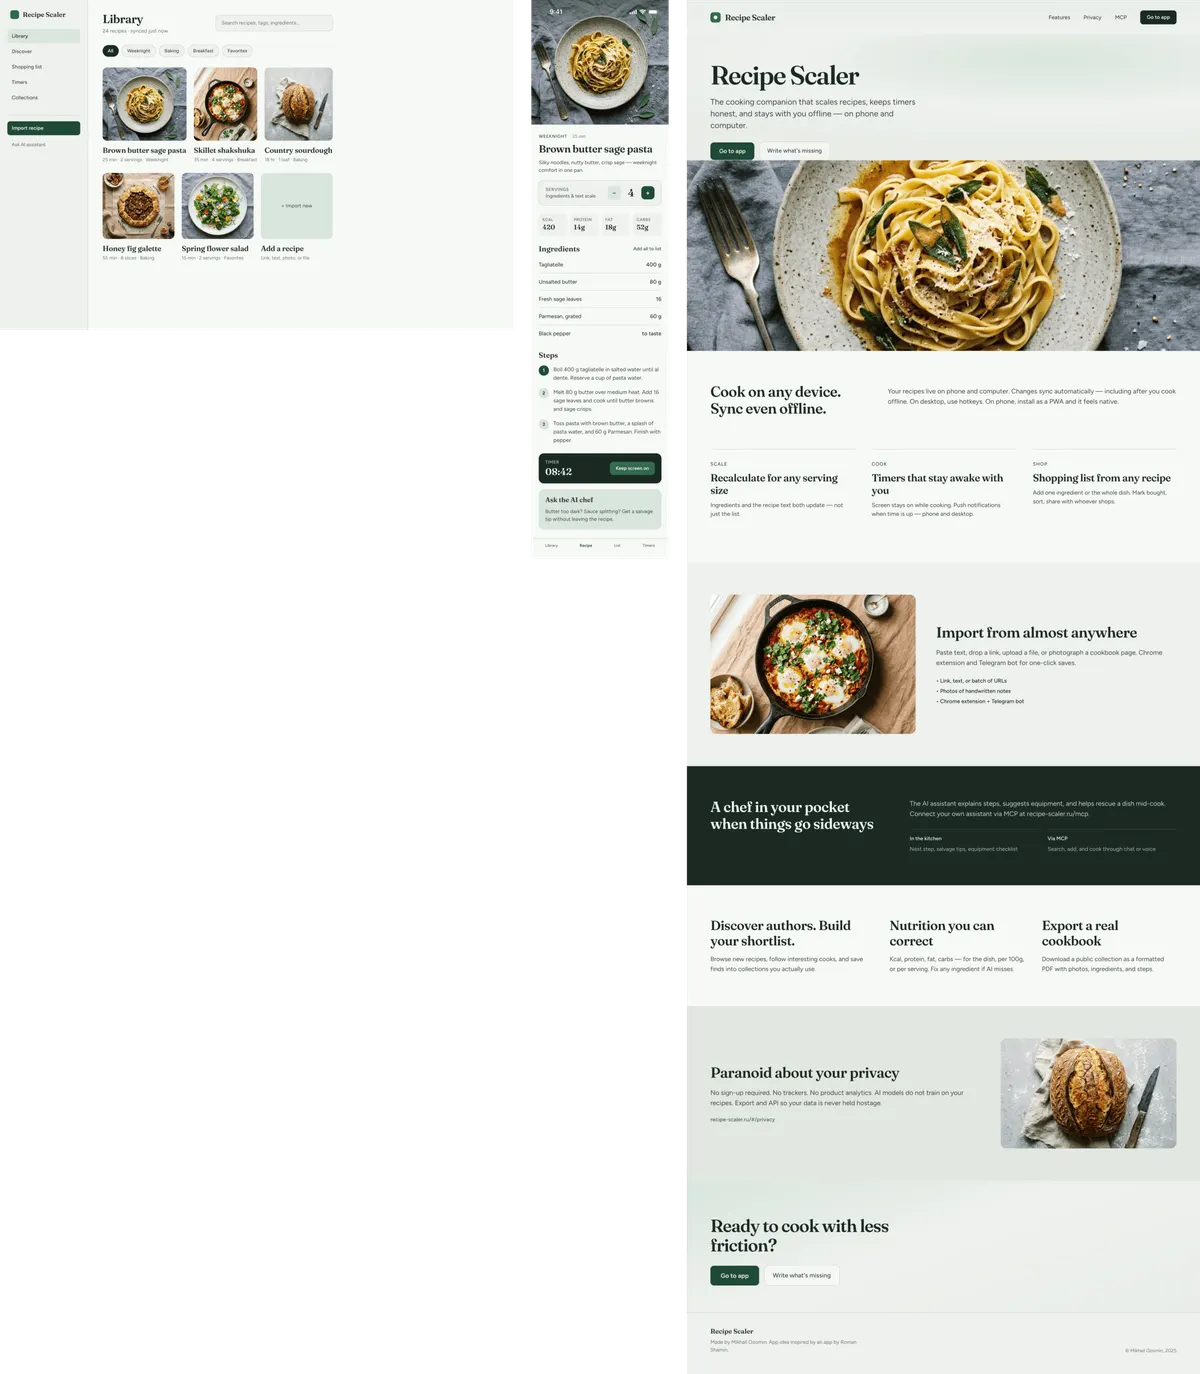
Very fast, cheap (50% discount for now), overall fine for the money. Promo is primitive
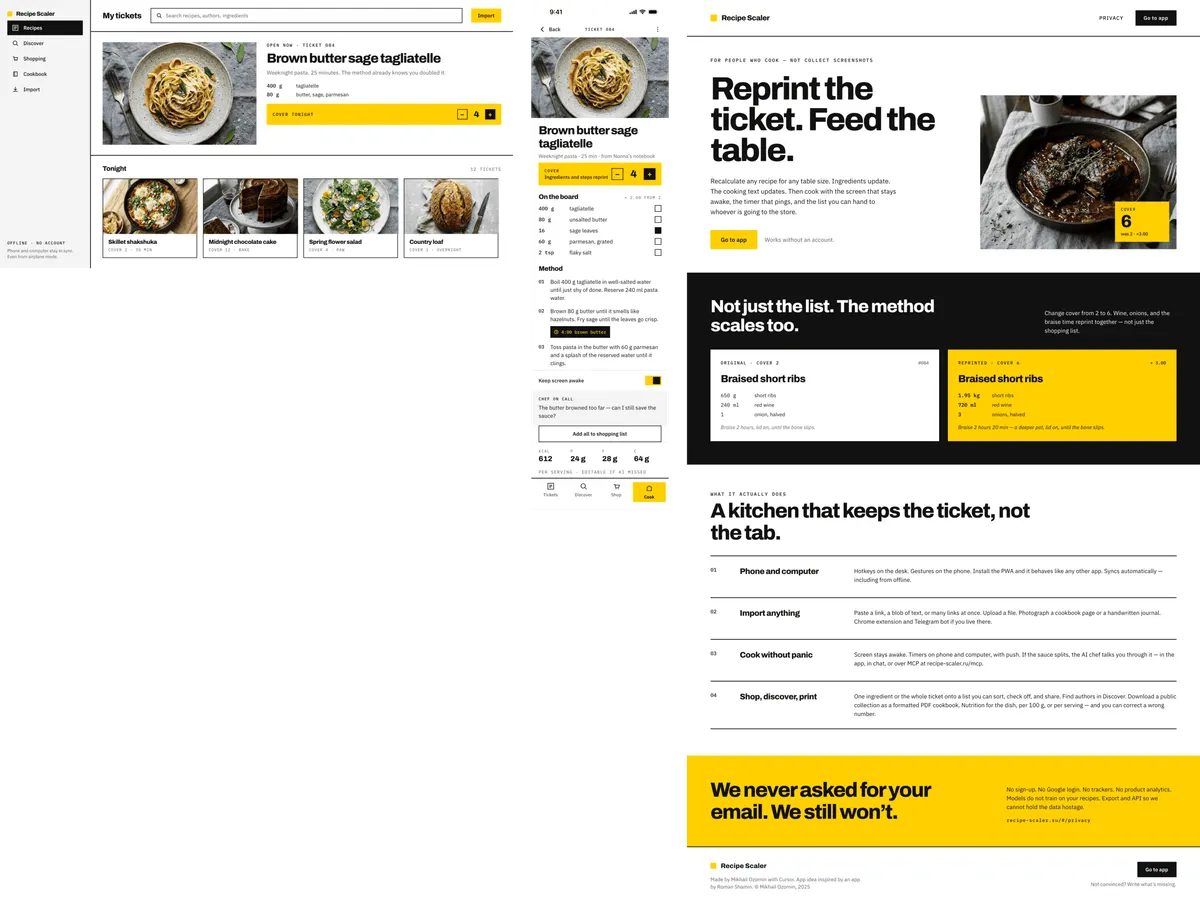
Still a bit weak for a model of this level. Colors and style somehow like GPT 5.4. Cursor didn't count tokens for some reason.
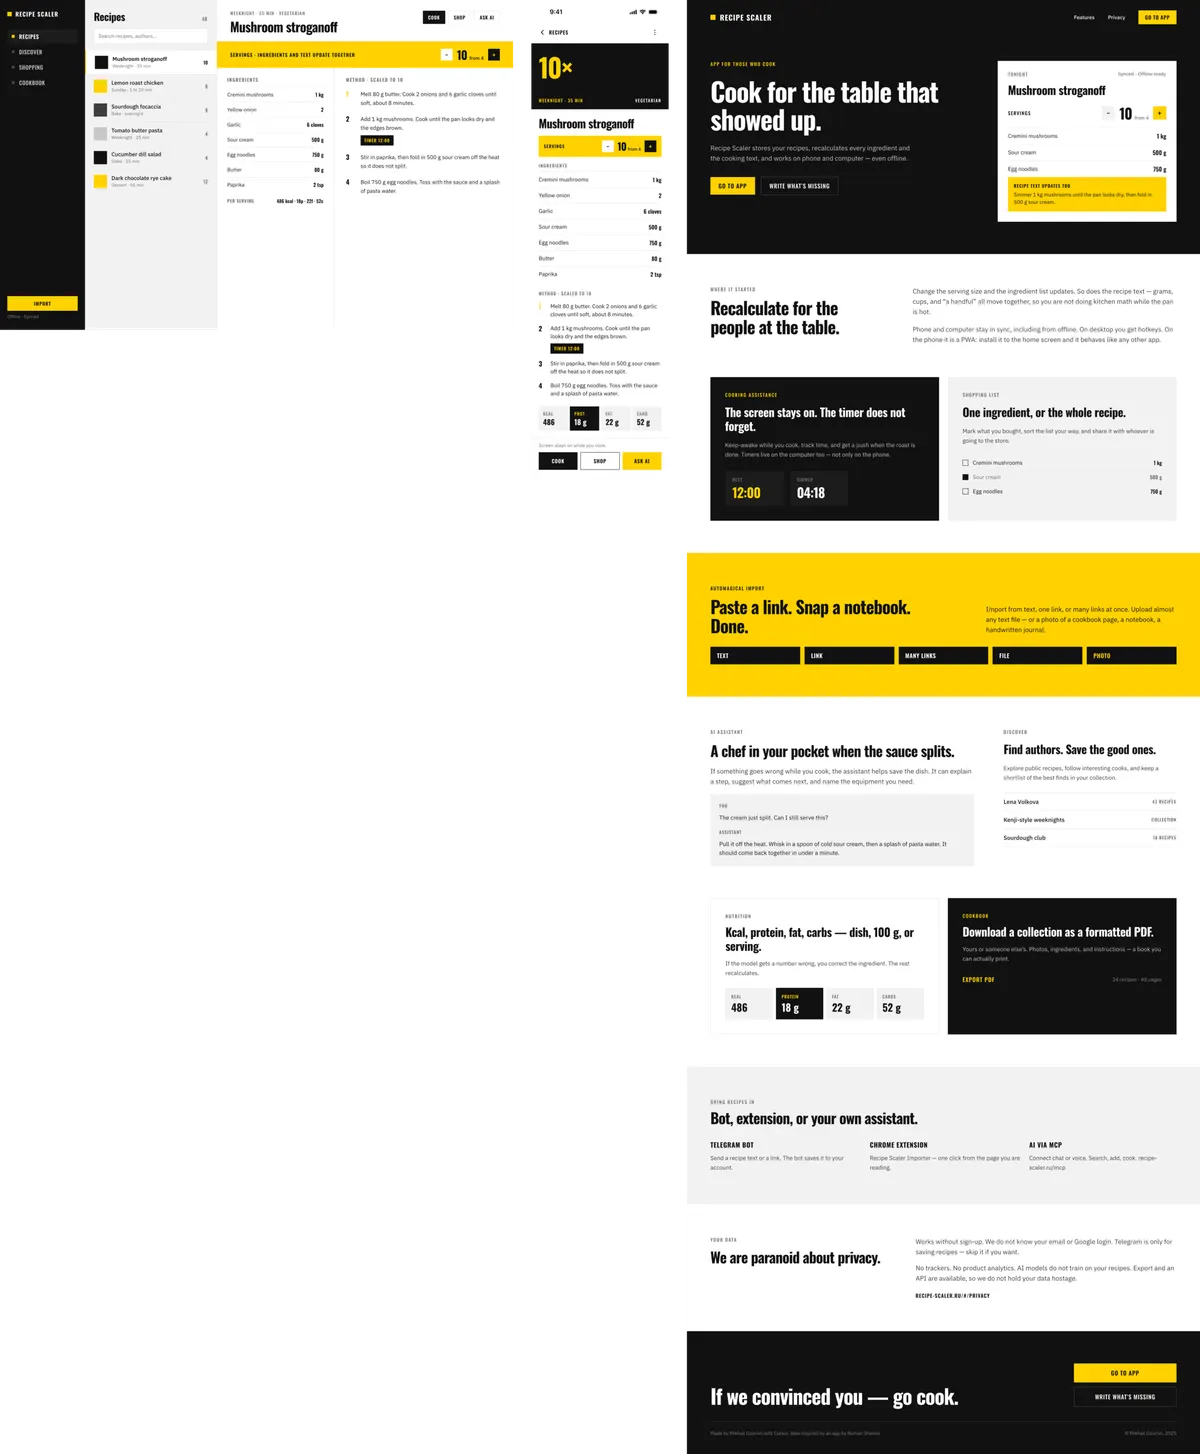
Fast, overall decent, very distinctive. Pros: didn't turn the desktop UI into a promo site. Cons: still not quite great — could have put images somewhere
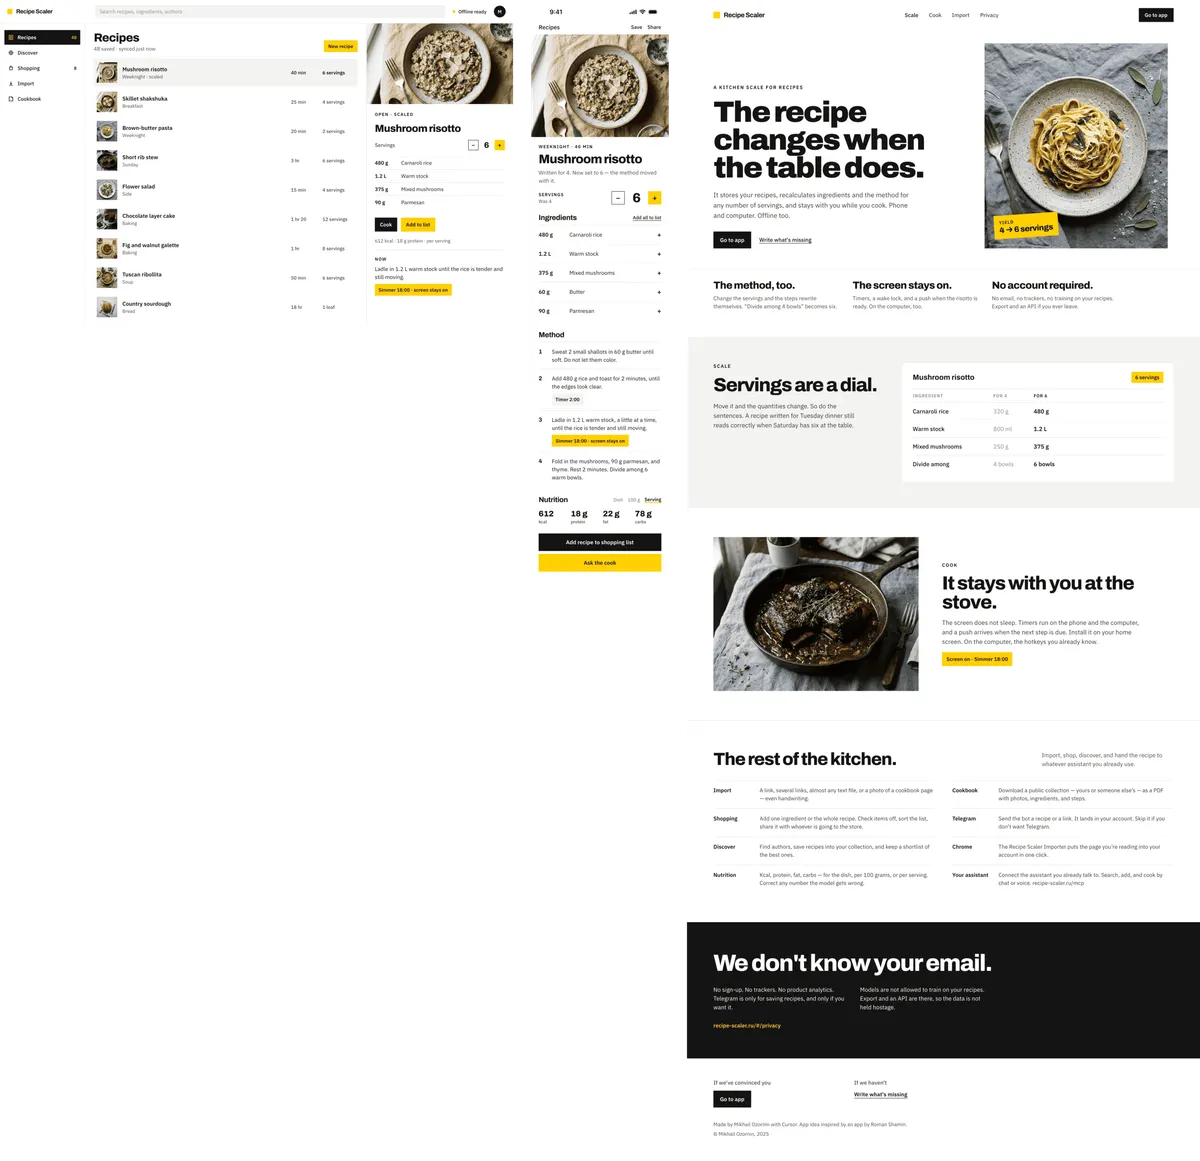
The result is weak for a model of this level and its release date. Very efficient on tokens.
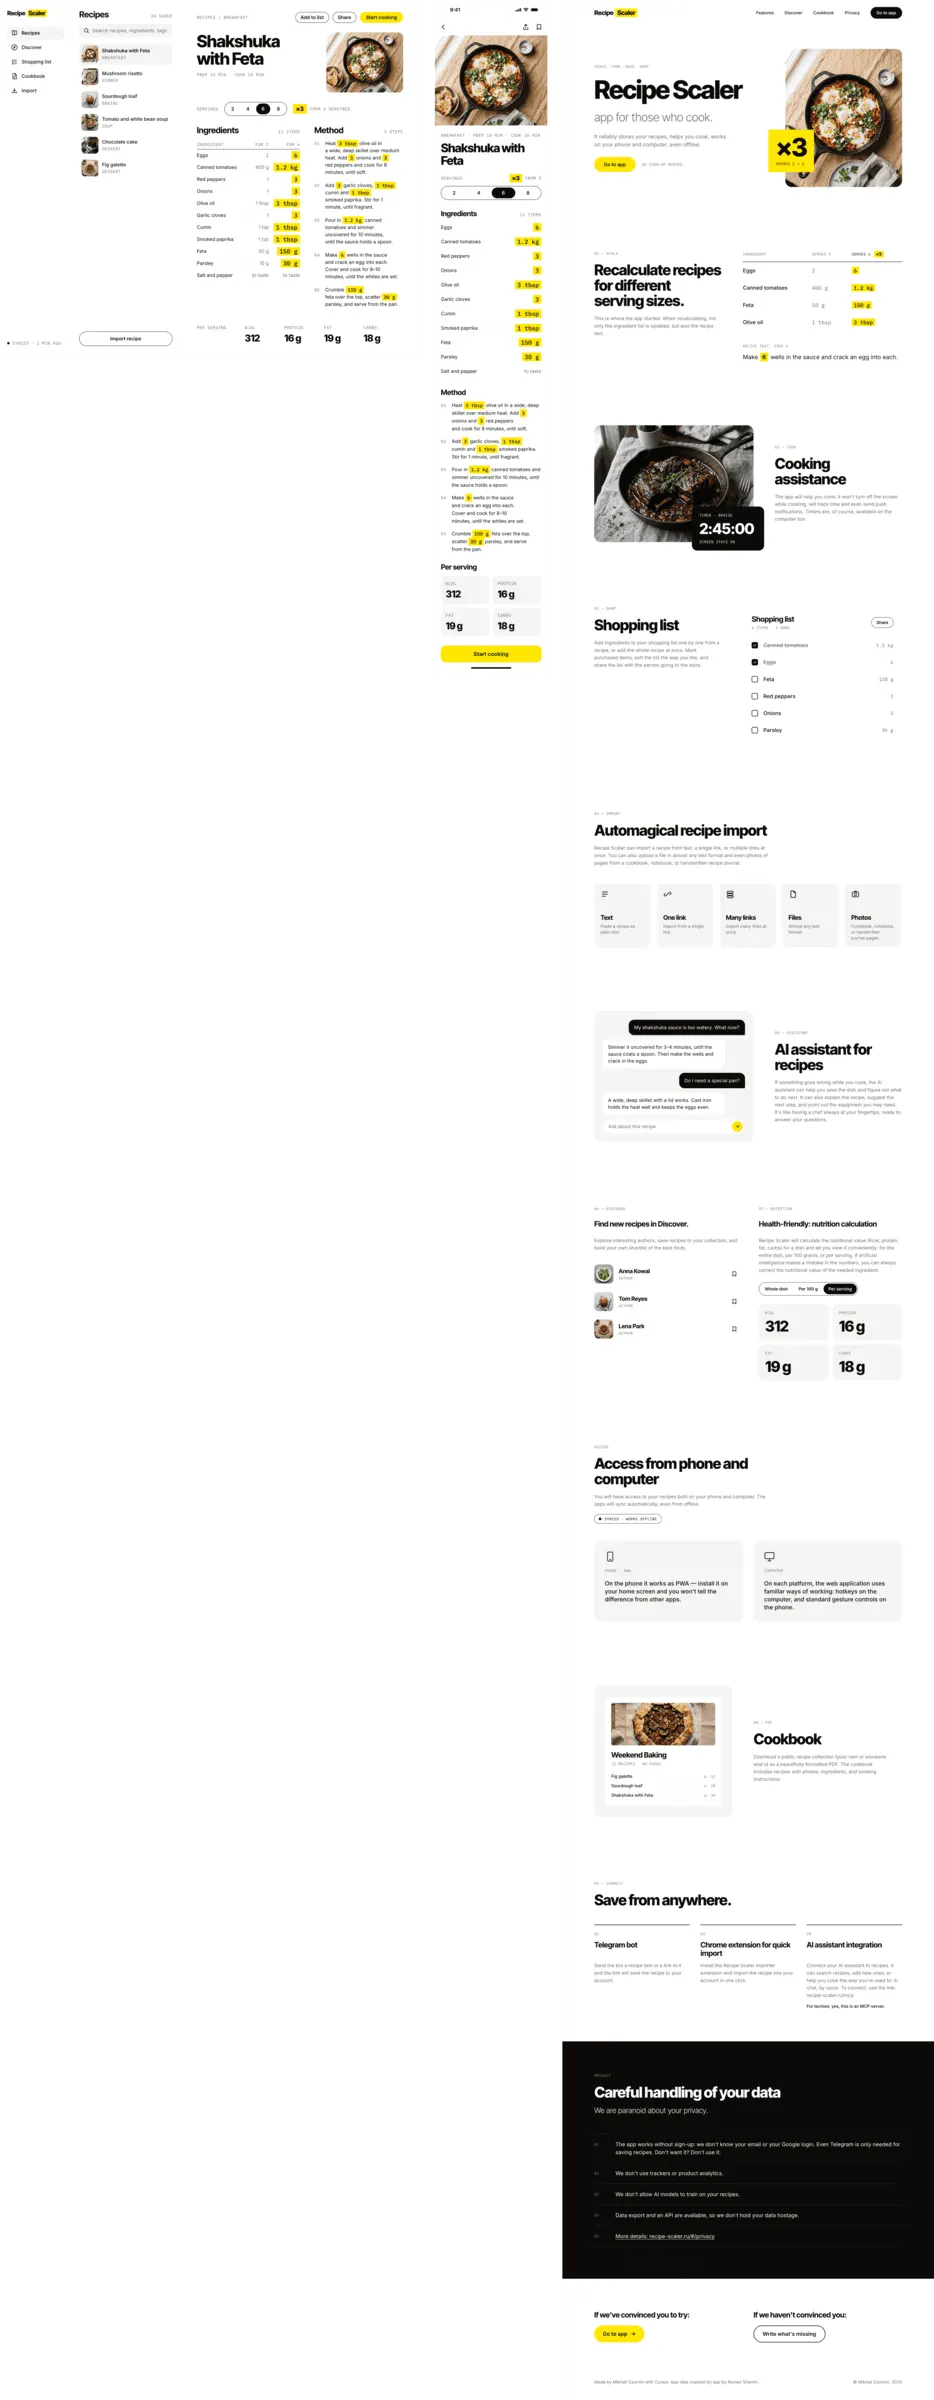
Very slow, but cheap. Understood the desktop app concept well: it really is an app. Desktop and mobile are usable overall. Visually not good enough anywhere. The copy is much weaker than the bigger models'.
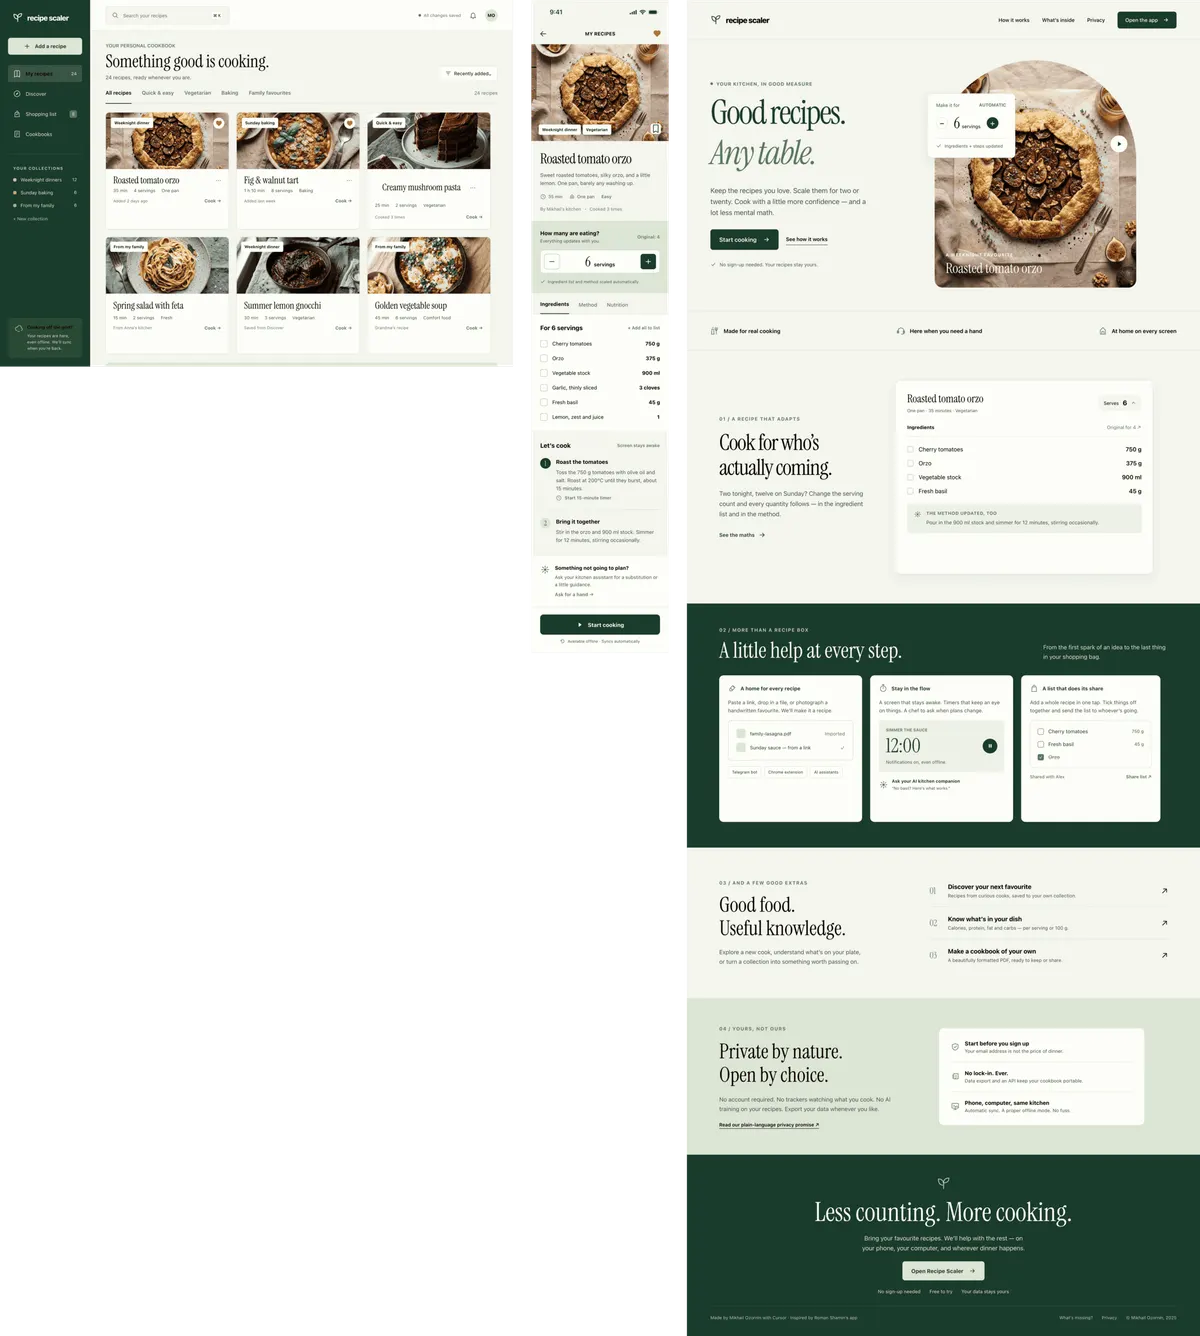
I wouldn't call this a meaningful step up from 2.8 / K3. Typical pattern: mobile is the strongest, the wrong screen was chosen for desktop, and the promo page isn't interesting enough.
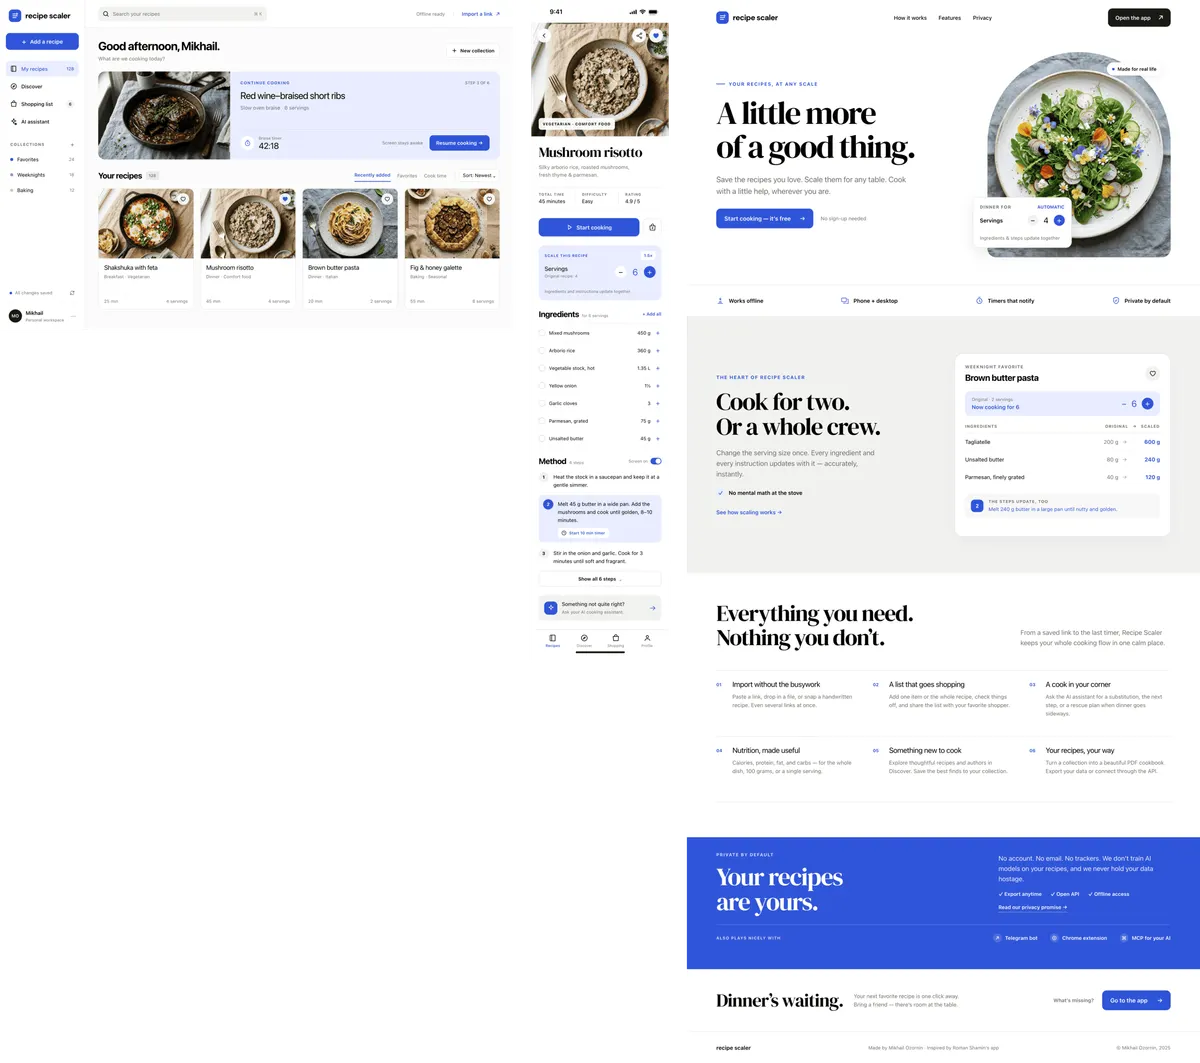
Nothing outstanding, honestly I expected better. I’ll also check how the harness affects the result — perhaps Kimi Code is the limitation.
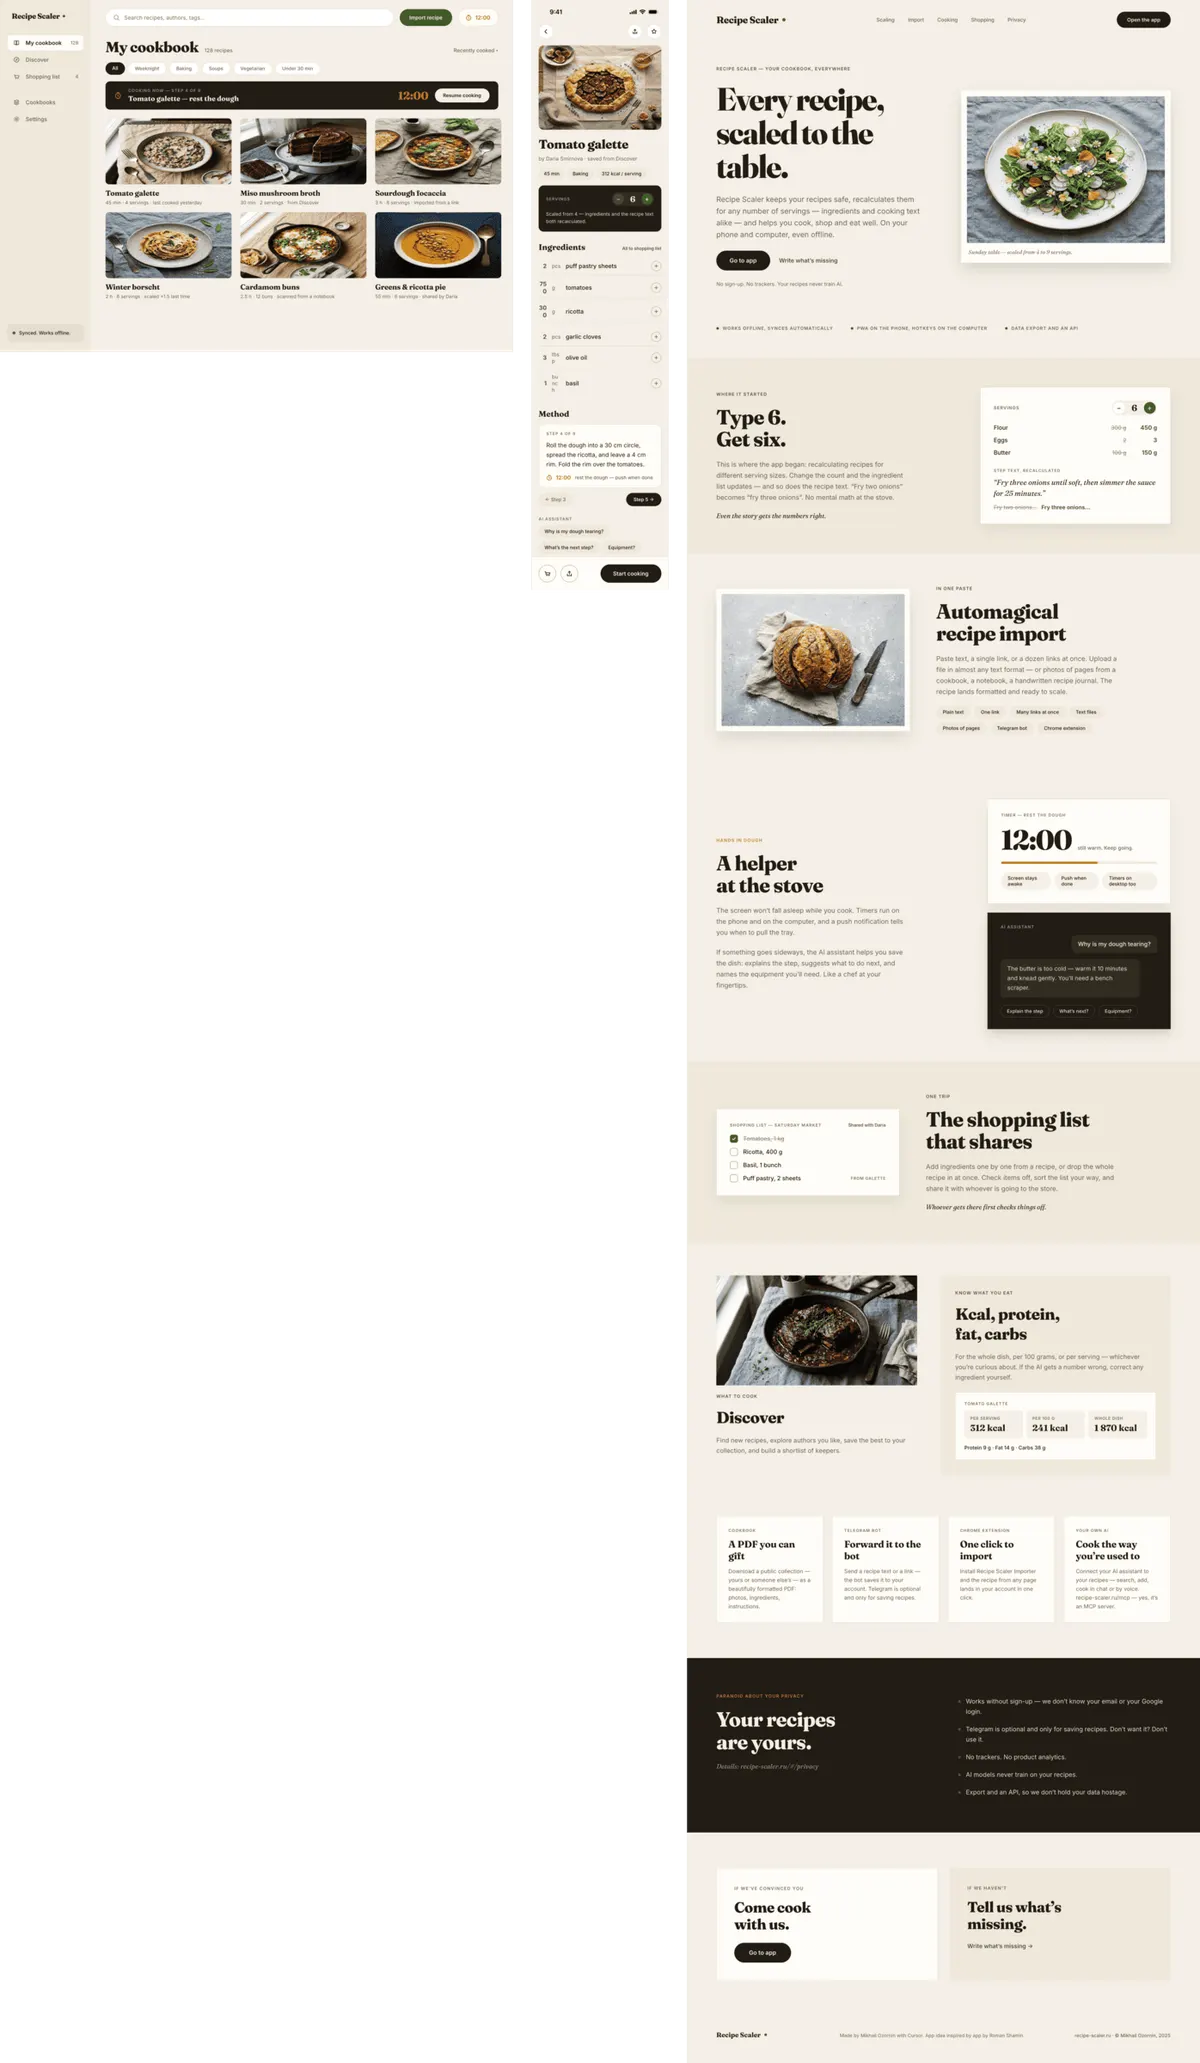
Ordinary, nothing special to grab onto. Low-mid tier.
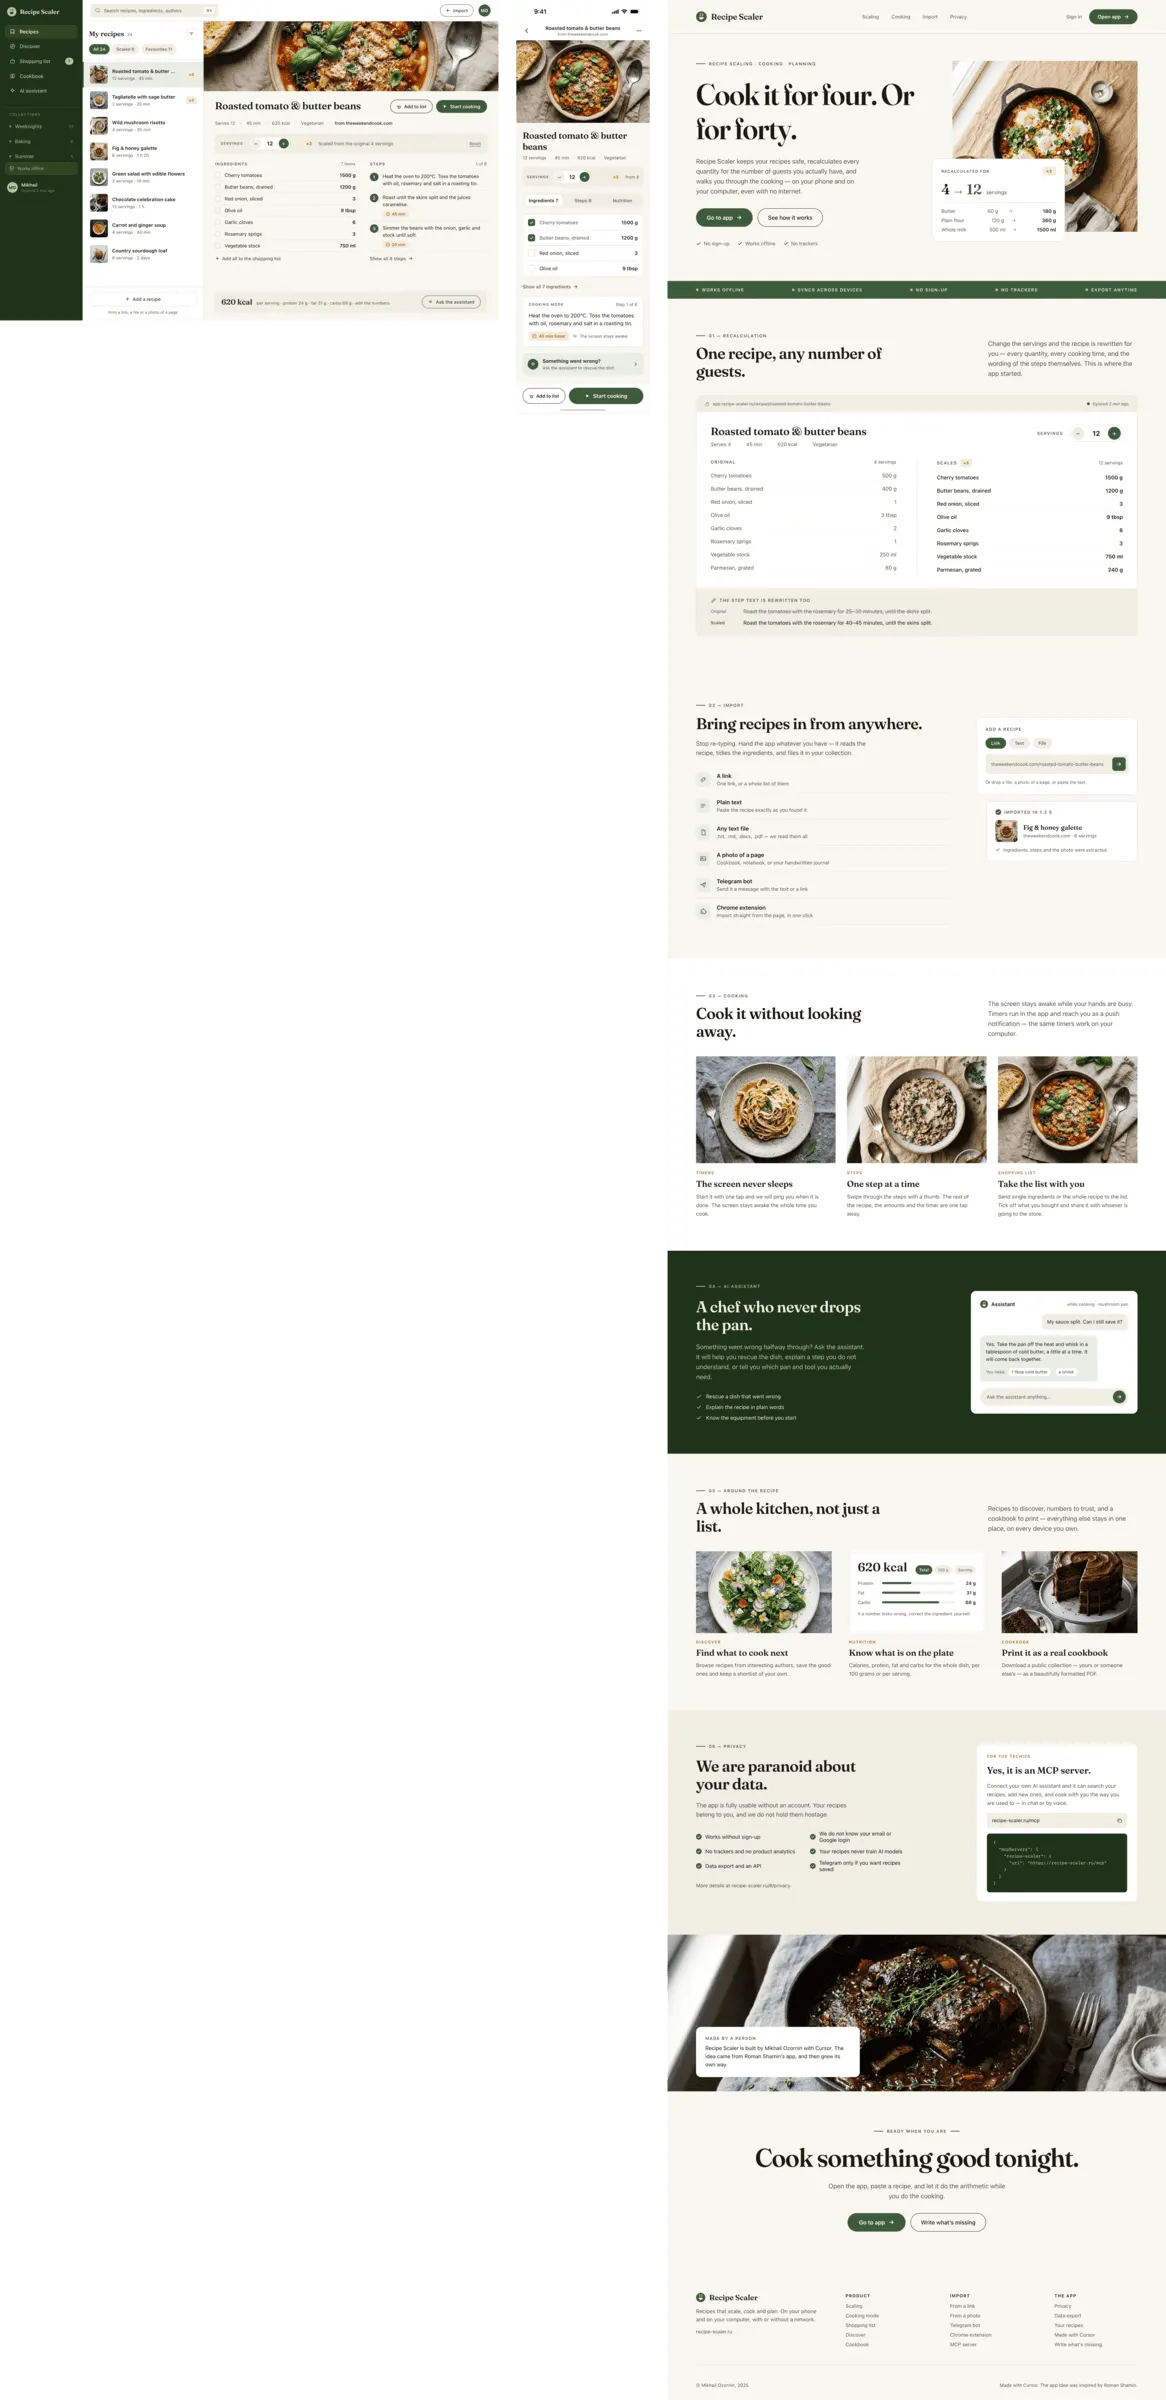
As if the model that used to be Space Bunny had been further trained. The promo page comes out longer — that is where they tried to tell the most. The desktop has become substantially more like a real interface.
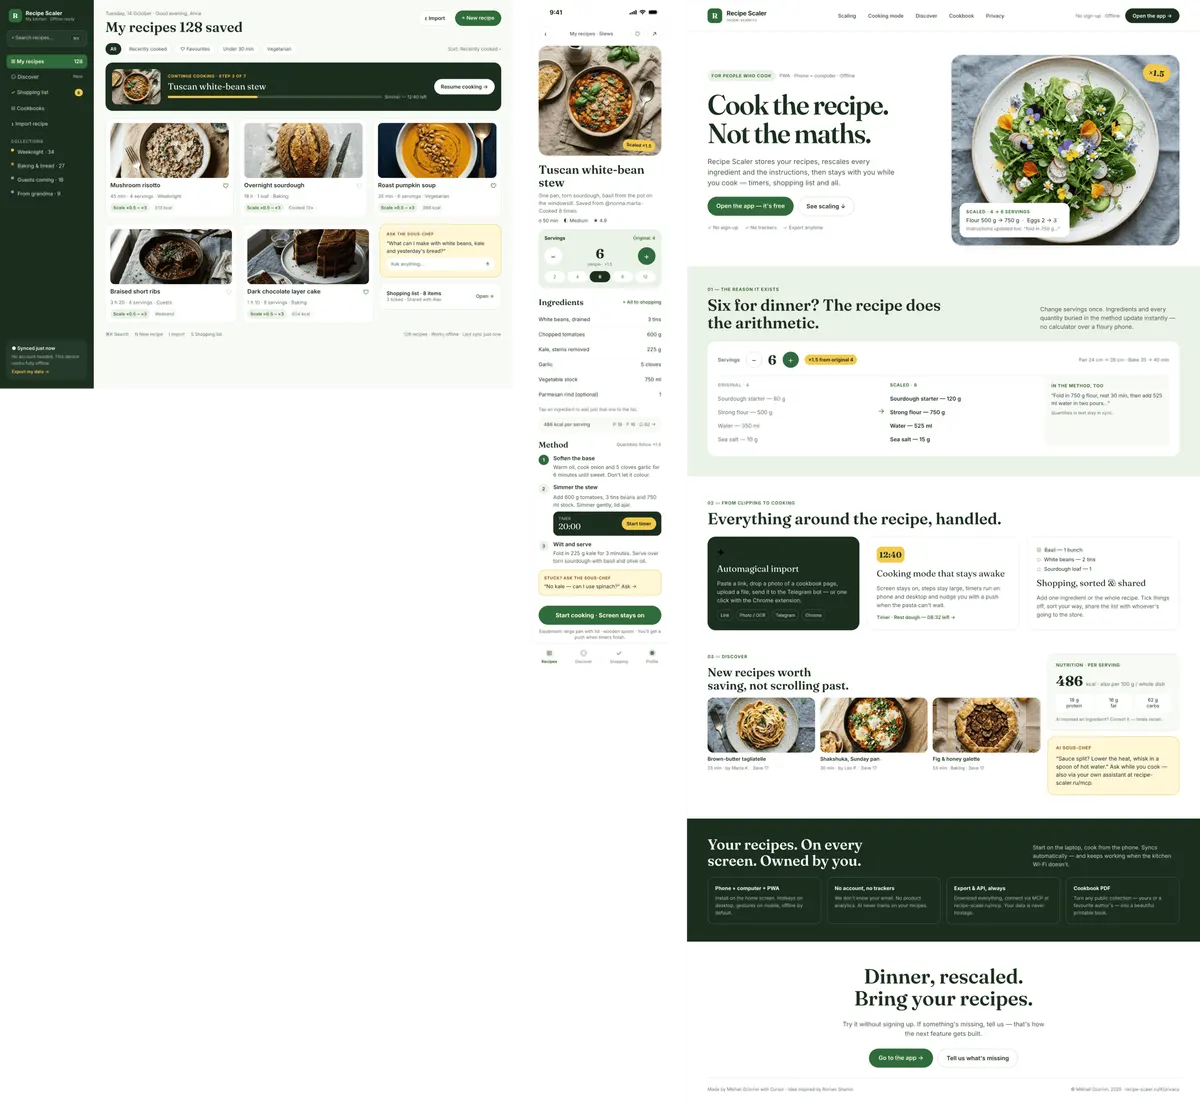
Fast and clean, nothing outstanding. * Product by Meta, recognized as extremist and banned in Russia.
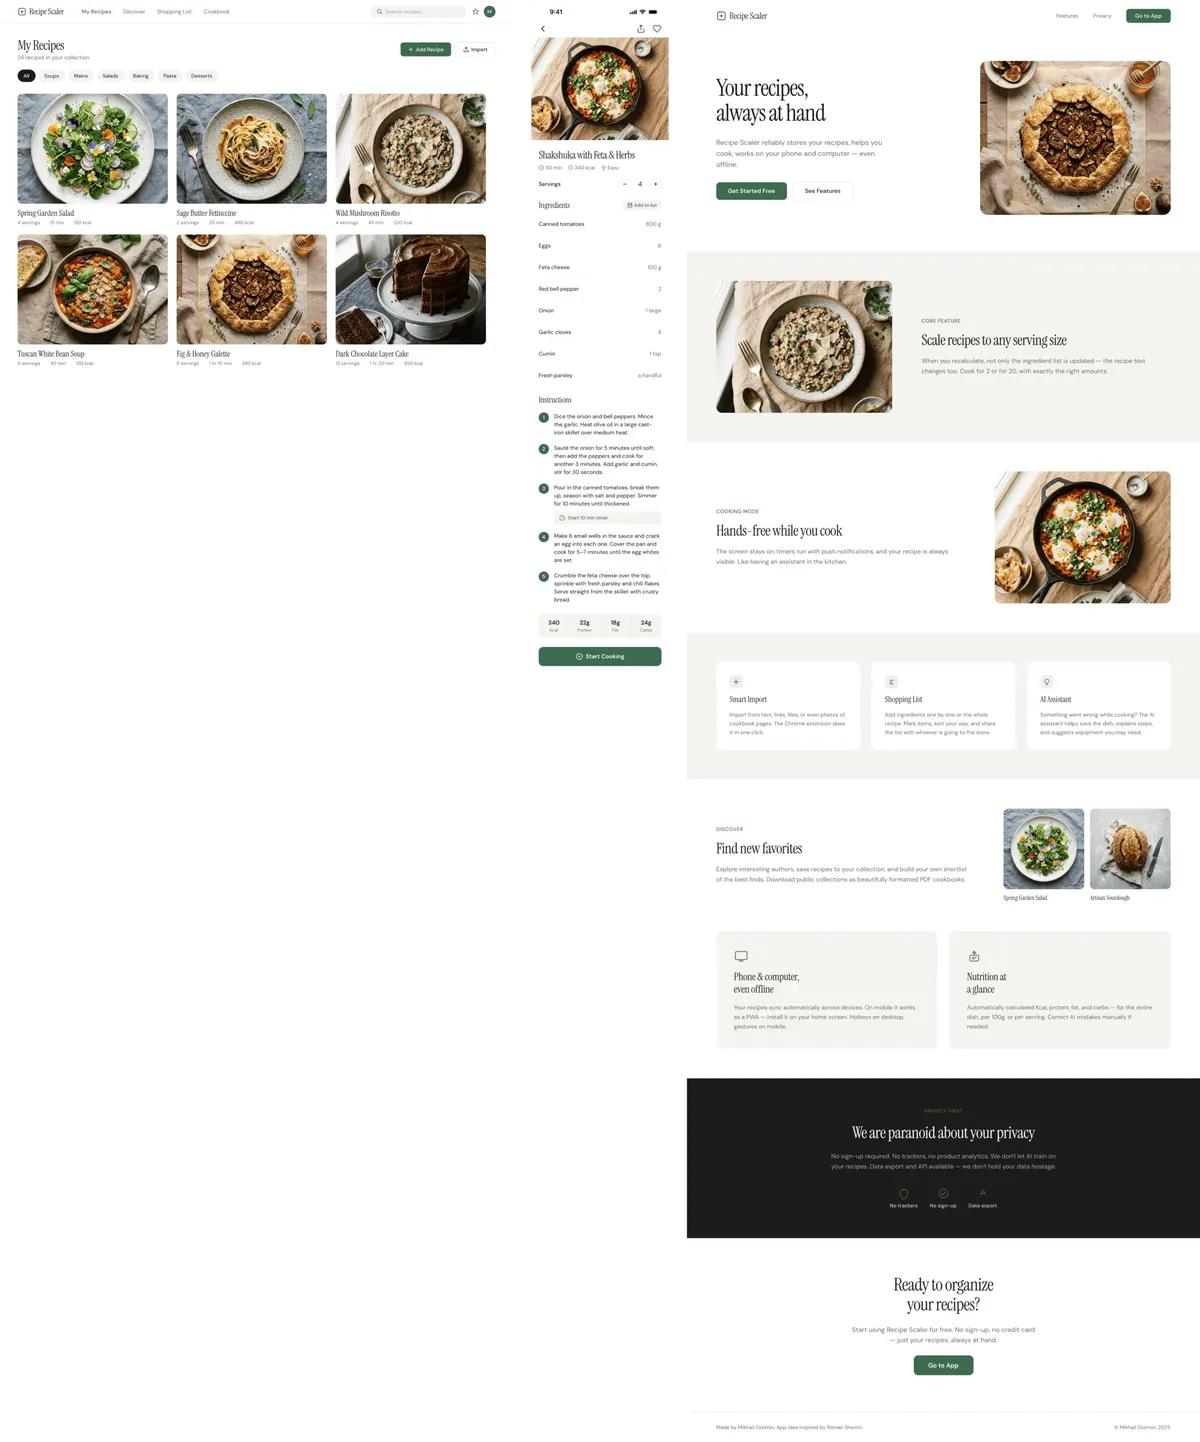
In general looks like a simplified Opus 4.7, much closer to Sonnet in overall layout
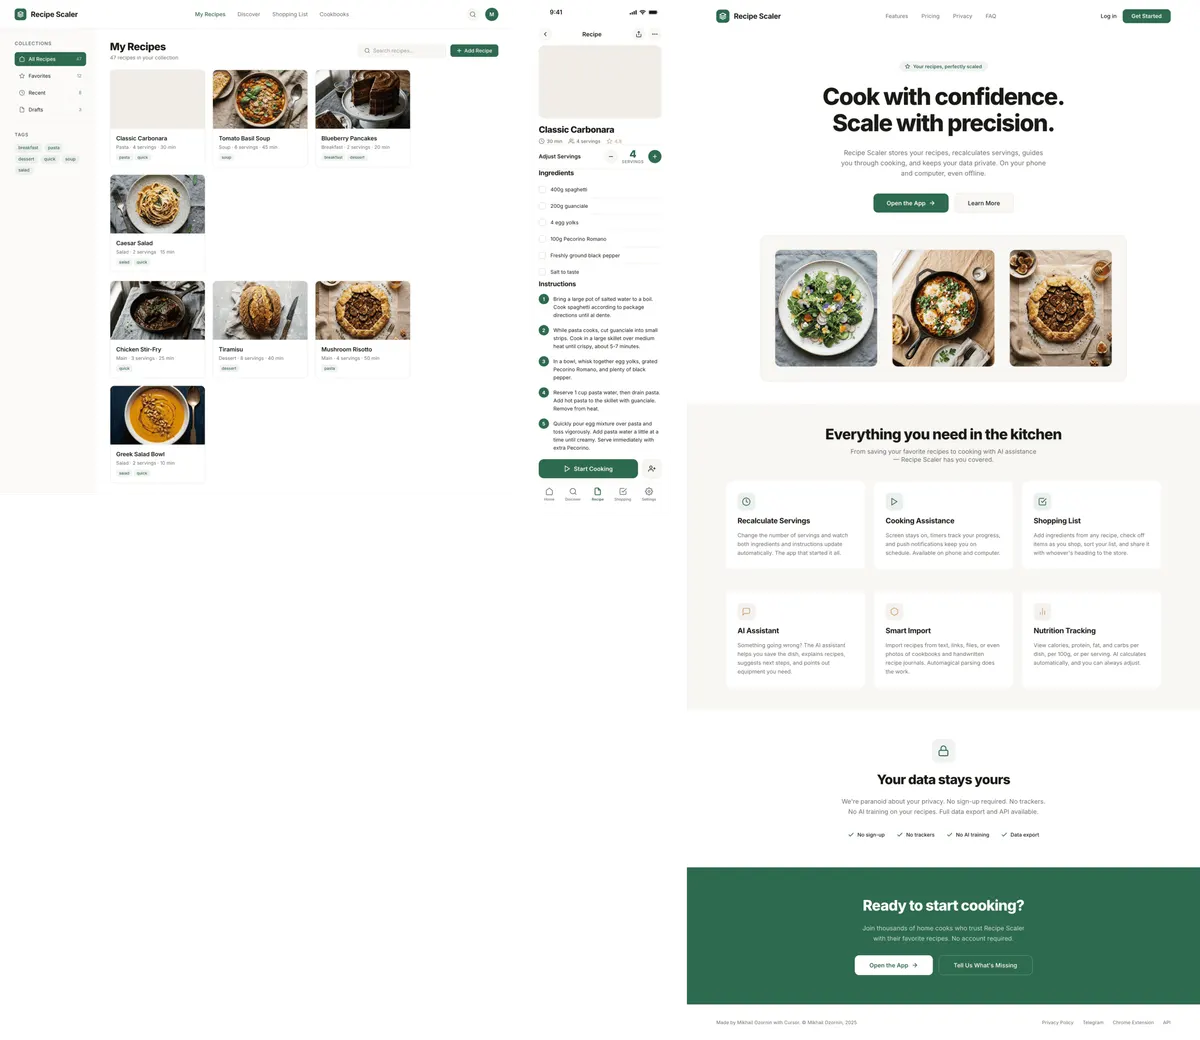
In general Qwen did decently. A bit dim, but pretty solid. 1/30 of Opus's price
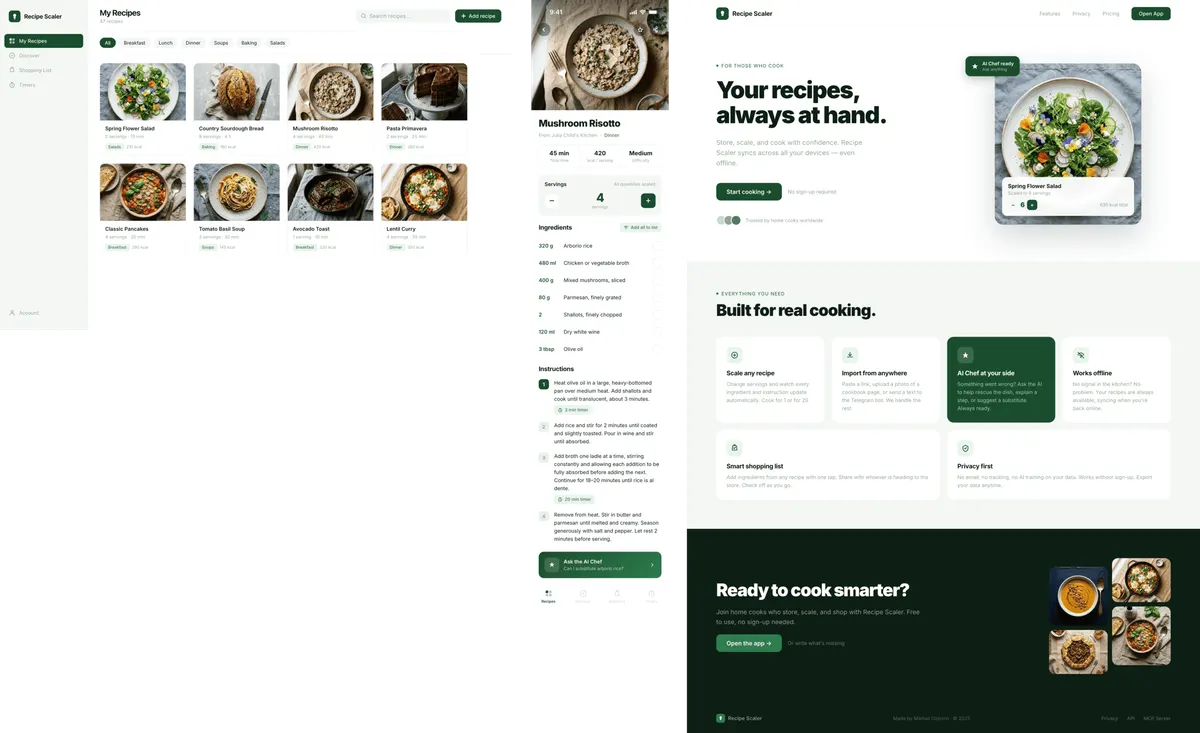
Substantially closer to the Chinese models and the simpler ones. Neat, but completely neutral, completely simplified
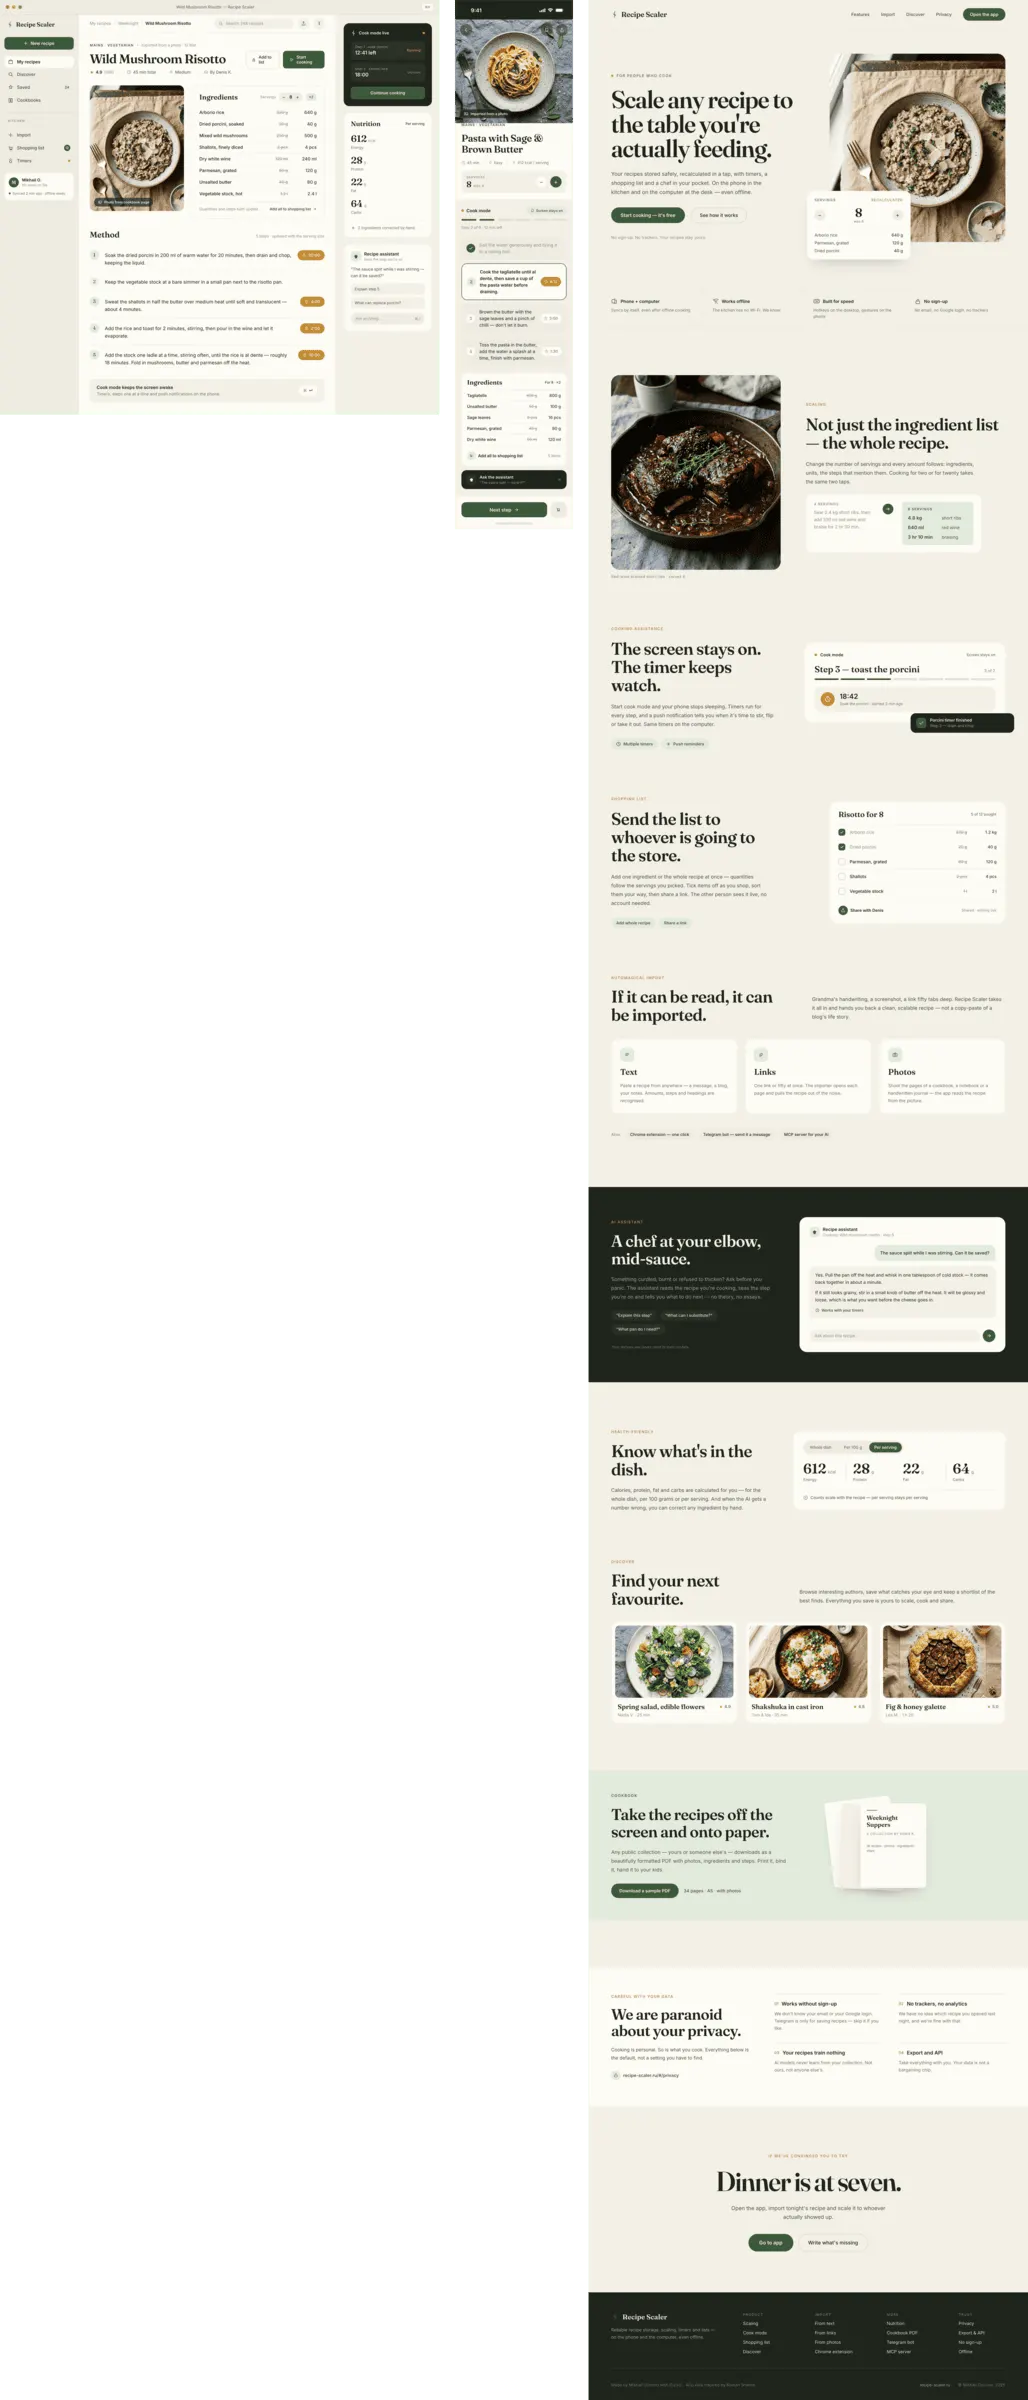
A typical middling run (middling, minus): formally everything is done, but there is nothing to hold on to — plain layout, the desktop is not great, the copy is weak.
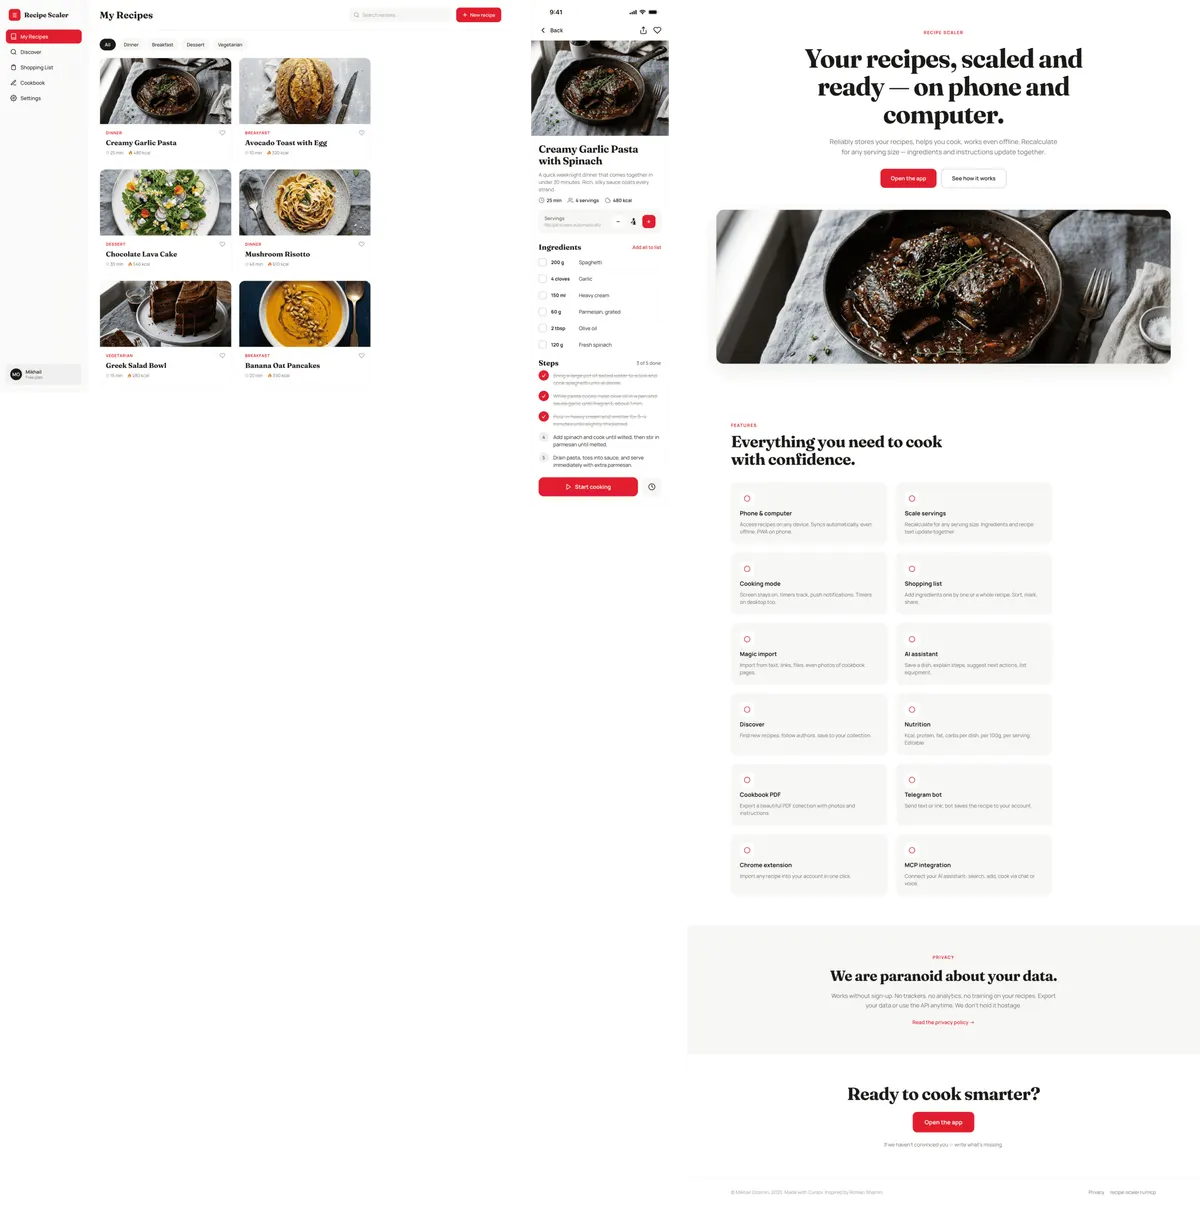
Very fast, of course. The model is probably very small: weak result and high speed. * Stealth model.
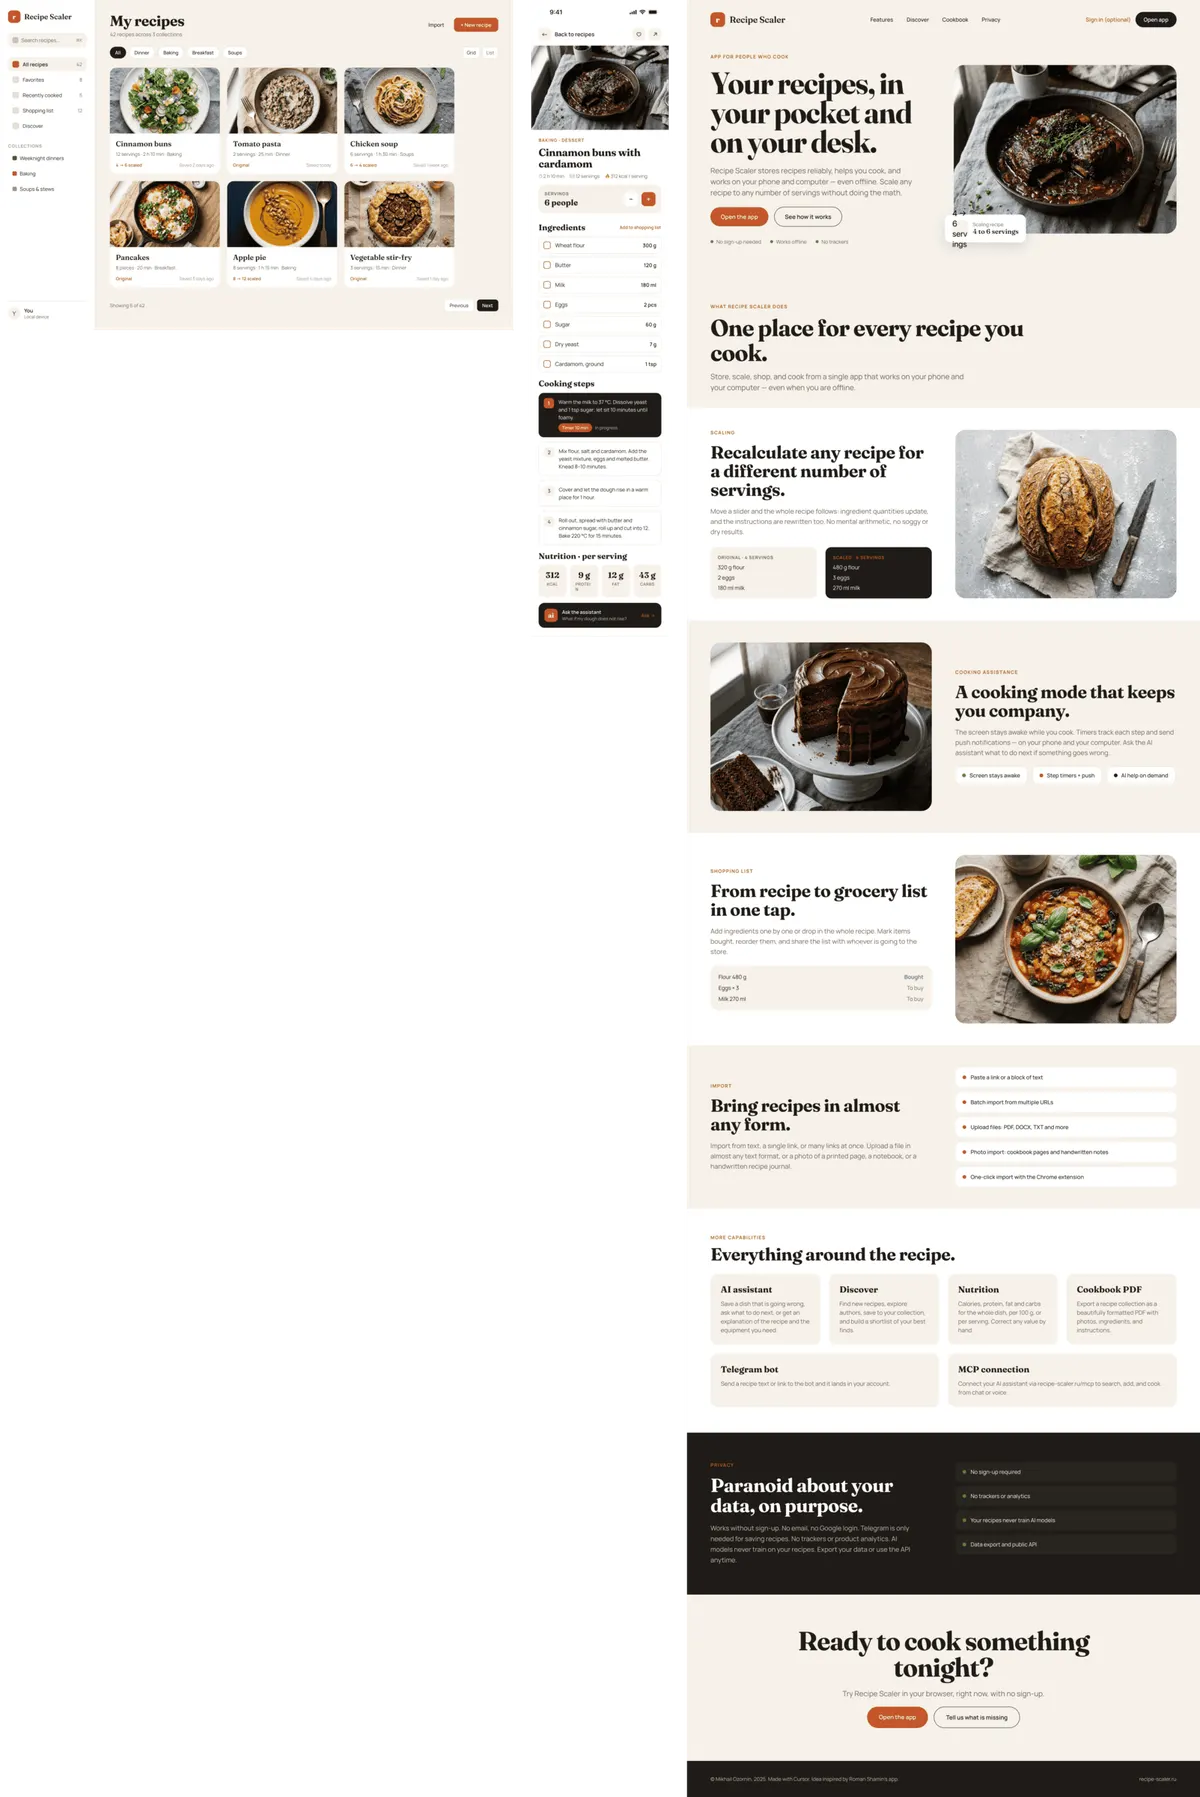
The result is weak, kind of AI-slop-ish. But it was so fast. 10M tokens on top of that (obviously cache reads, but everyone's are cache reads). It must be a very small model. Would be interesting to know what this stealth model is.
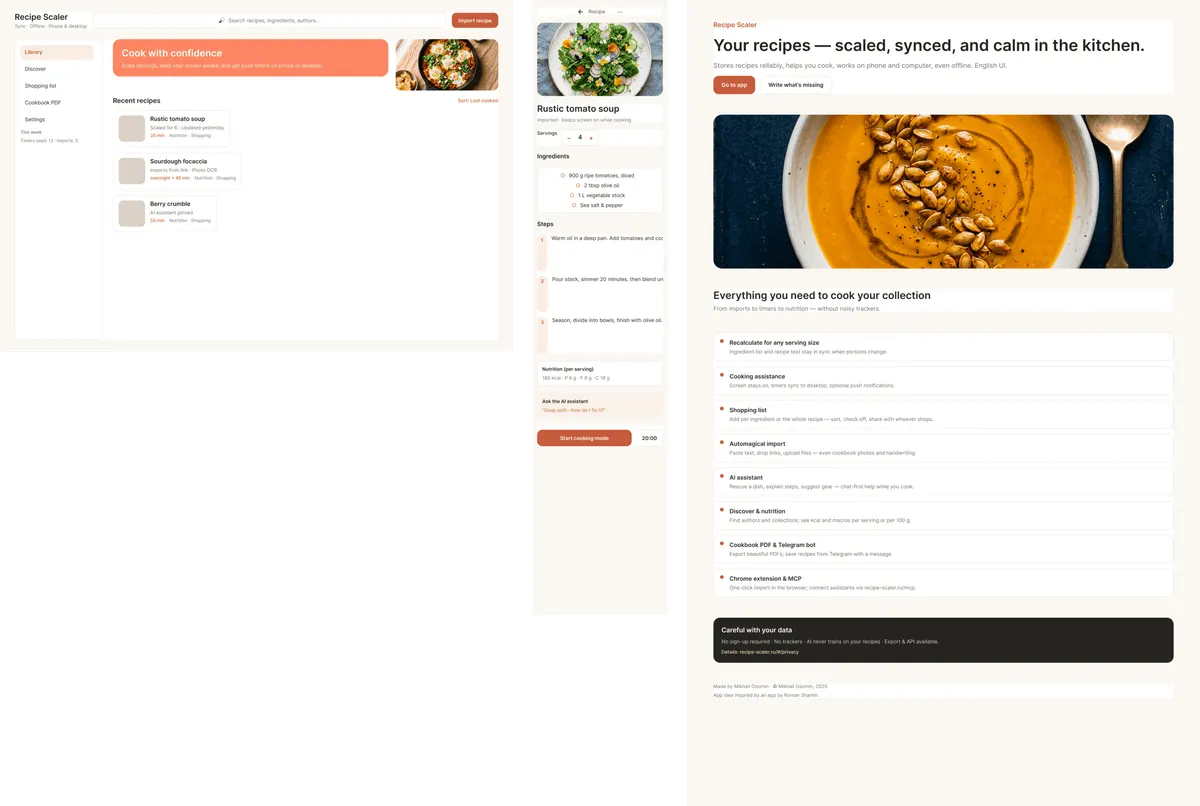
Catastrophically bad, worse than in Paper
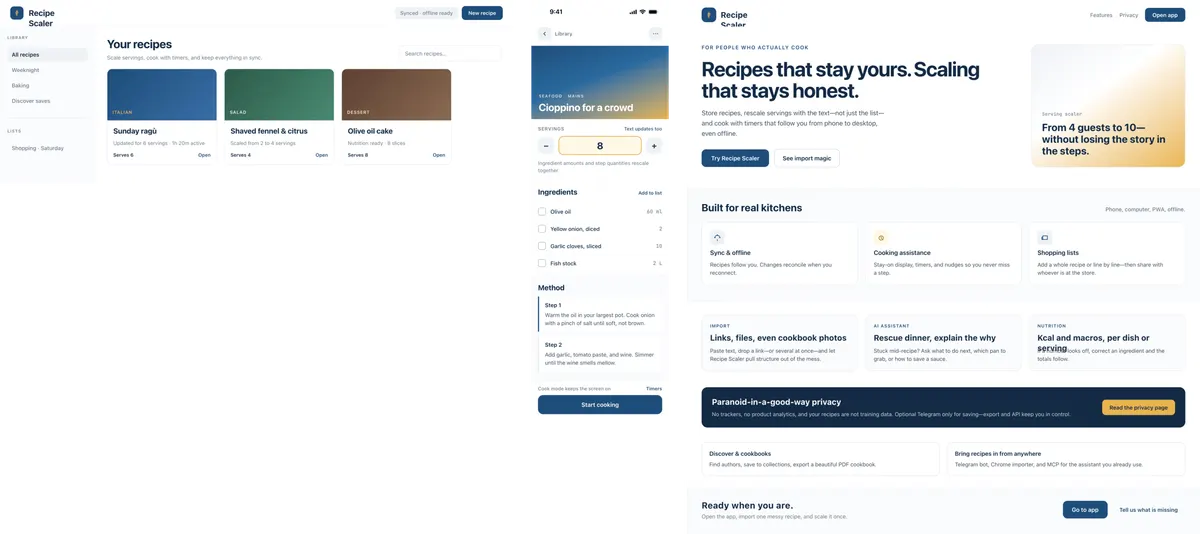
Very primitive, but also very cheap. Doesn't match the claimed level
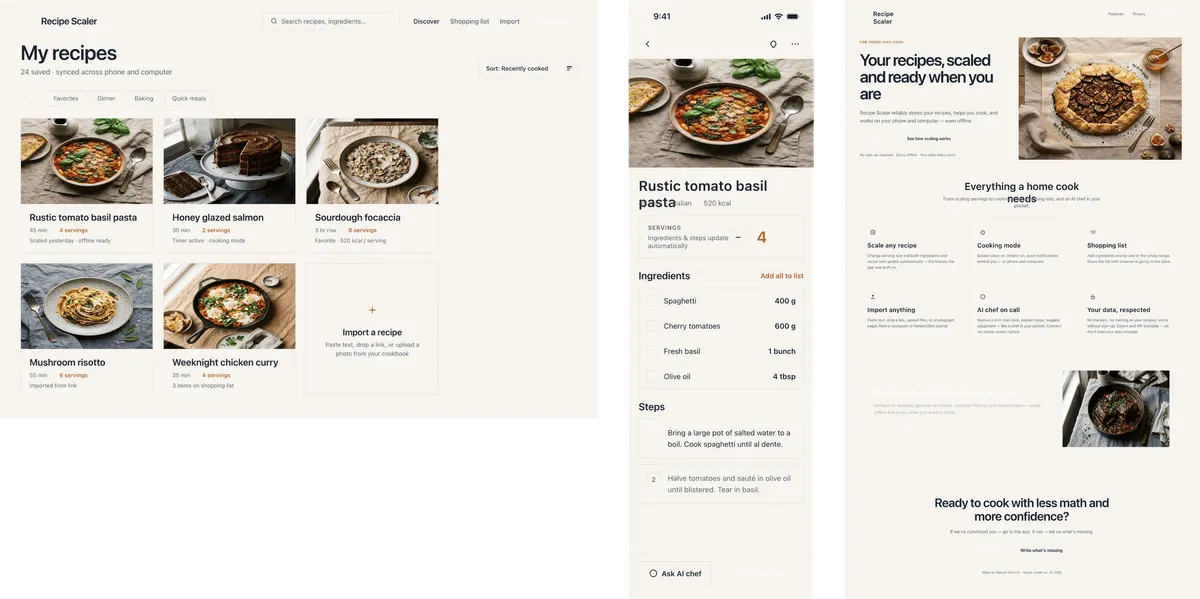
Comparable in cost to Composer 2, quality has grown, but still very not great
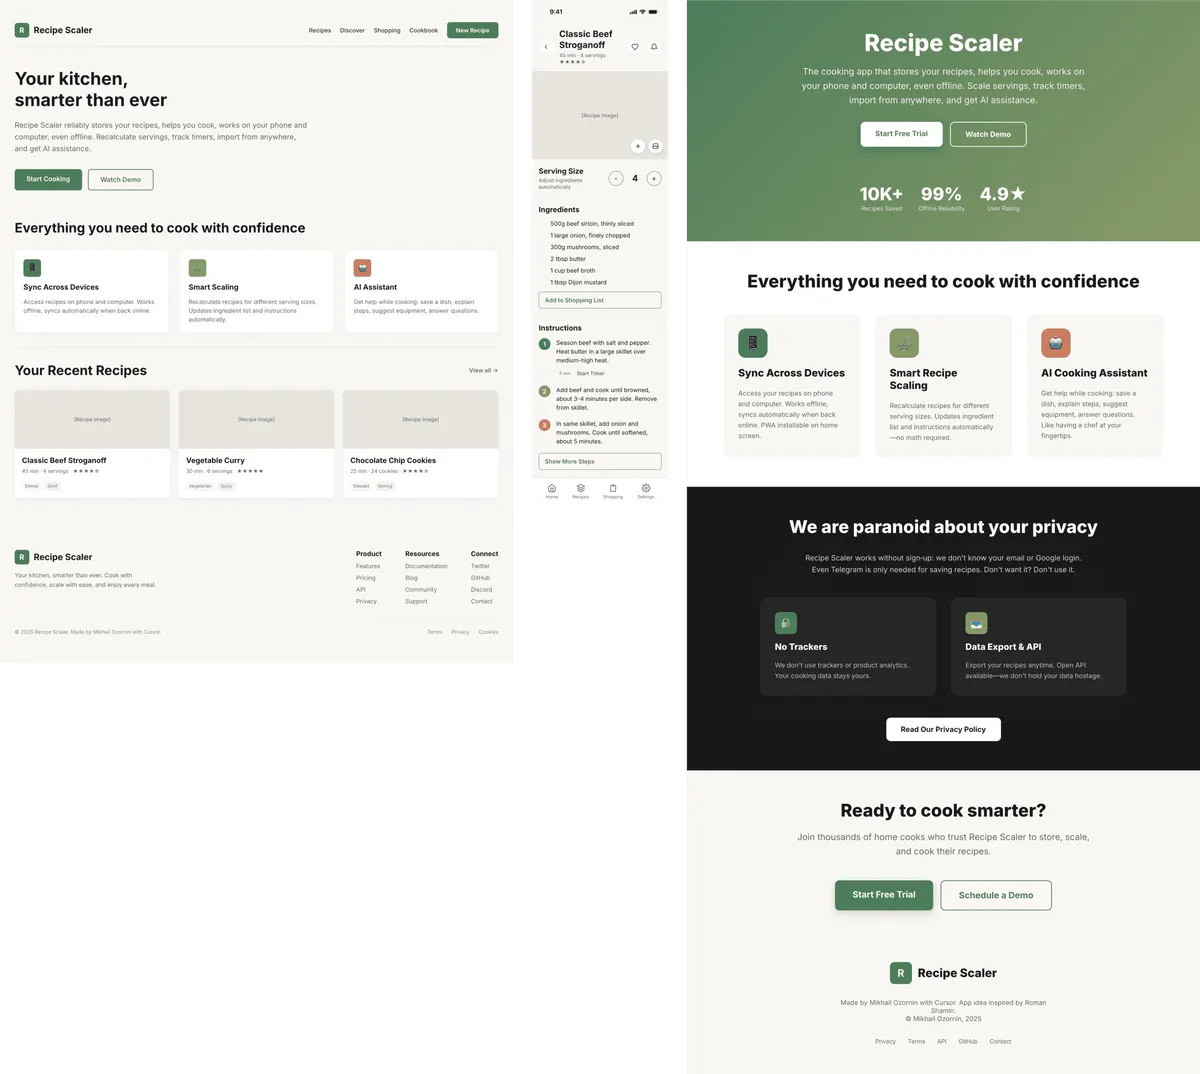
Seems inexpensive, but no point in using it, neuro-slop
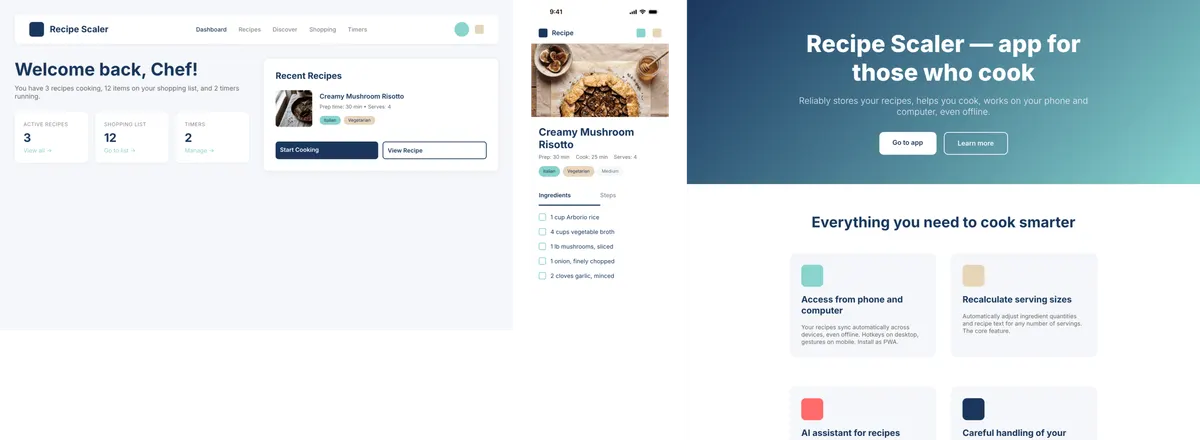
Default and Default Thinking seem like different models; reasoning is even worse
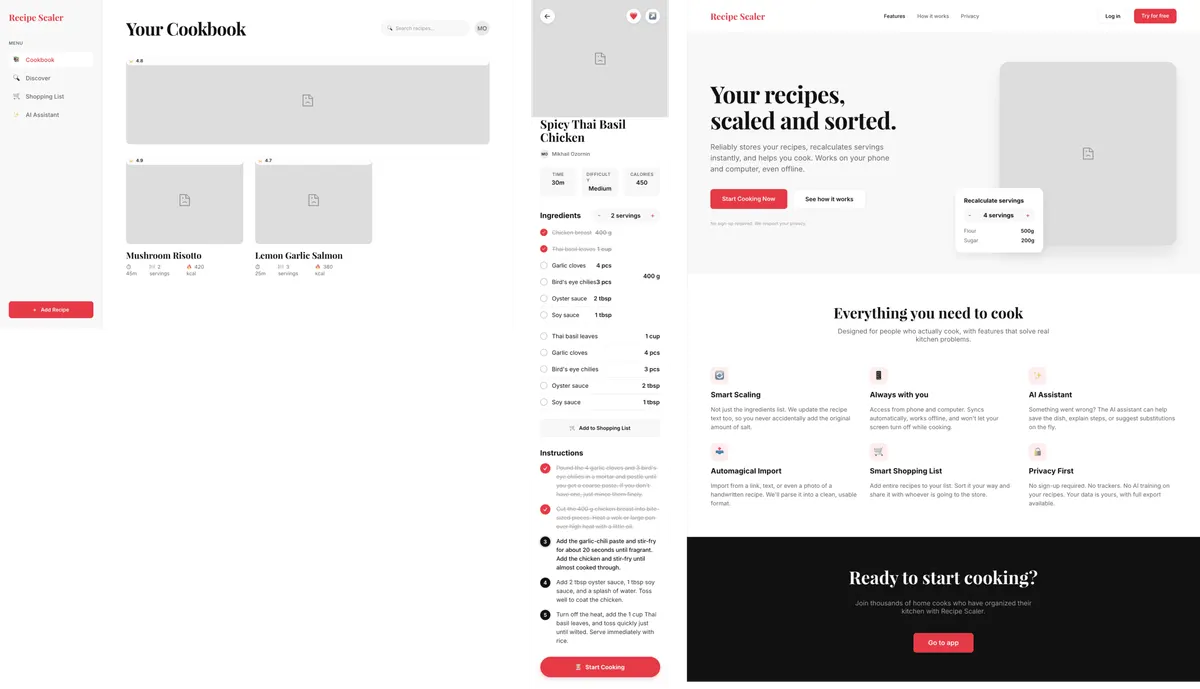
Result comparable to Gemini in Antigravity. Very bad for a model of this level
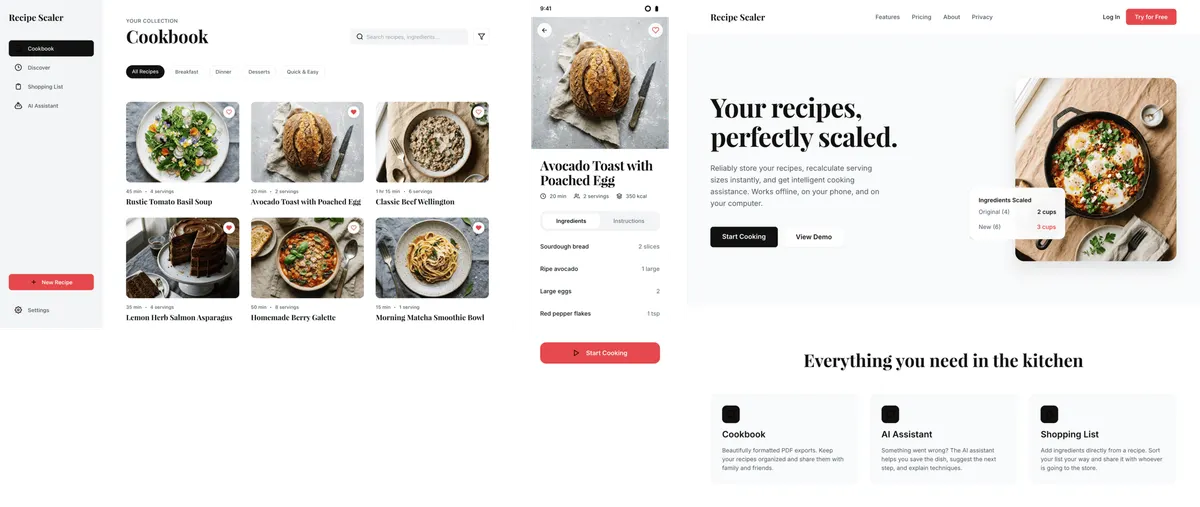
Very bad at using tools, monstrous integration into the tool
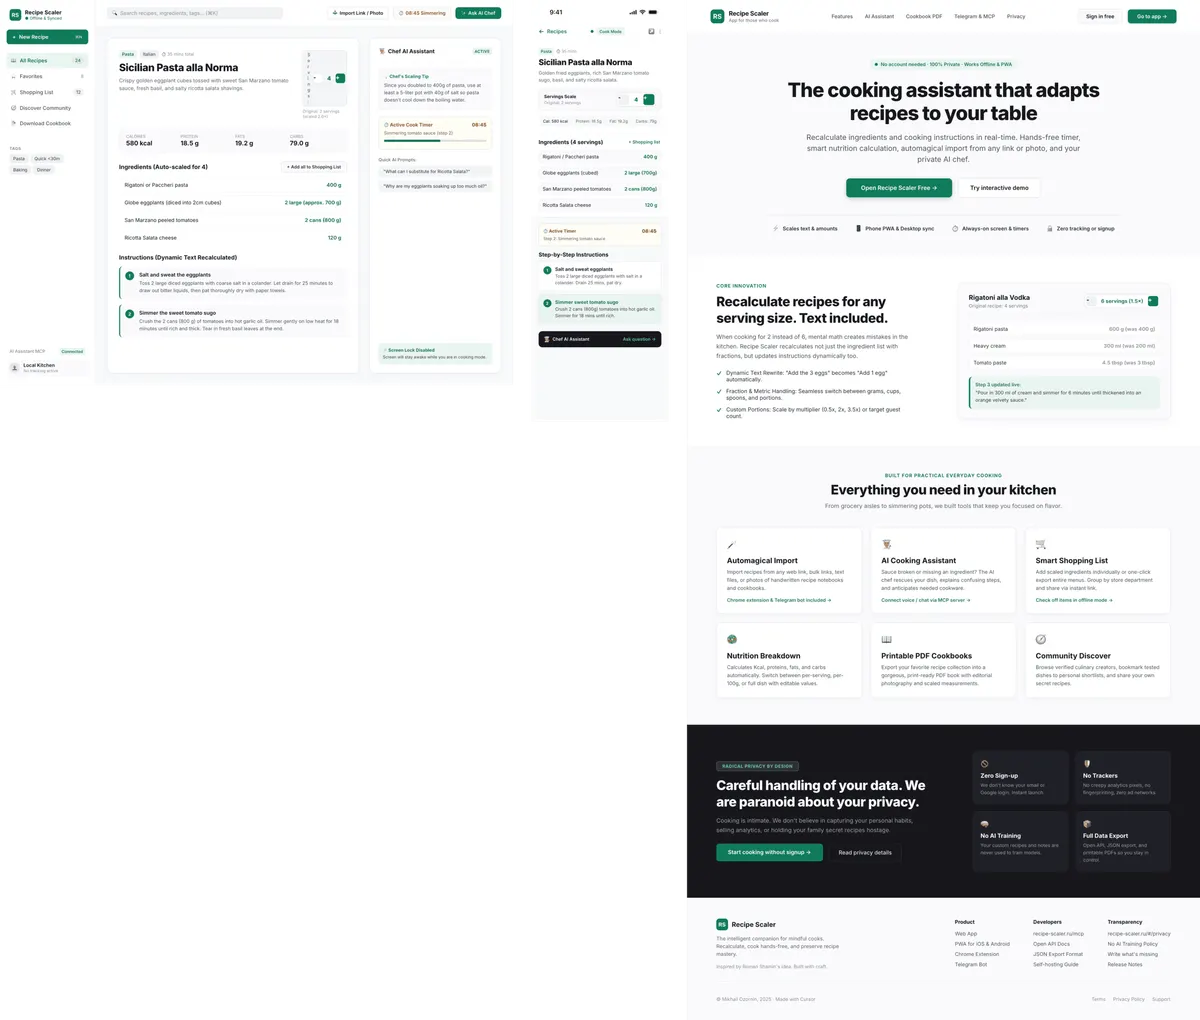
On par with Chinese models from six months ago. Weak across the board: visuals, logic, copy. Ran via OpenRouter proxy with thinking disabled (0 reasoning tokens), gemini-3.8-flash-20260902 snapshot.
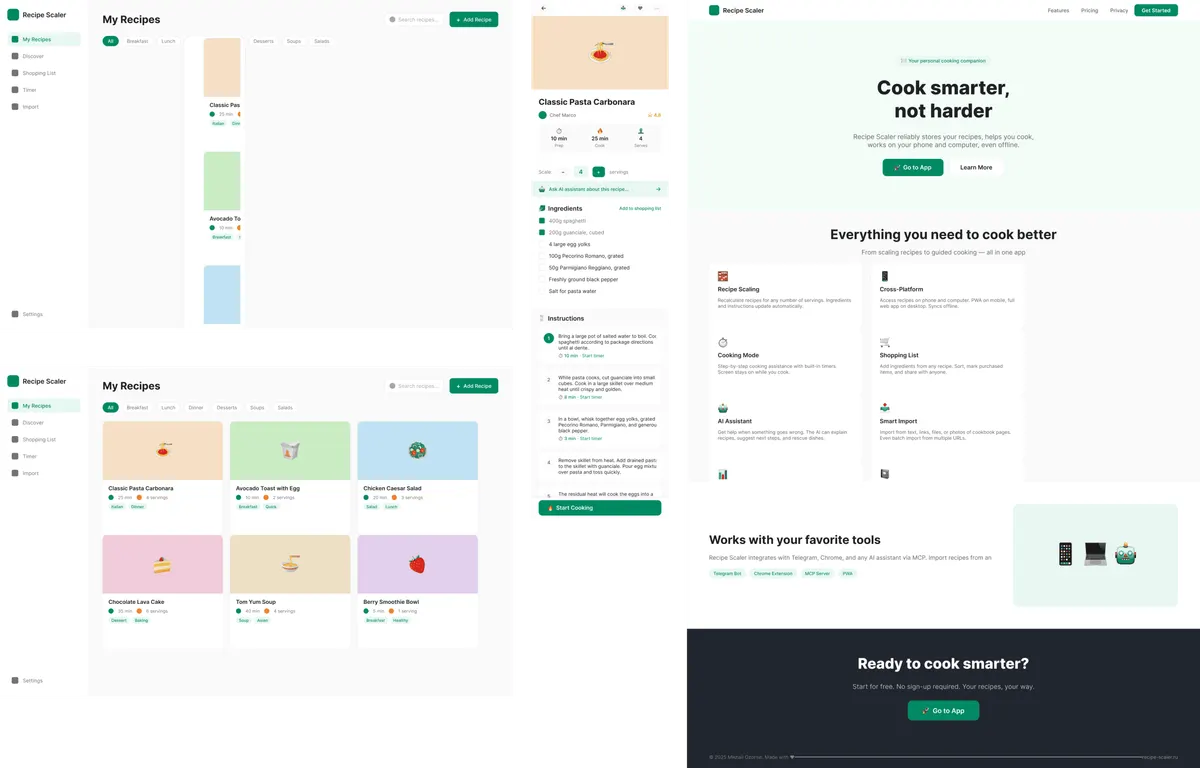
In general worse than in Paper. GLM didn't master a correct DOM
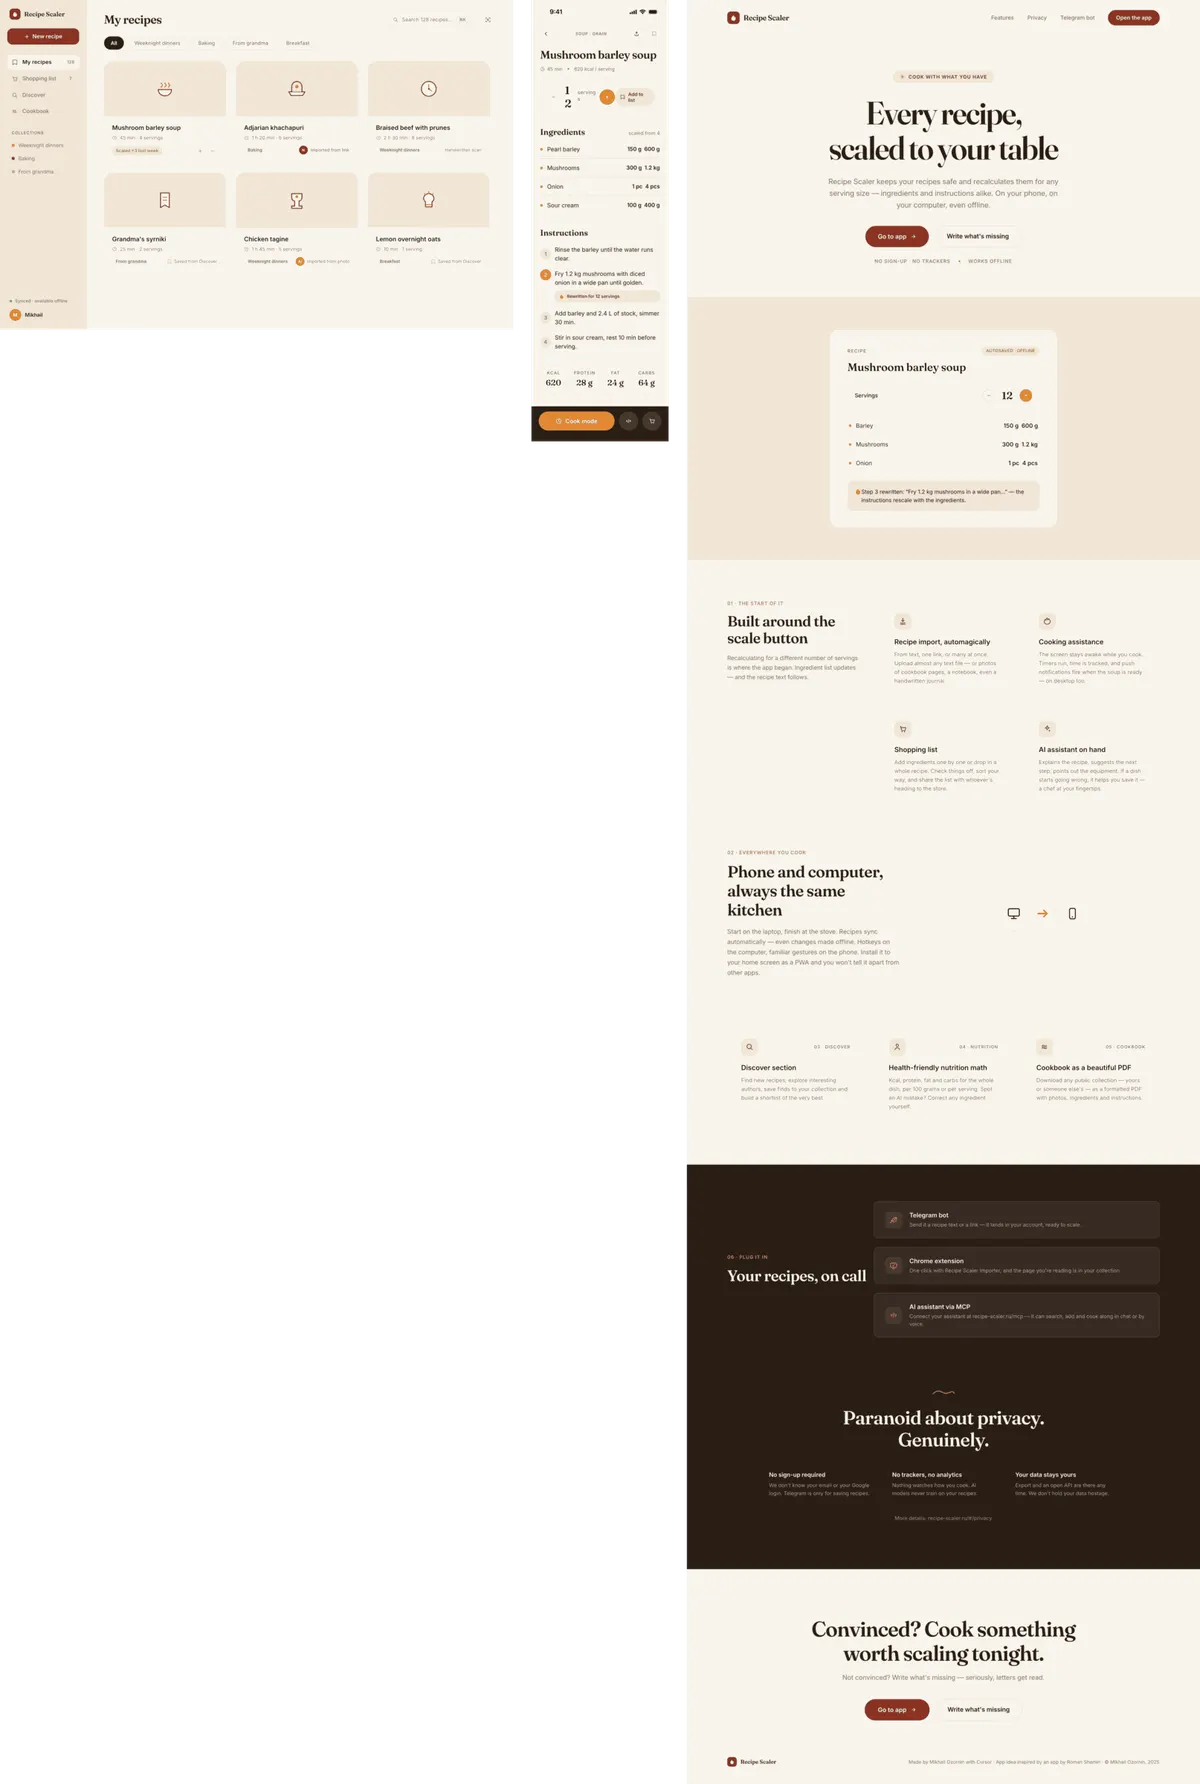
Much weaker than full GLM 5.3 Max: vision is there, but layout bugs (servings overlap, clipping) were not fixed. ~9.7M tokens in 21 min.
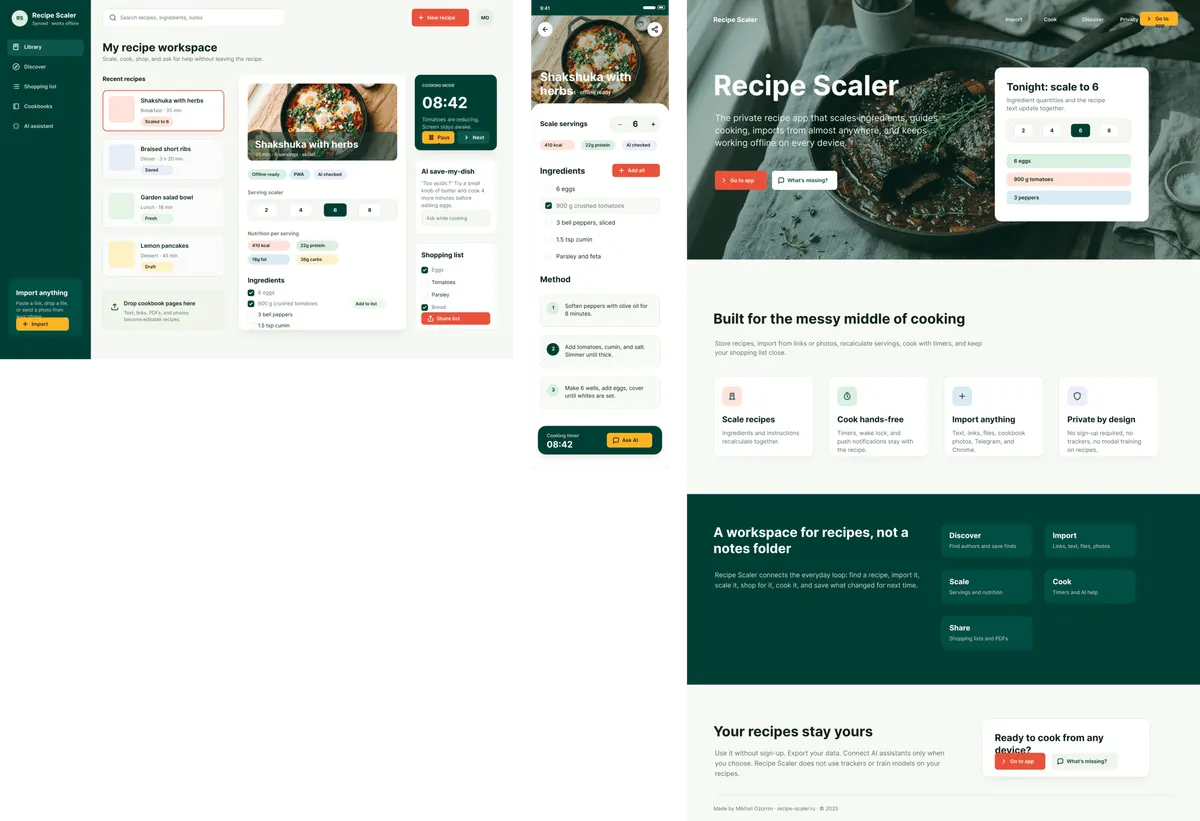
In Figma slightly better than in Paper. Lays things out monstrously simply
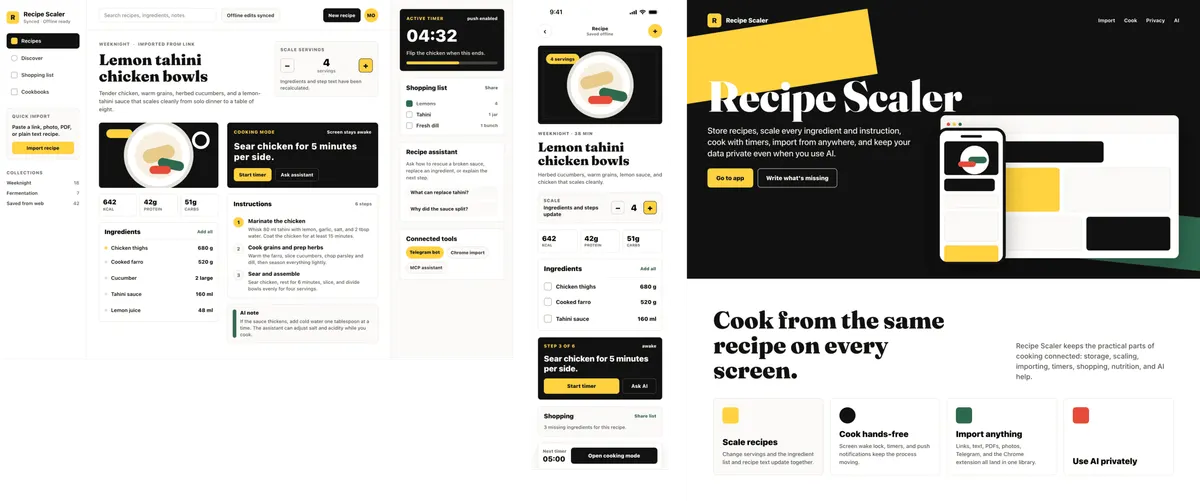
Very cheap compared to opus, the result is accordingly. The worst result among SOTA models
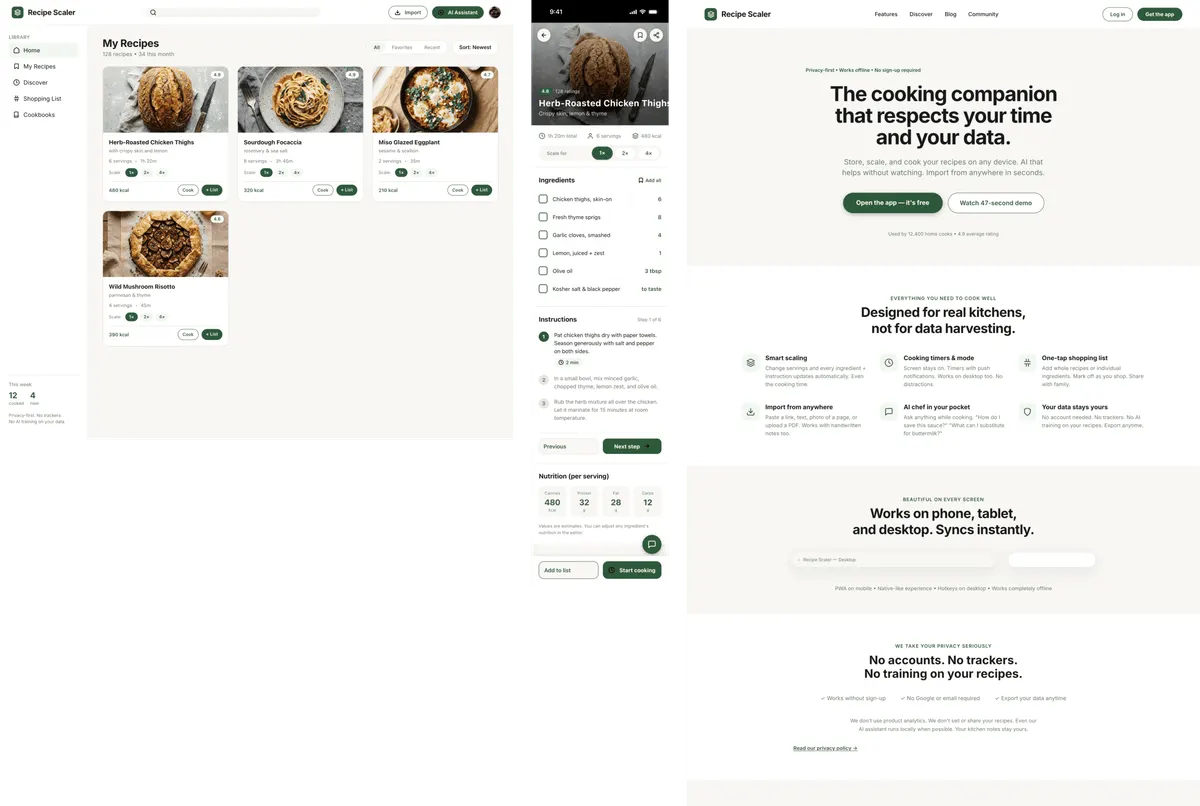
Mixed impressions. Mobile is generally fine. Promo is worse
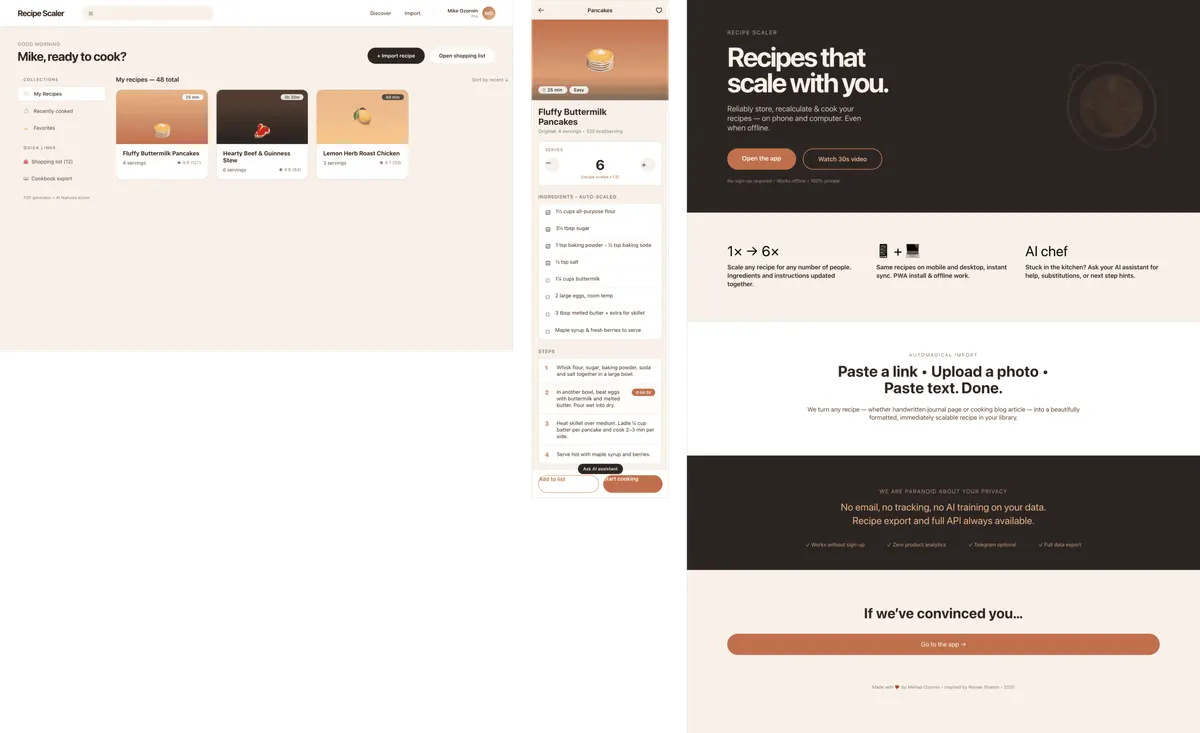
Unlike Cursor, Opencode couldn't handle the model at all
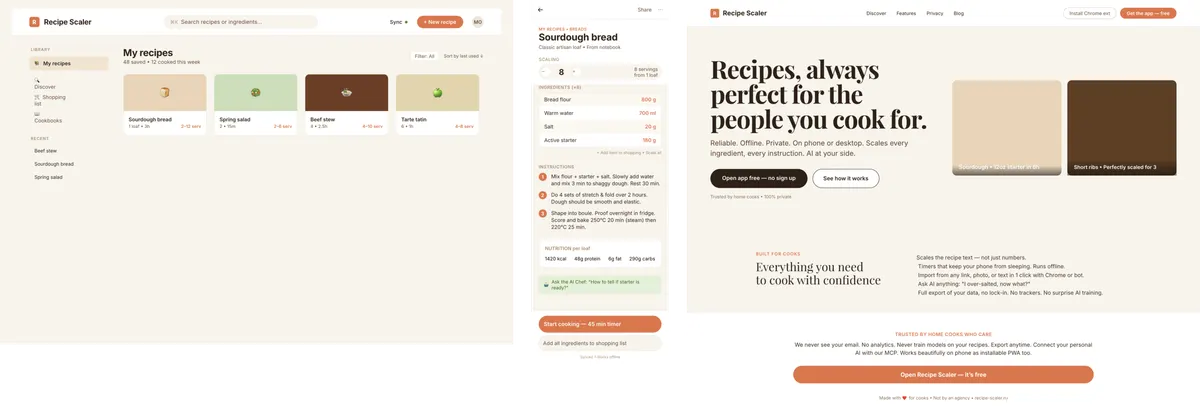
Fast, weak, expensive for this quality
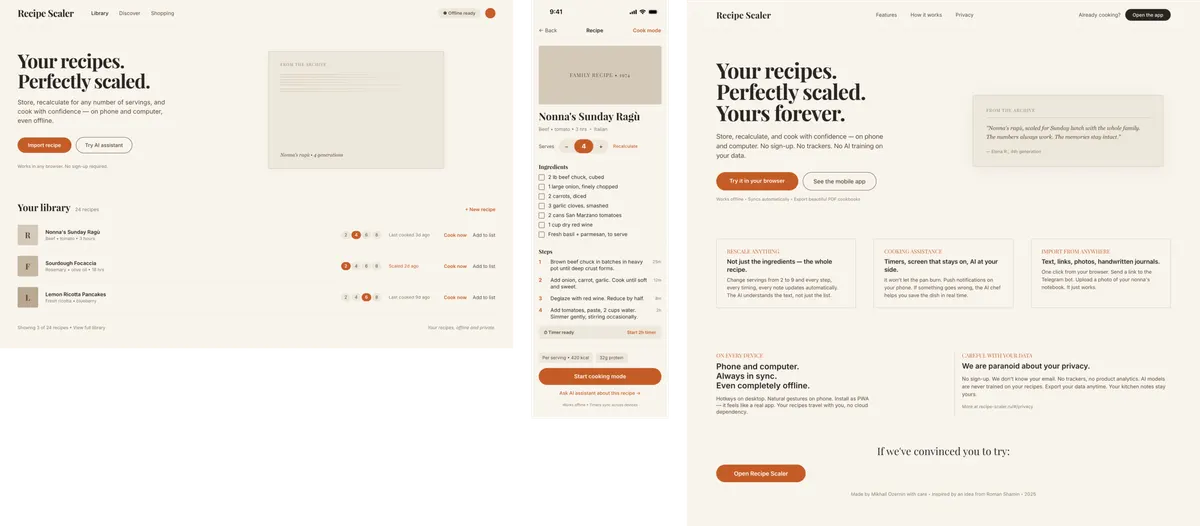
Same prompt with Google's design skill; compare with OpenCode Grok Build 0.1 without a skill
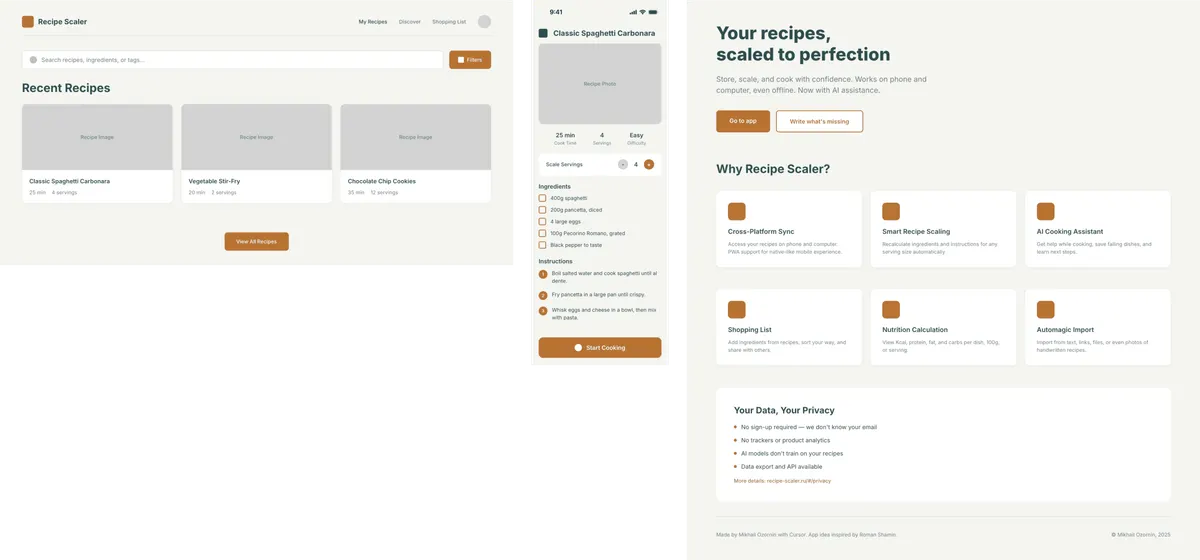
The trendiest open-source model on Openrouter. Very so-so
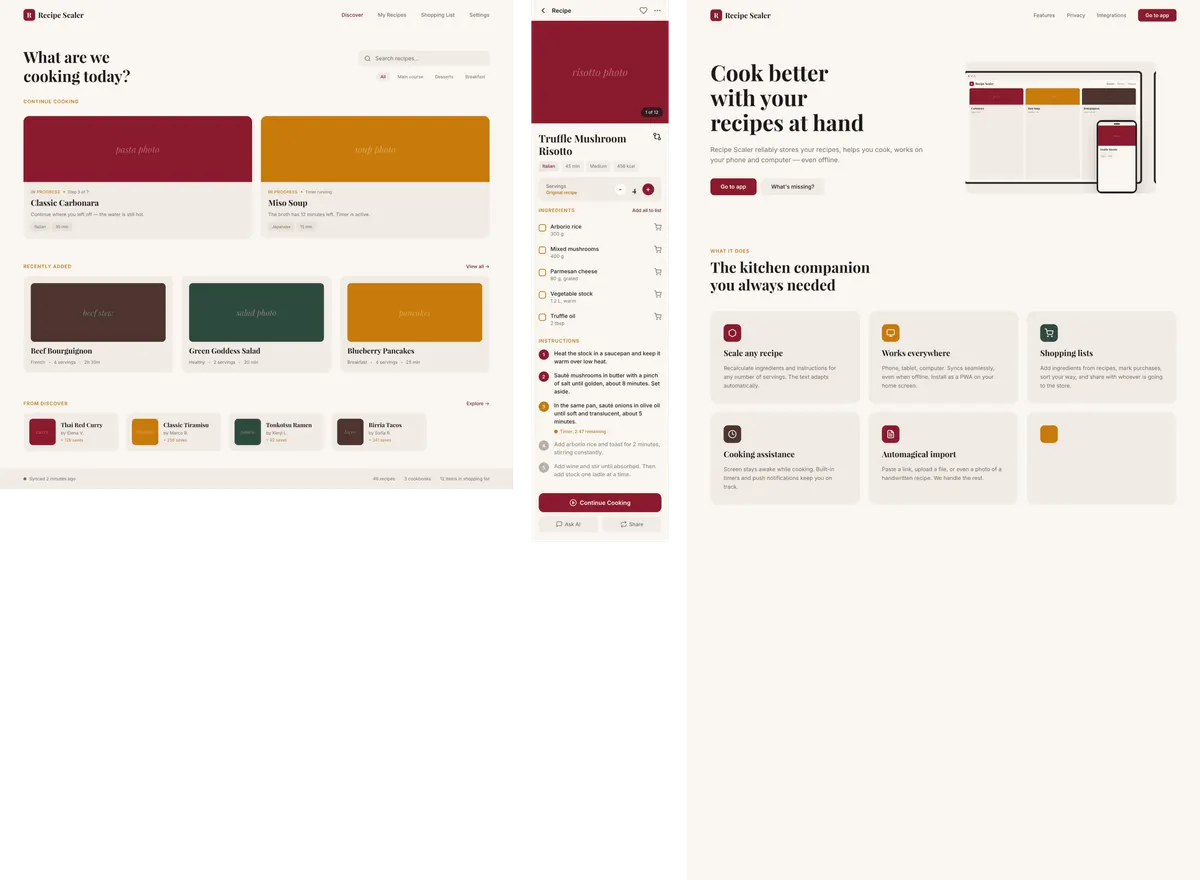
Mobile is better than the rest. Everything was duplicated, then erased via screenshots — 40+ minutes
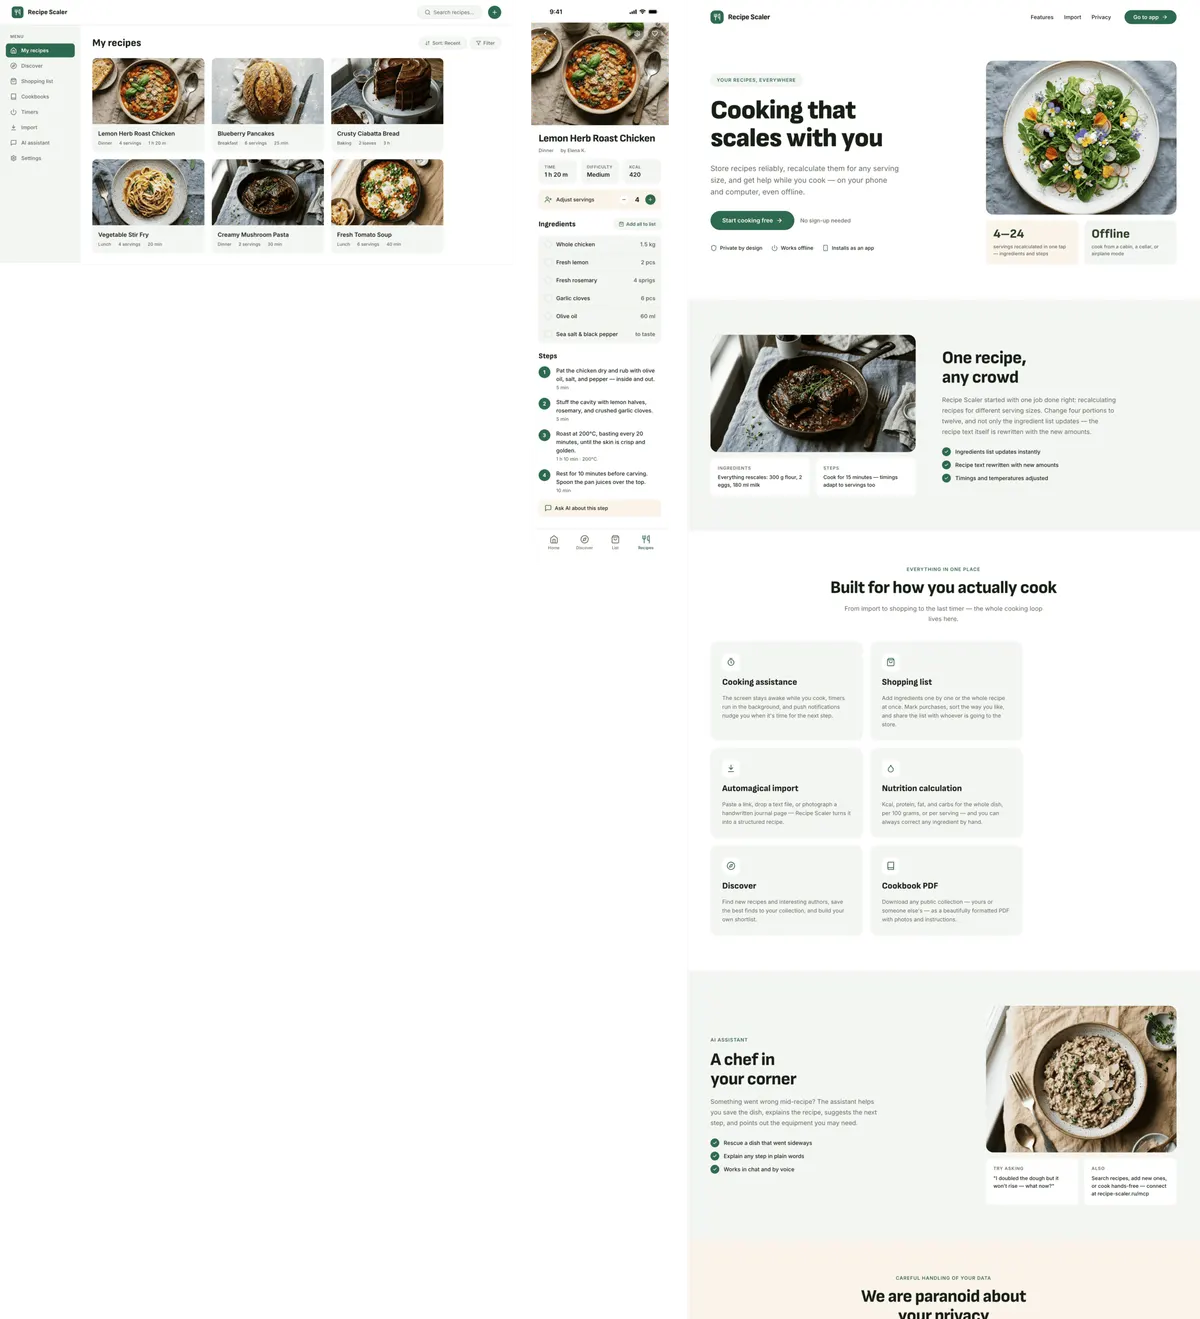
Weak at the high end. Upside: comparable to K3.
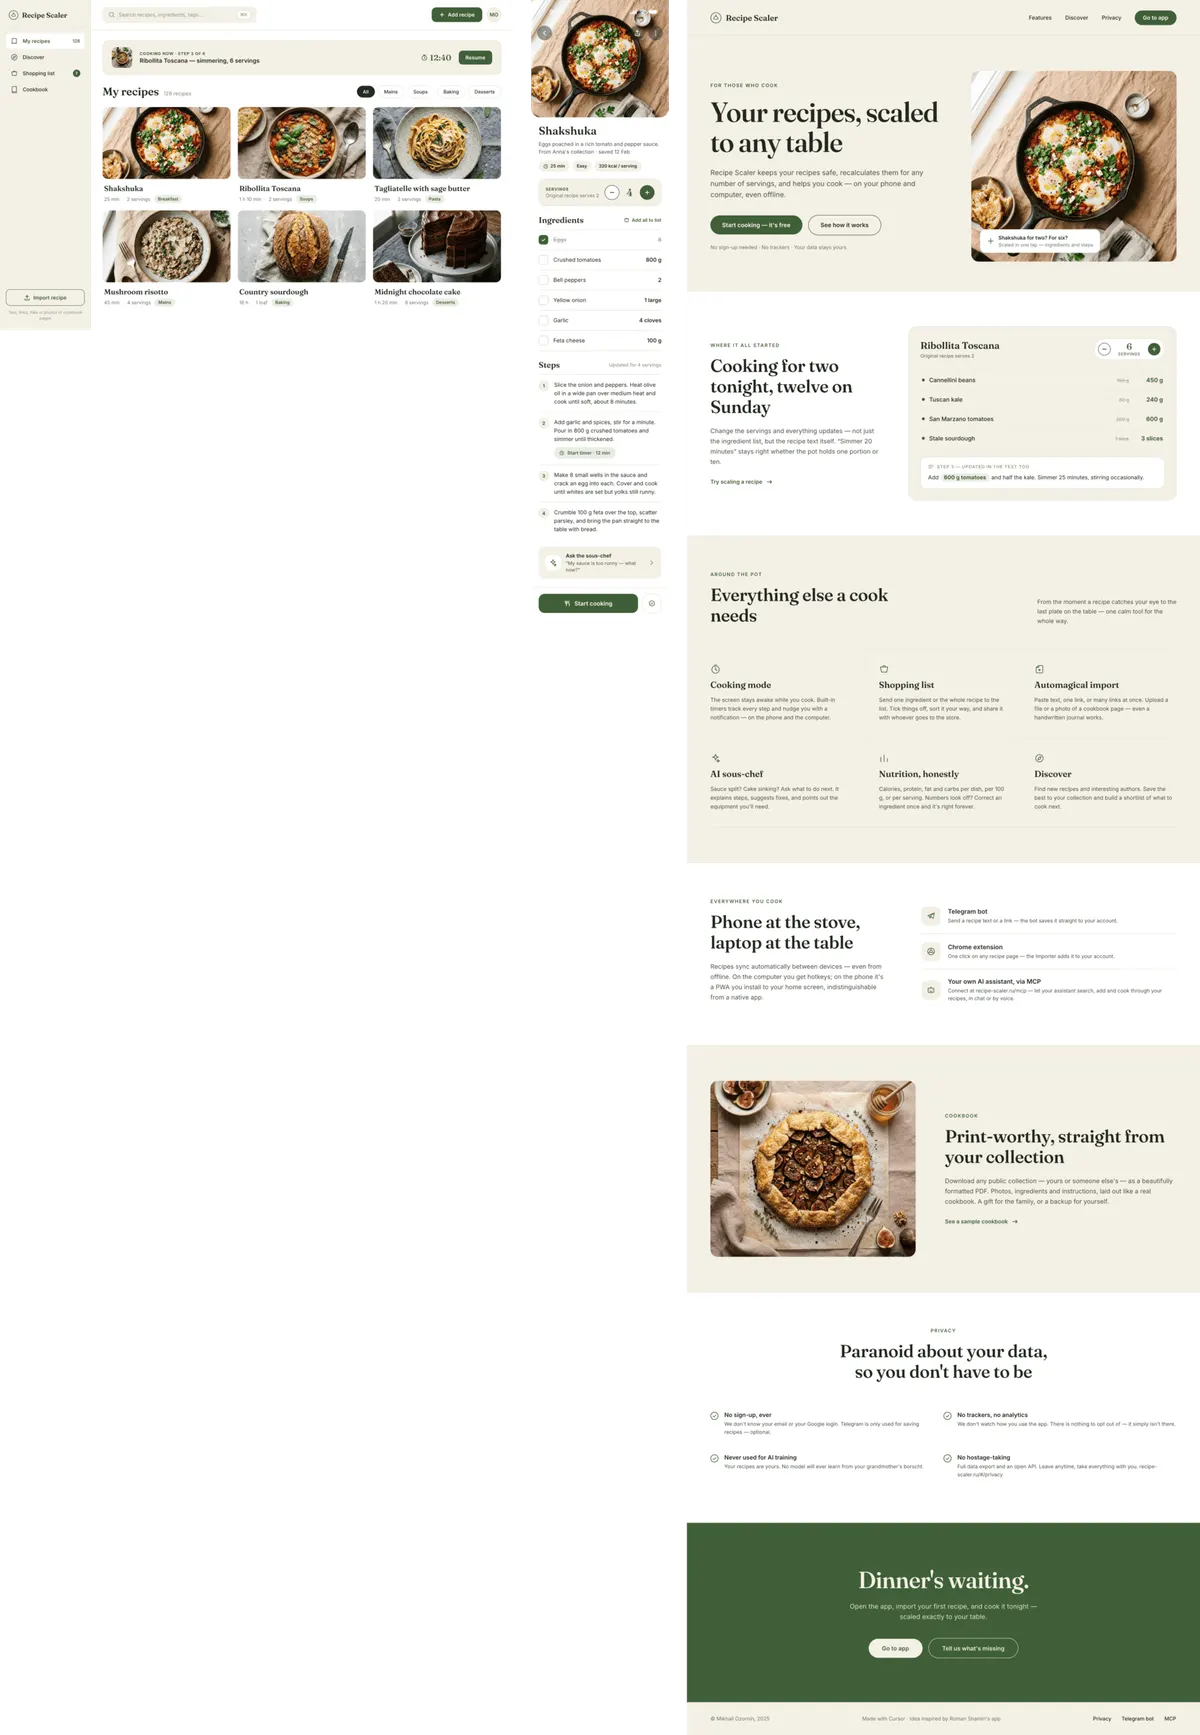
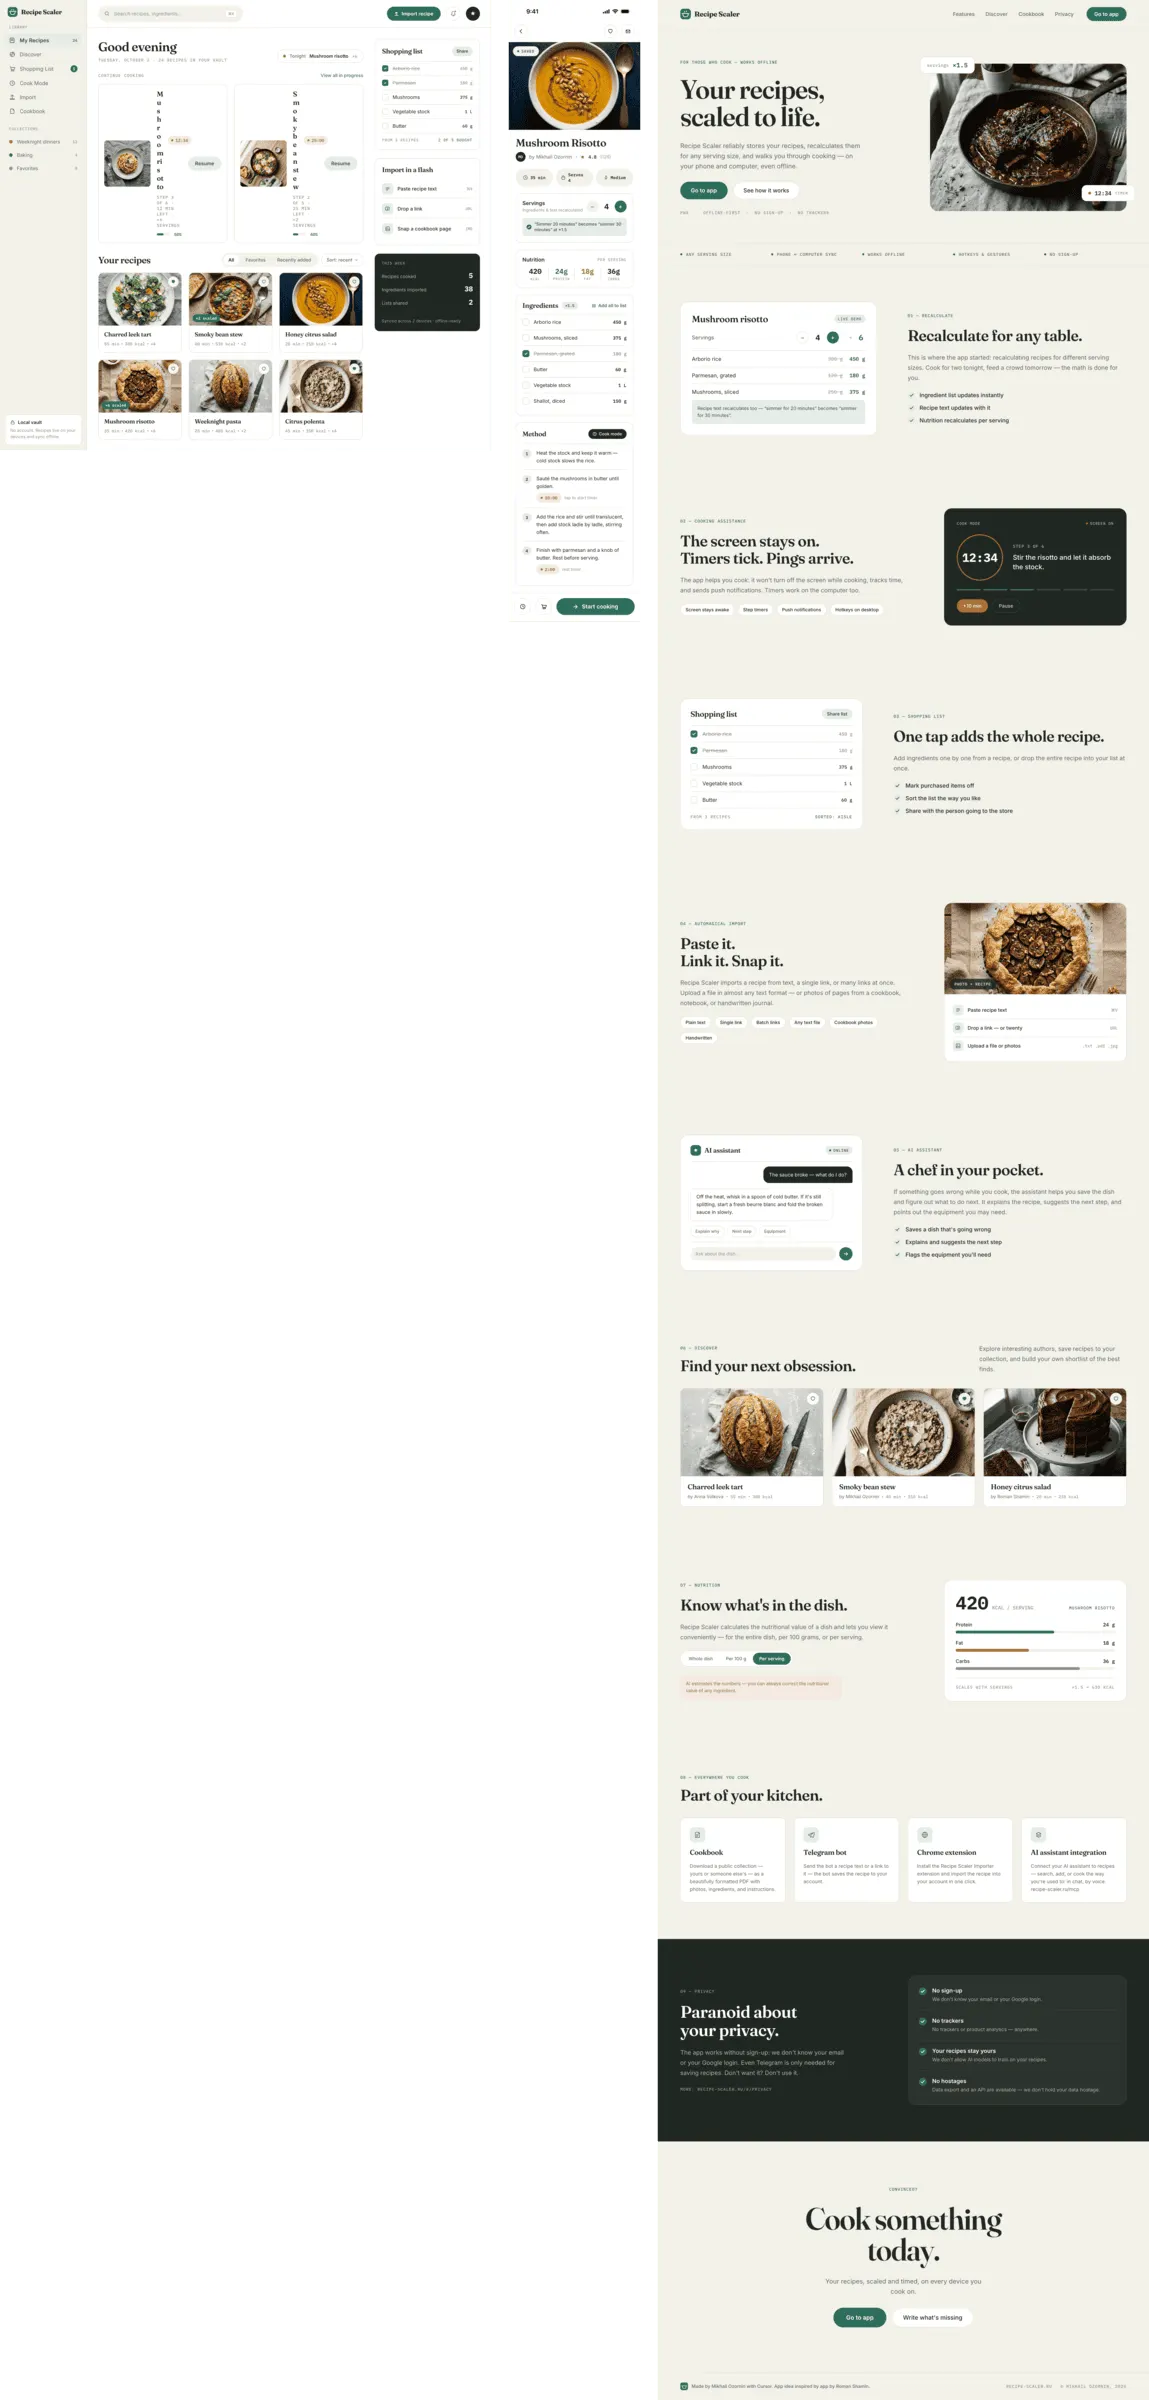
Nothing interesting overall; it would be mid if it had handled autolayout. Mobile is well structured, the rest is worse.
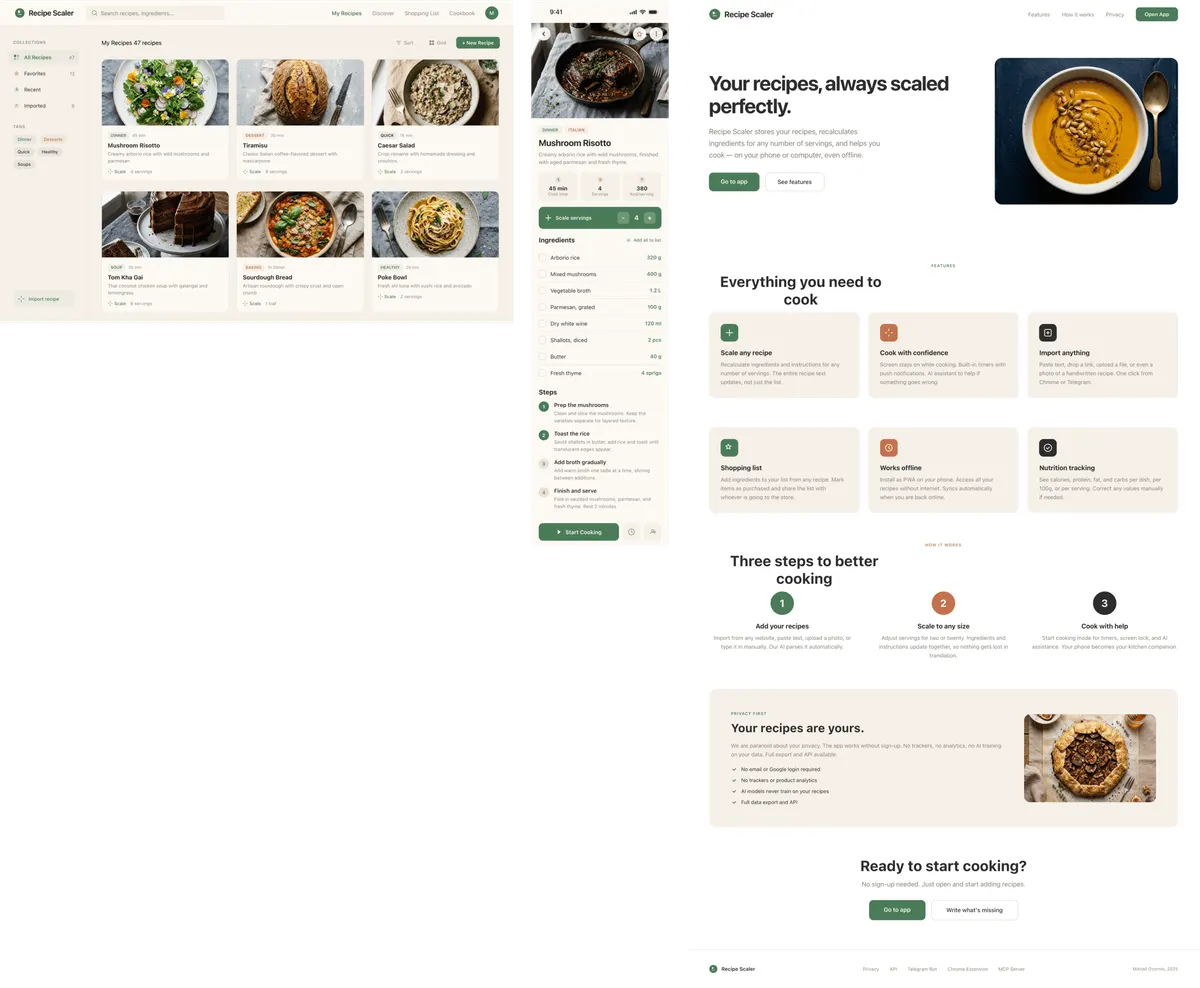
Included Cursor model; very cheap in subscription terms, weak on design
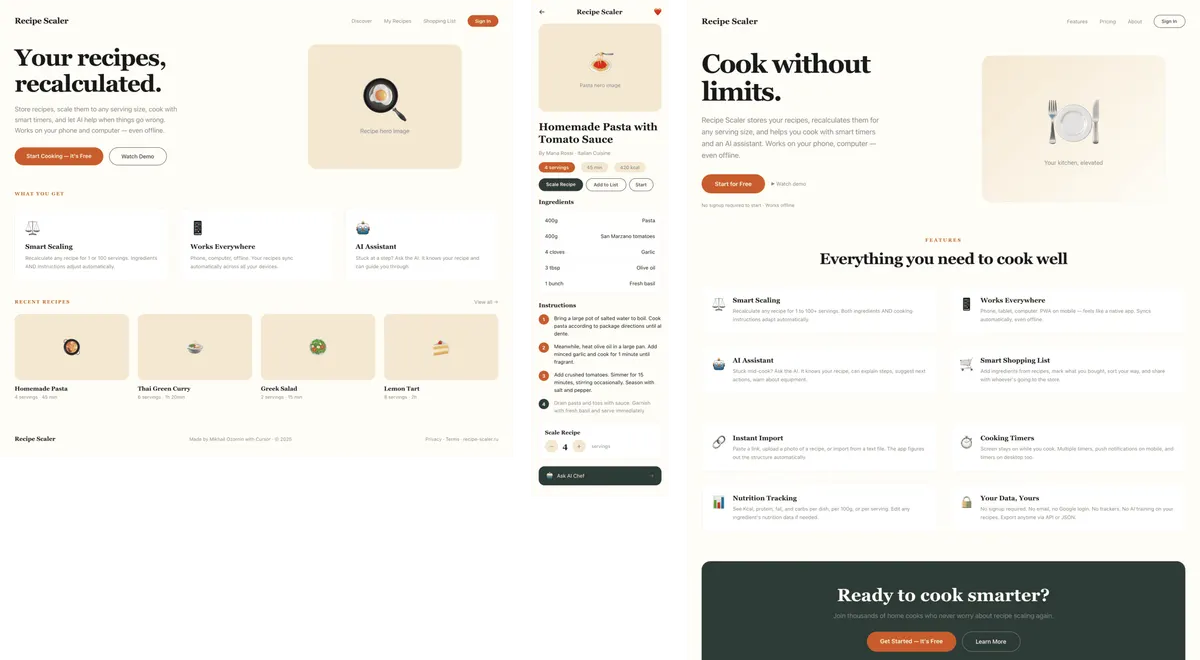
Incredibly fast, incredibly cheap, the quality is accordingly
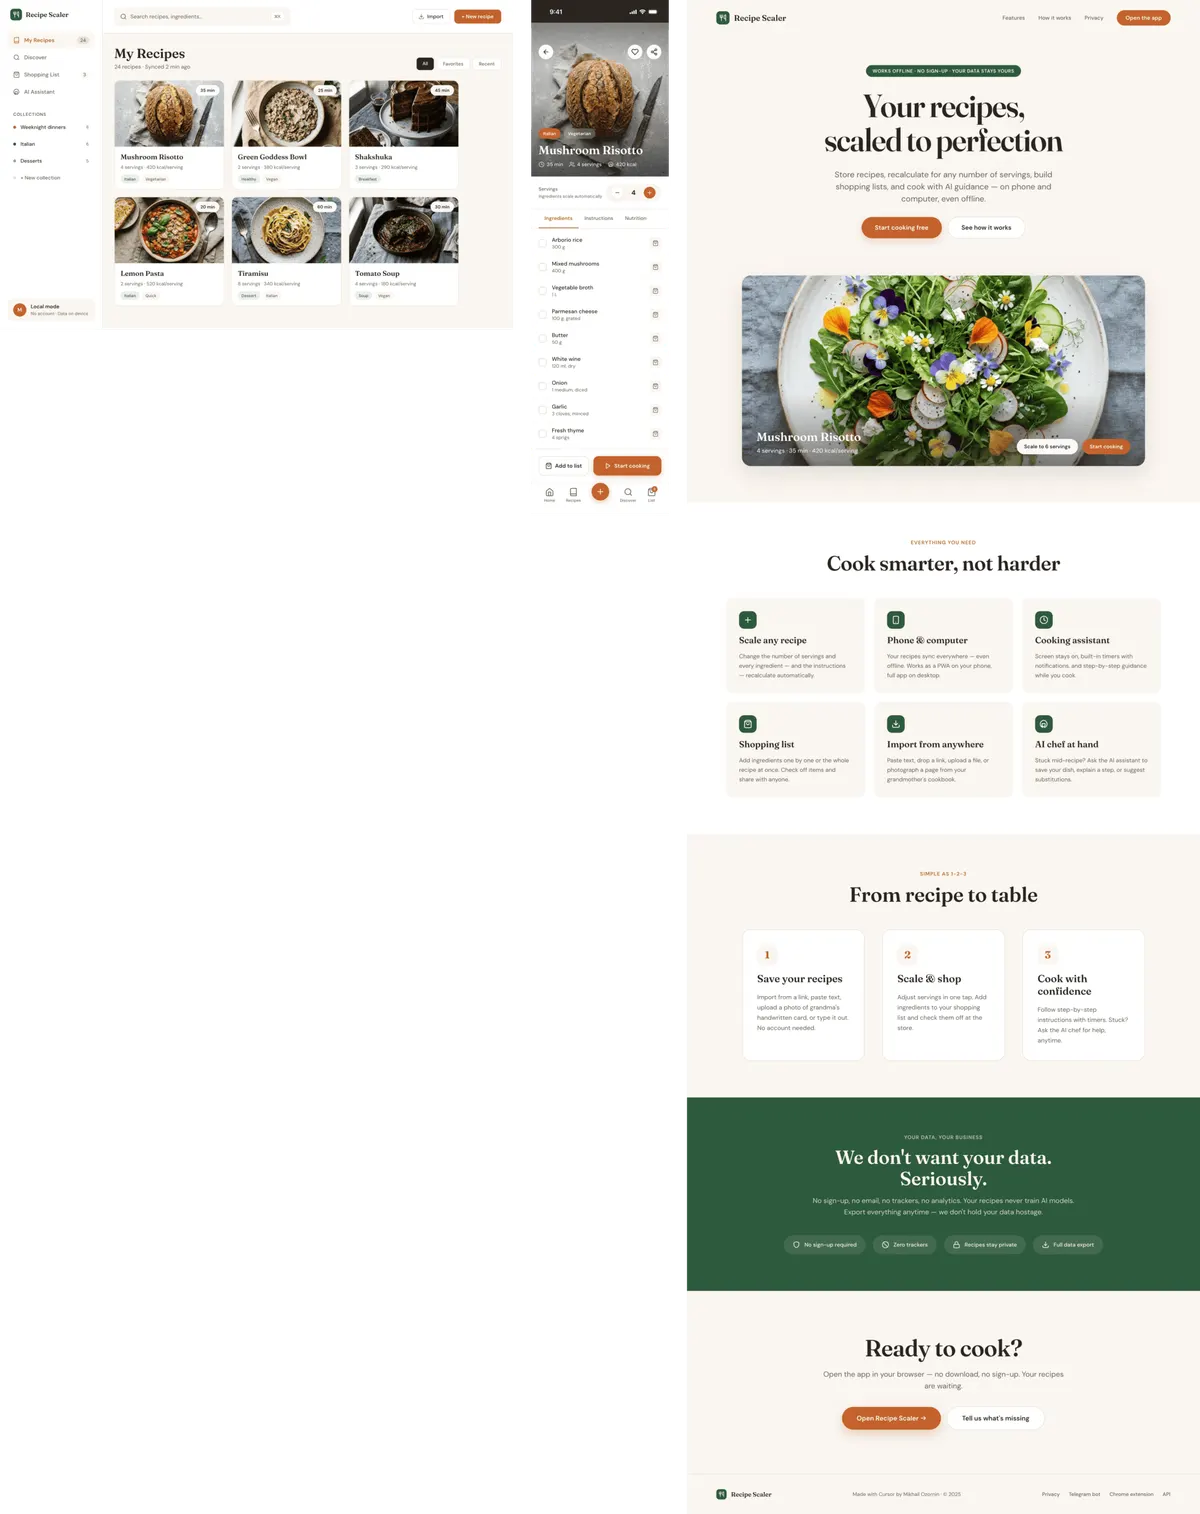
The best of the country's top-3 models, but it can't really catch the top-2 and top-1 models. Weak all around.
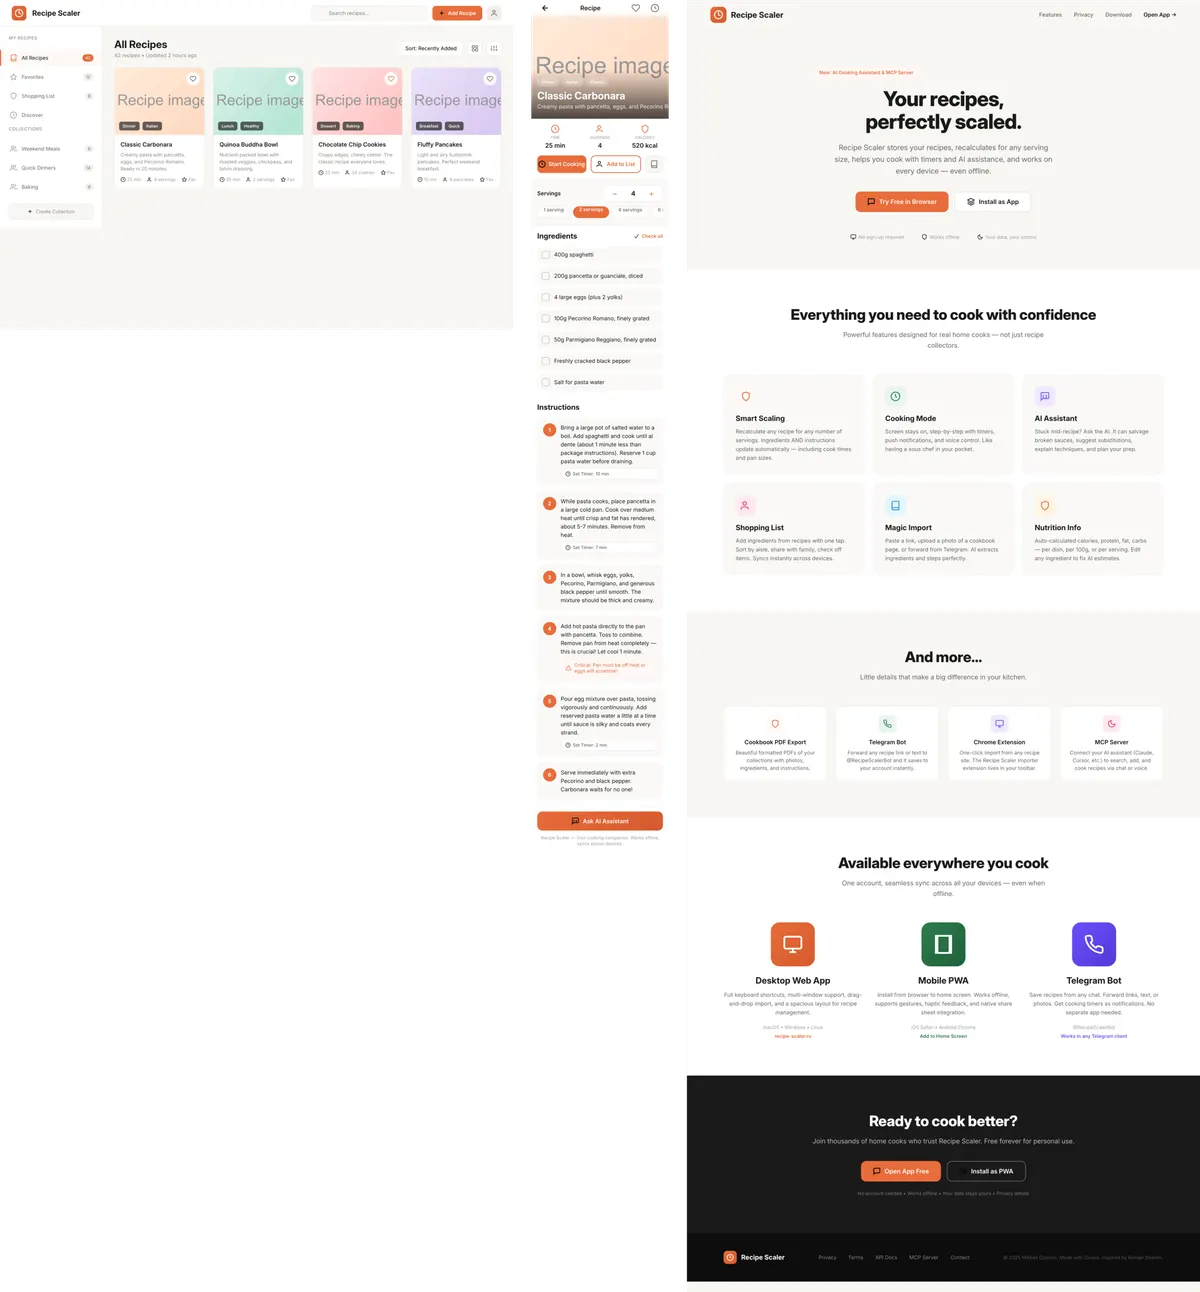
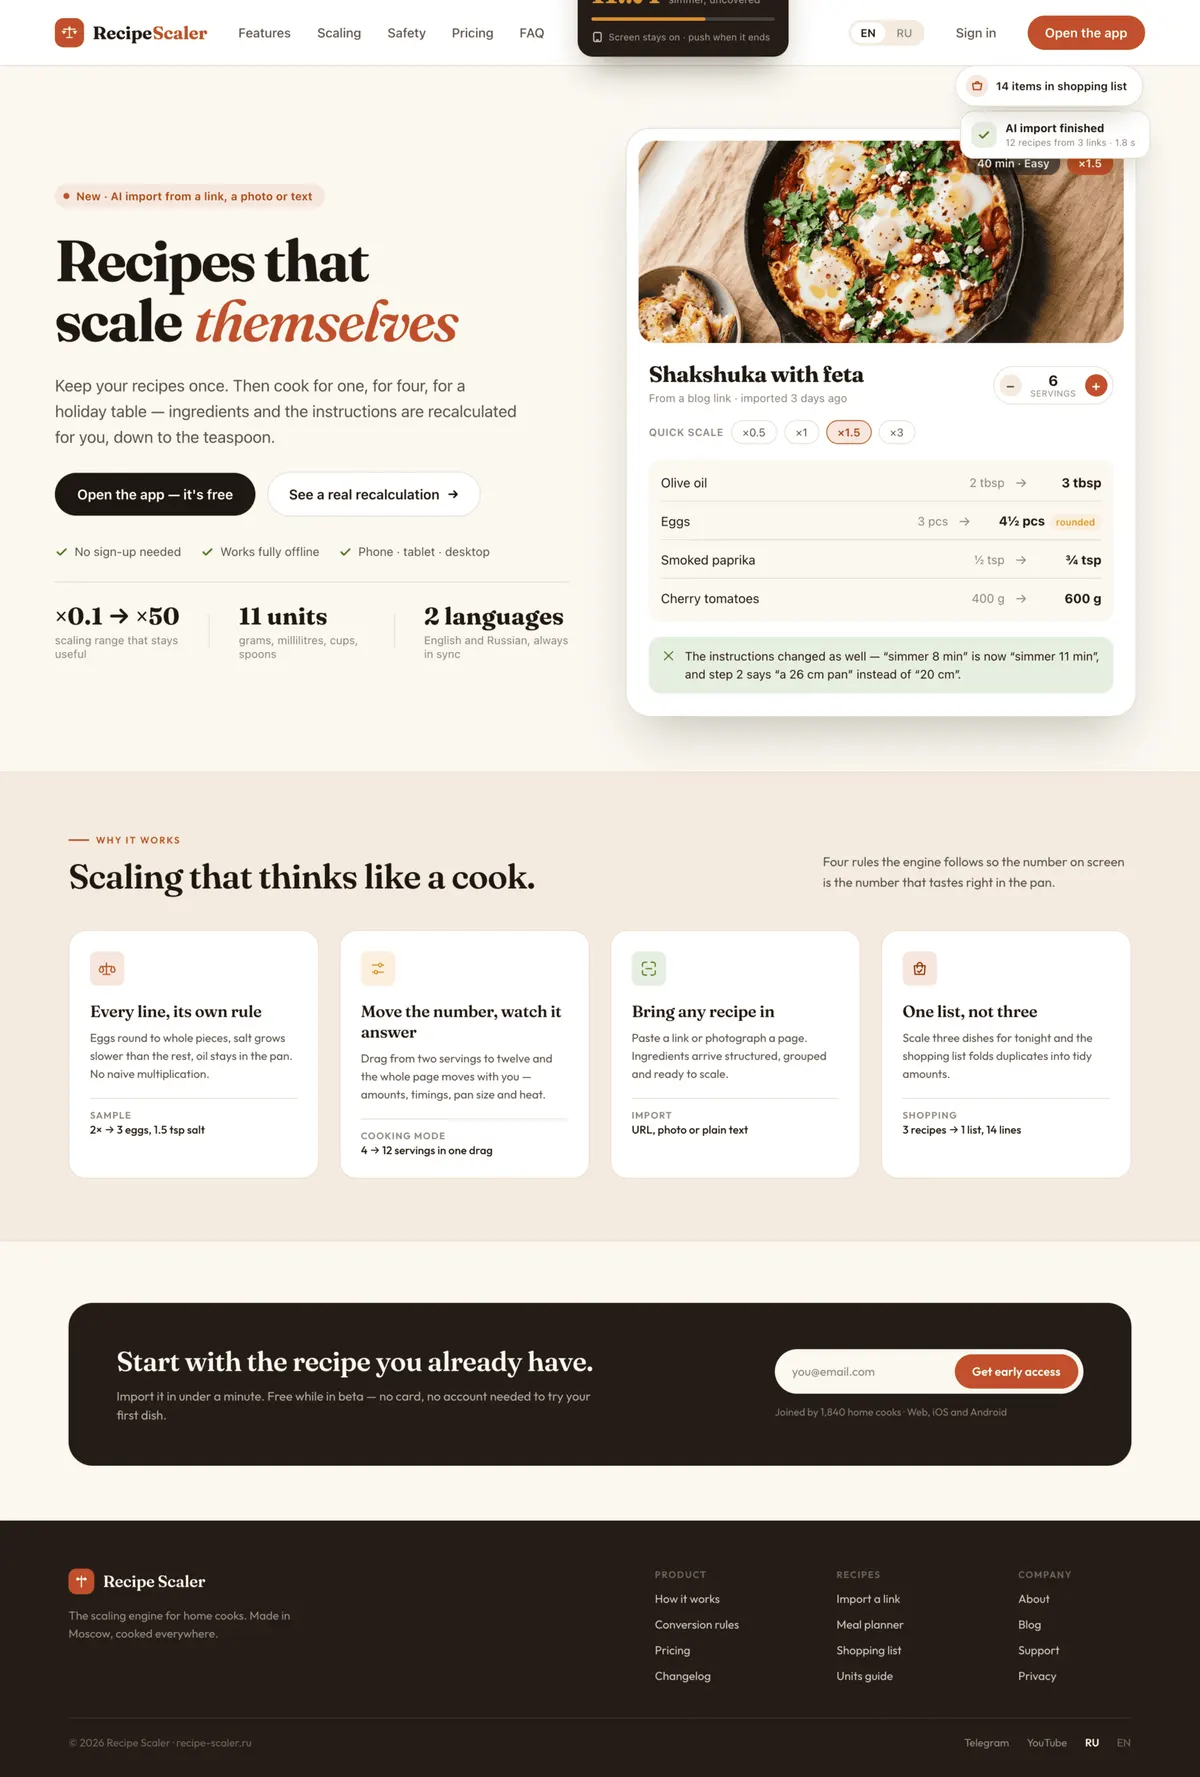
Couldn't wait for it to finish — showing the result after 1 h 11 min. Only the promo page of the three screens was done.
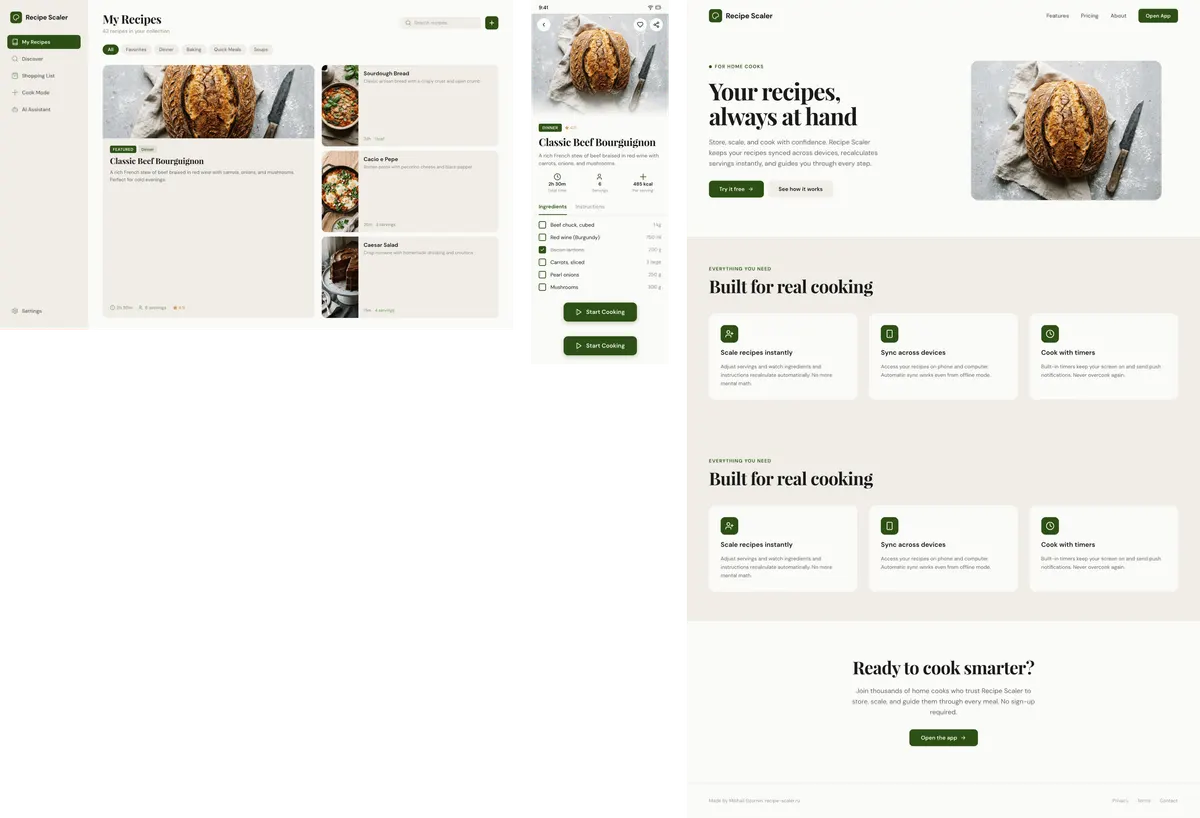
Expensive for its result, no improvement over 3.6 Max. Very bad at using tools
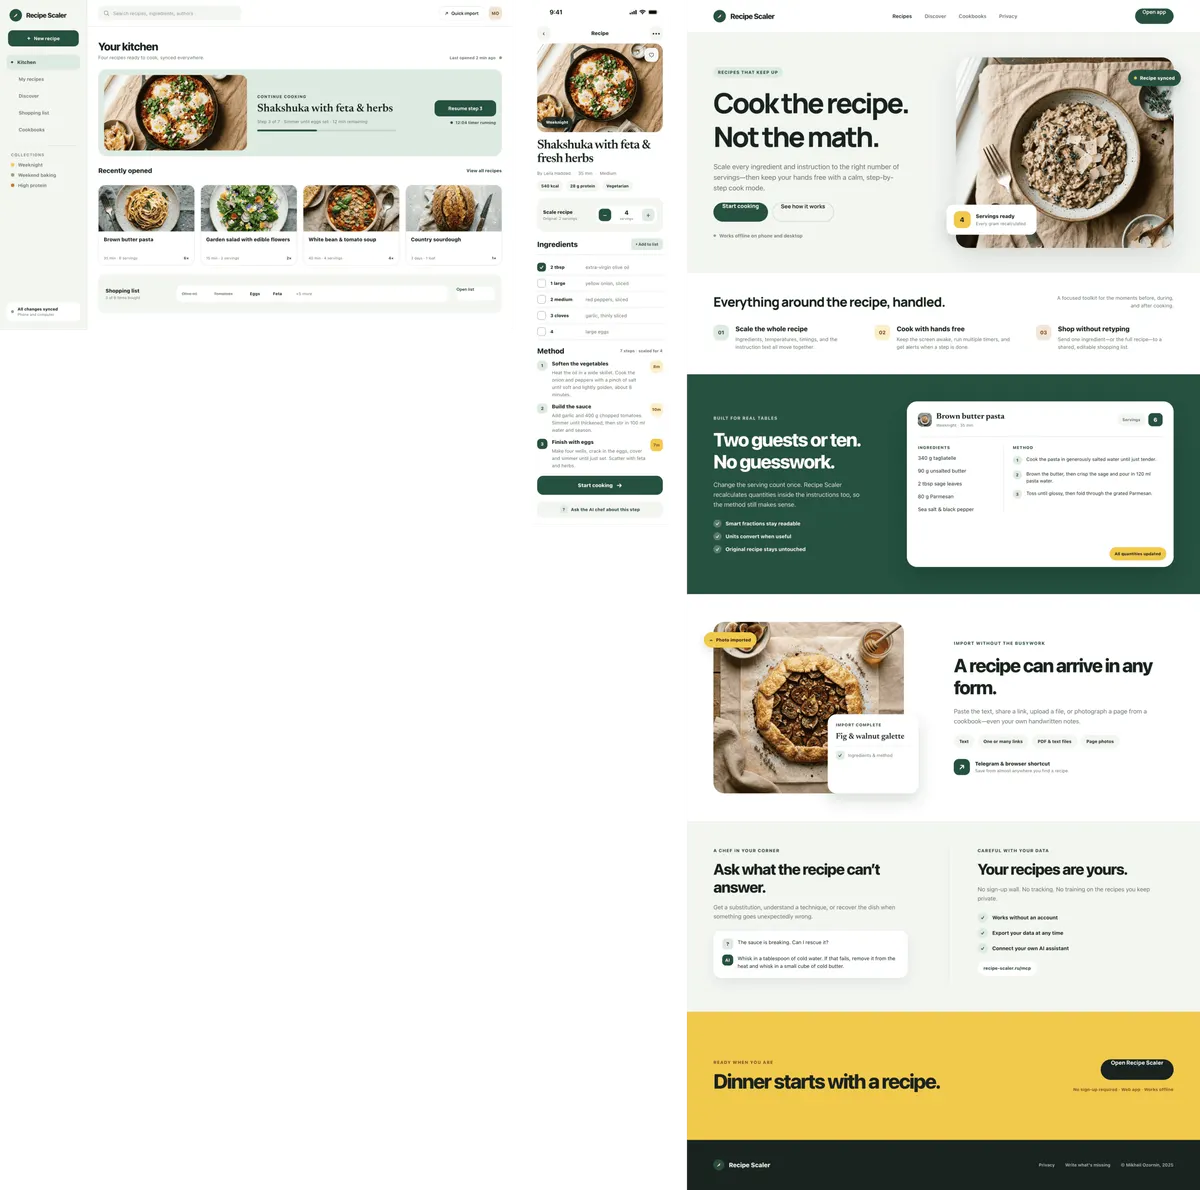
Weak across the board: layout, the "app" idea, the copy.
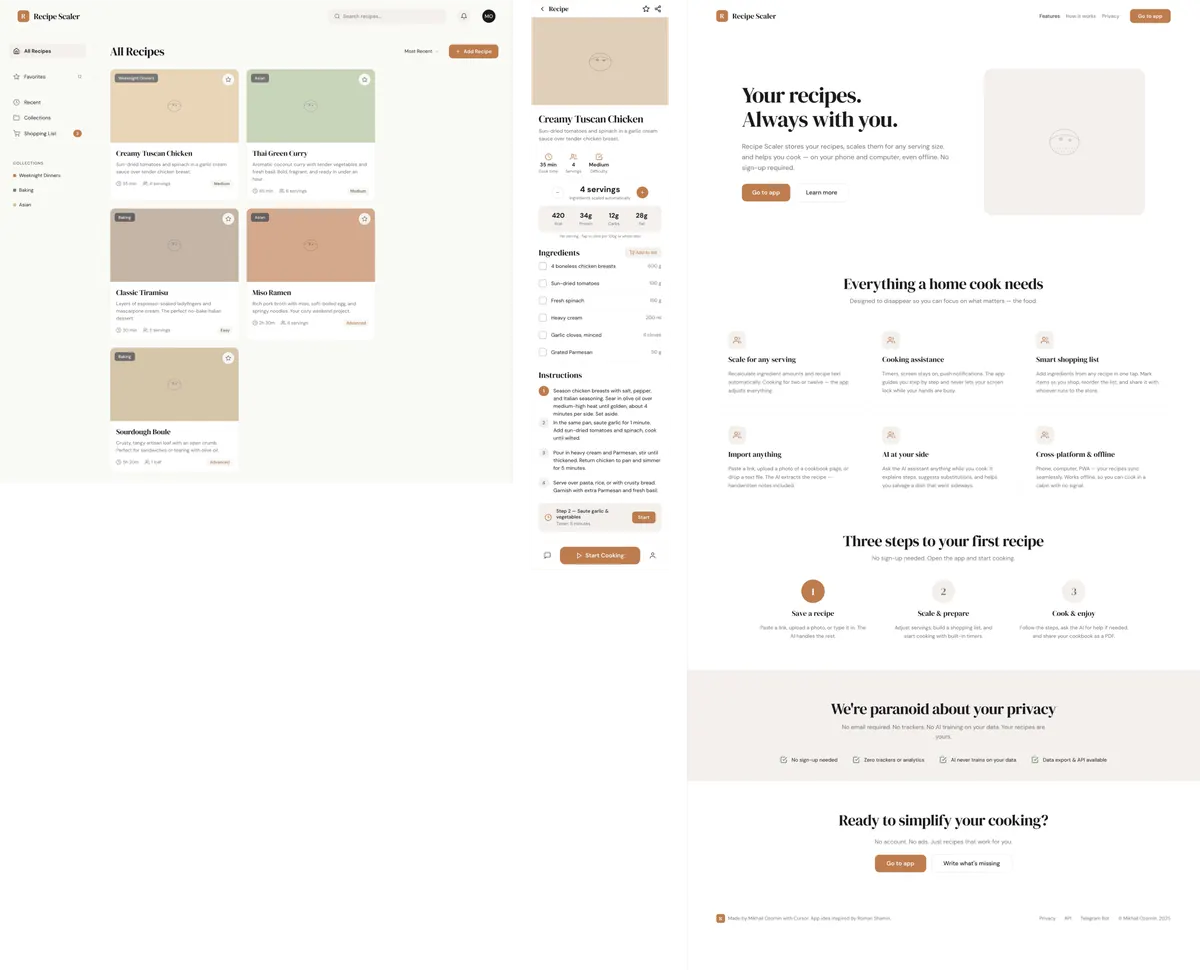
DeepSeek is very cheap, but managed only once. Mobile is watchable
DeepSeek is very cheap, but managed only once. Mobile is watchable
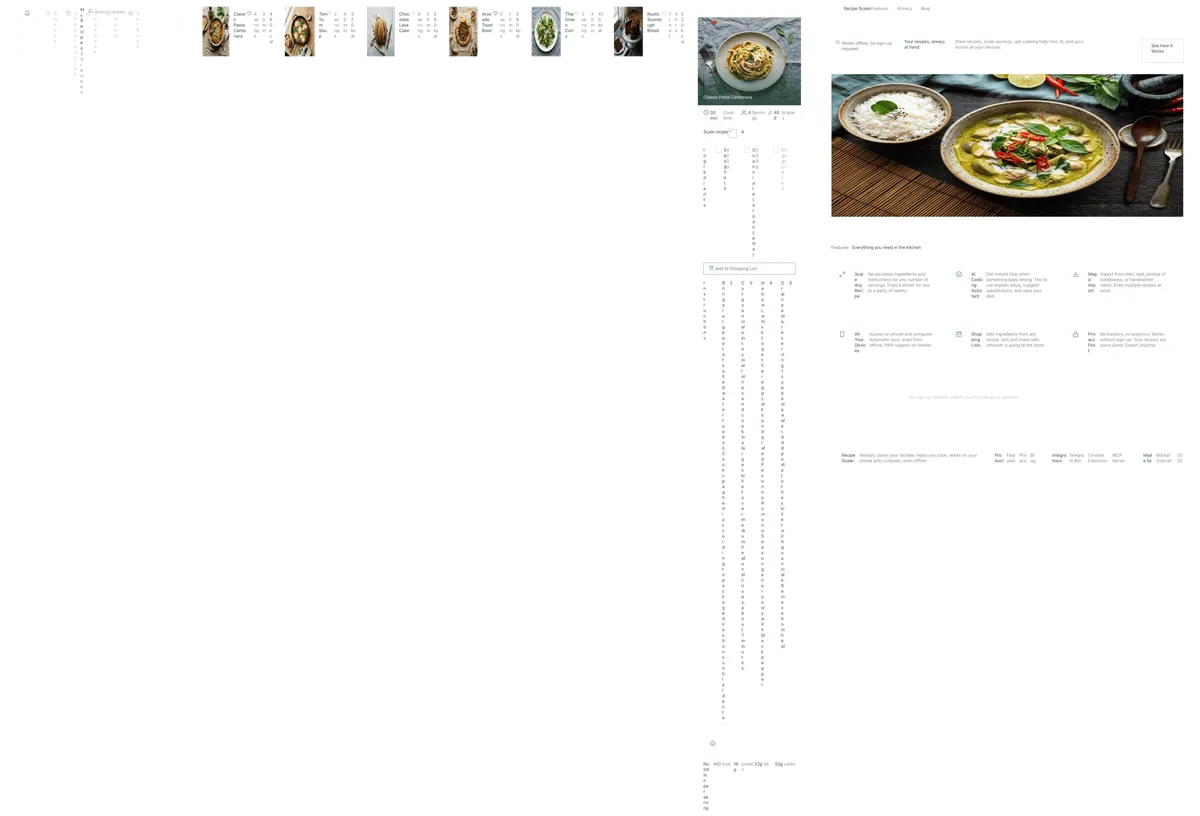
GLM in Cursor for some reason couldn't cope with the tools
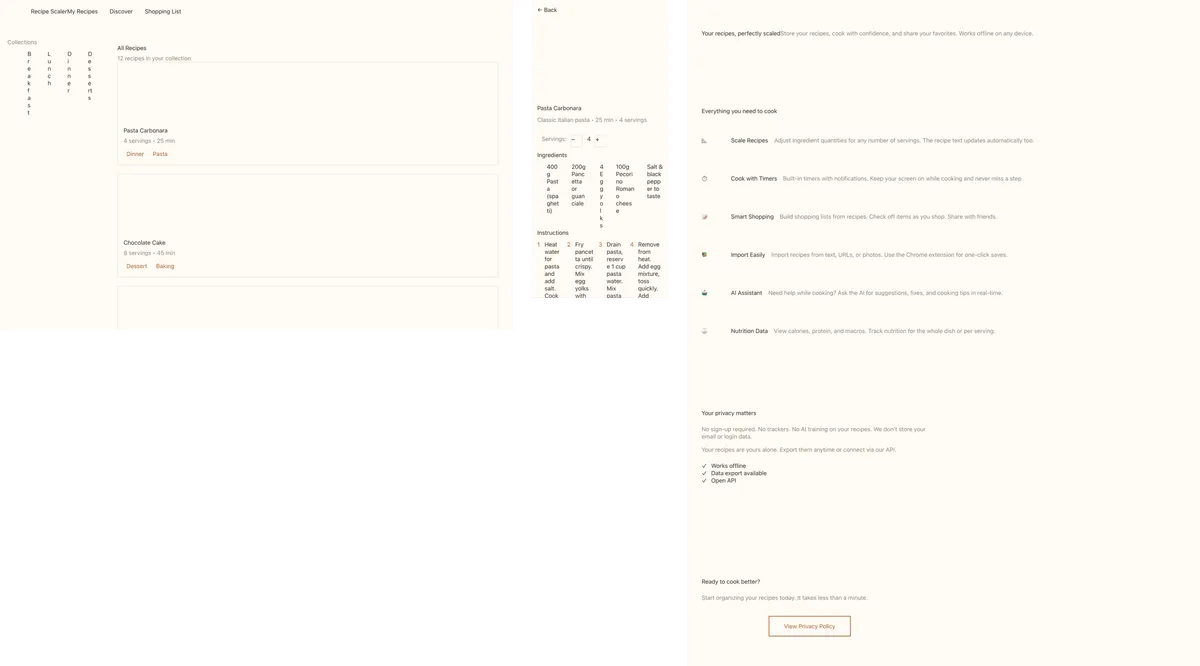
Didn't even cope with the tools. There's not a single reason to use it
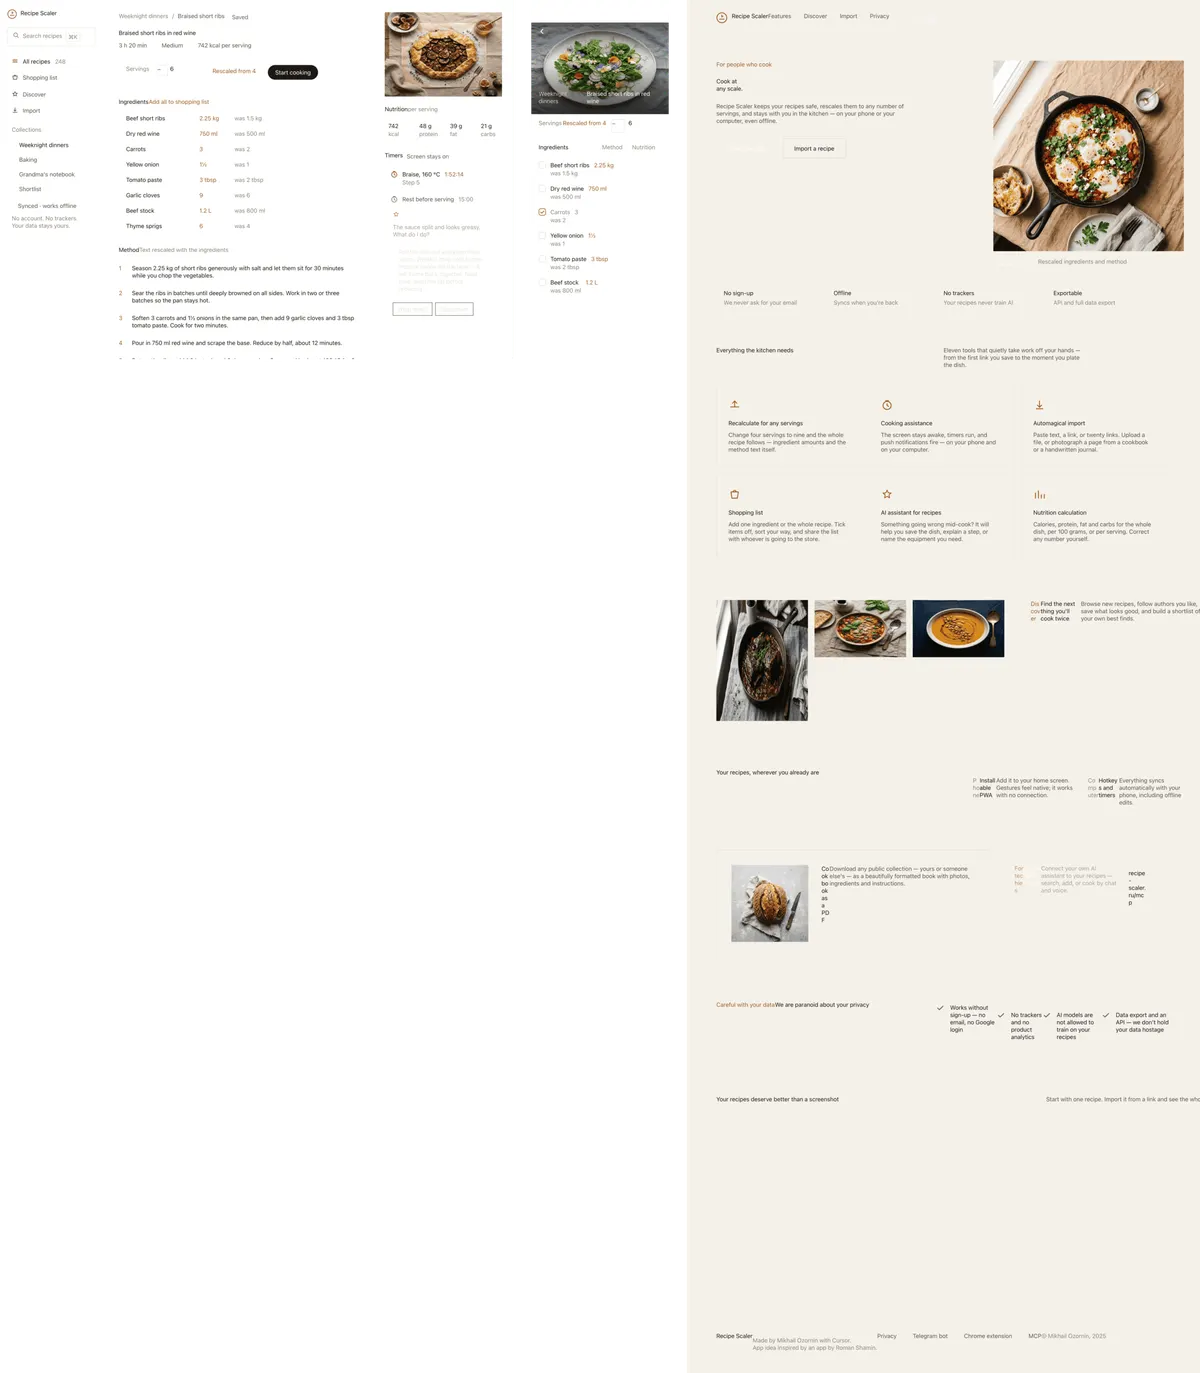
Very bad — failed the tools so hard it burned through the 100-call free-tier MCP limit. Models usually get by on half of that.
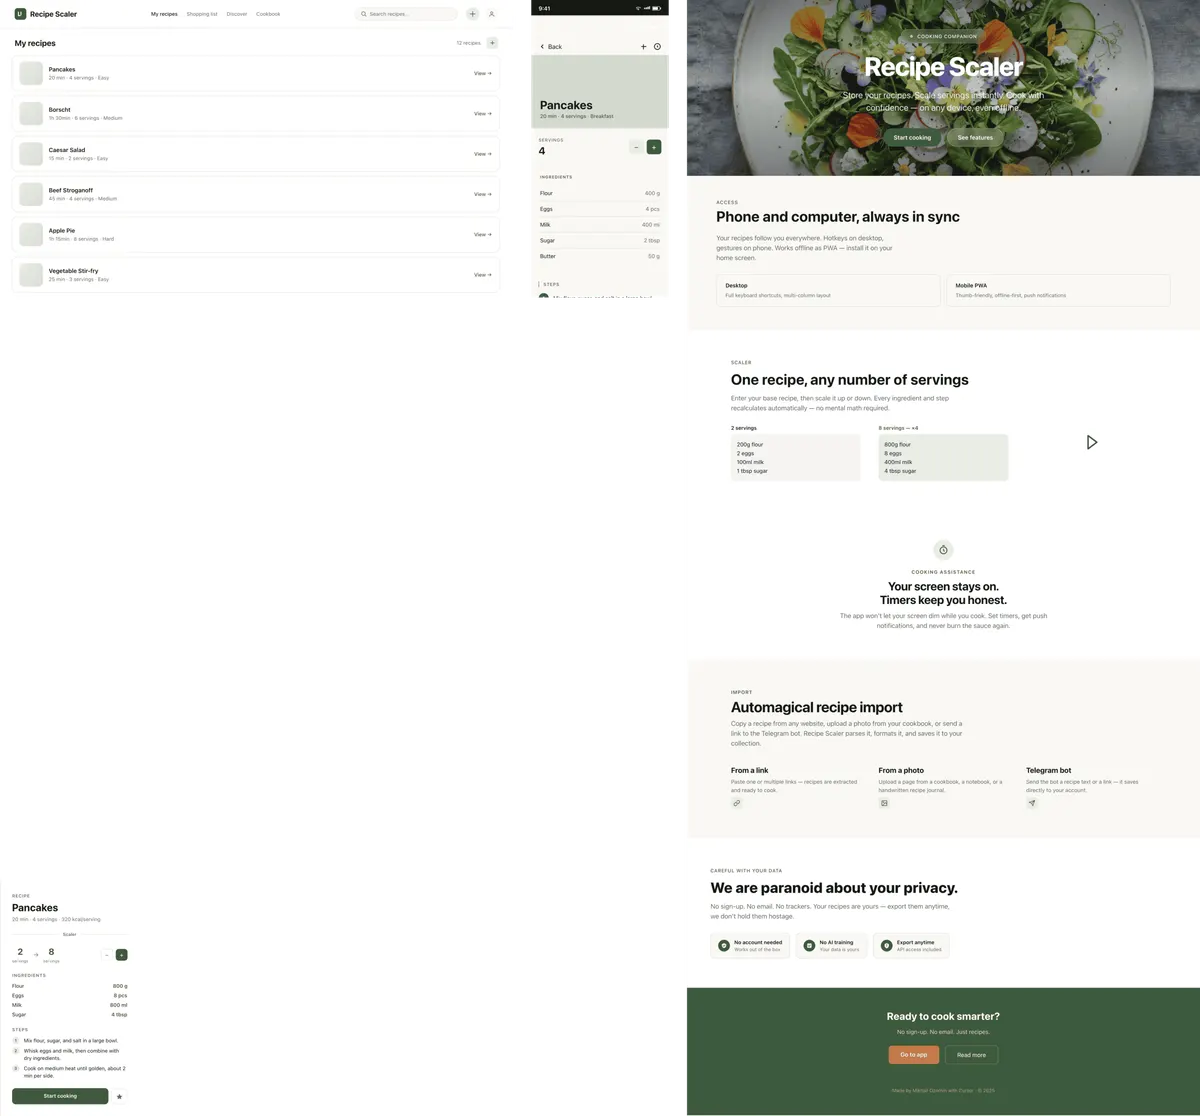
All bad, failed with the tools. Tokens may be counted without cache — unclear.
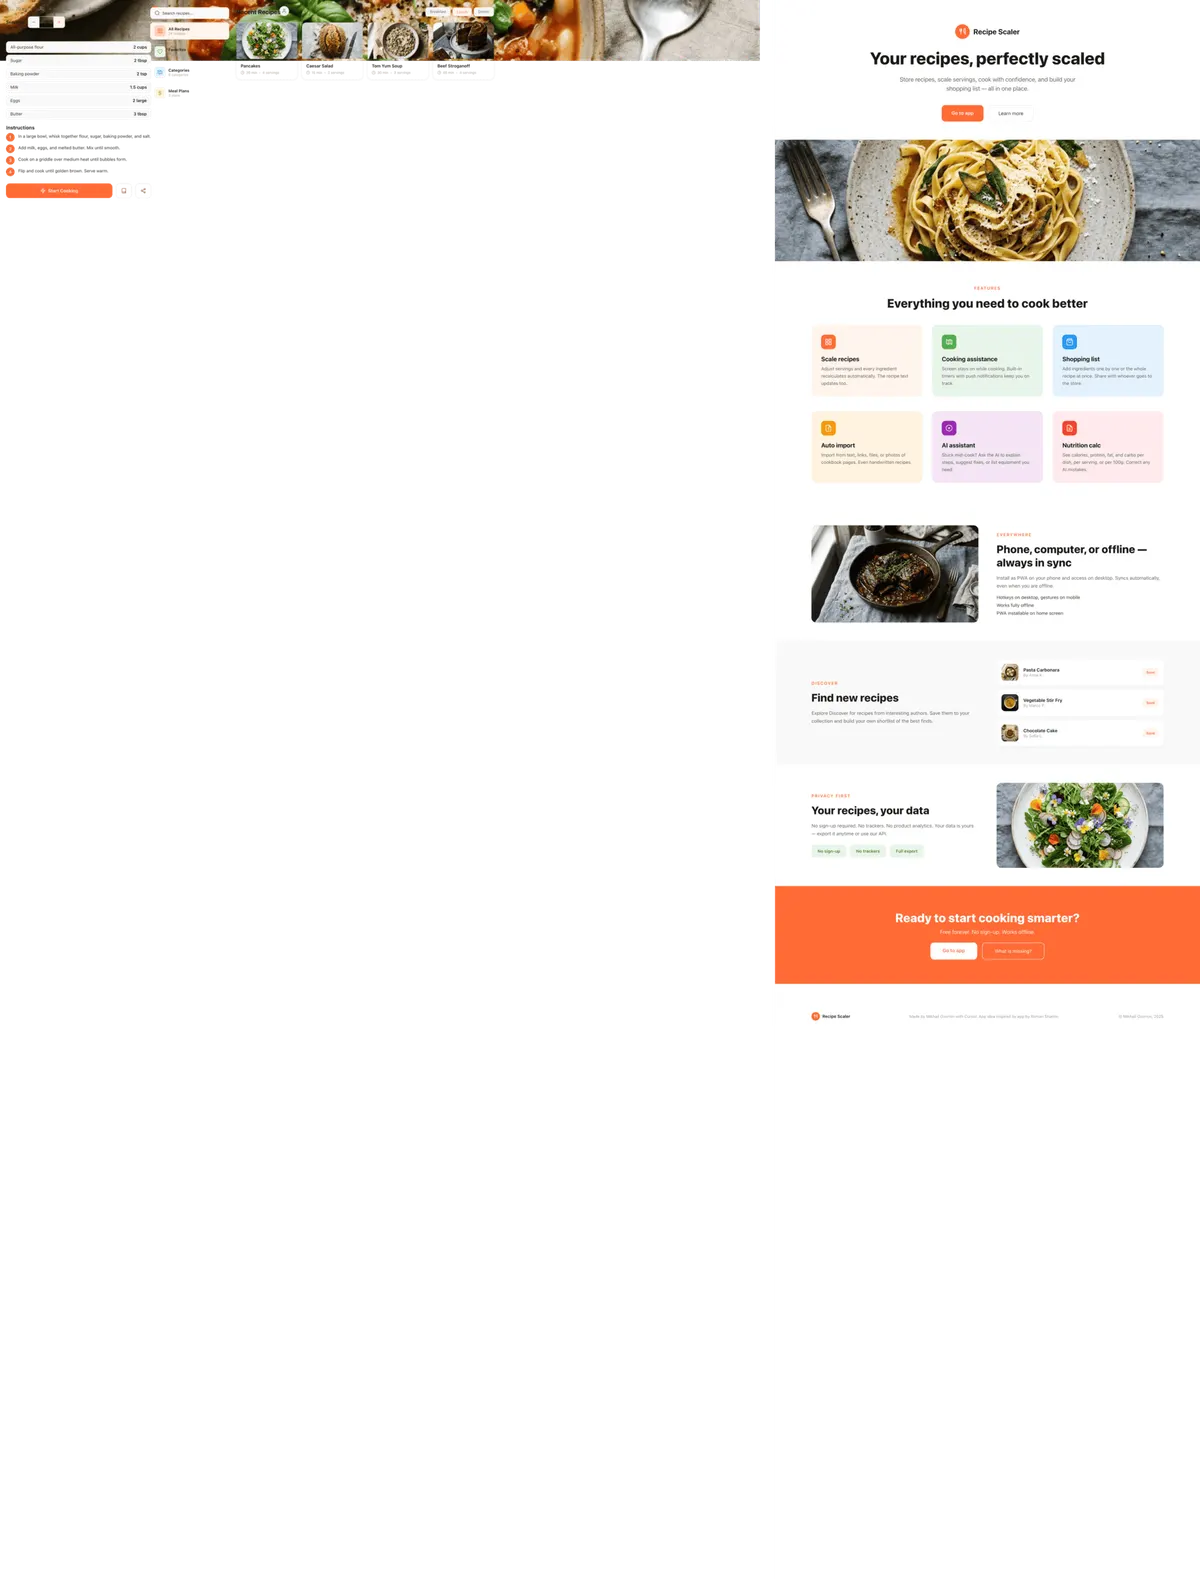
Bad, failed at everything. Tokens are likely reported without cache — can't be that low.